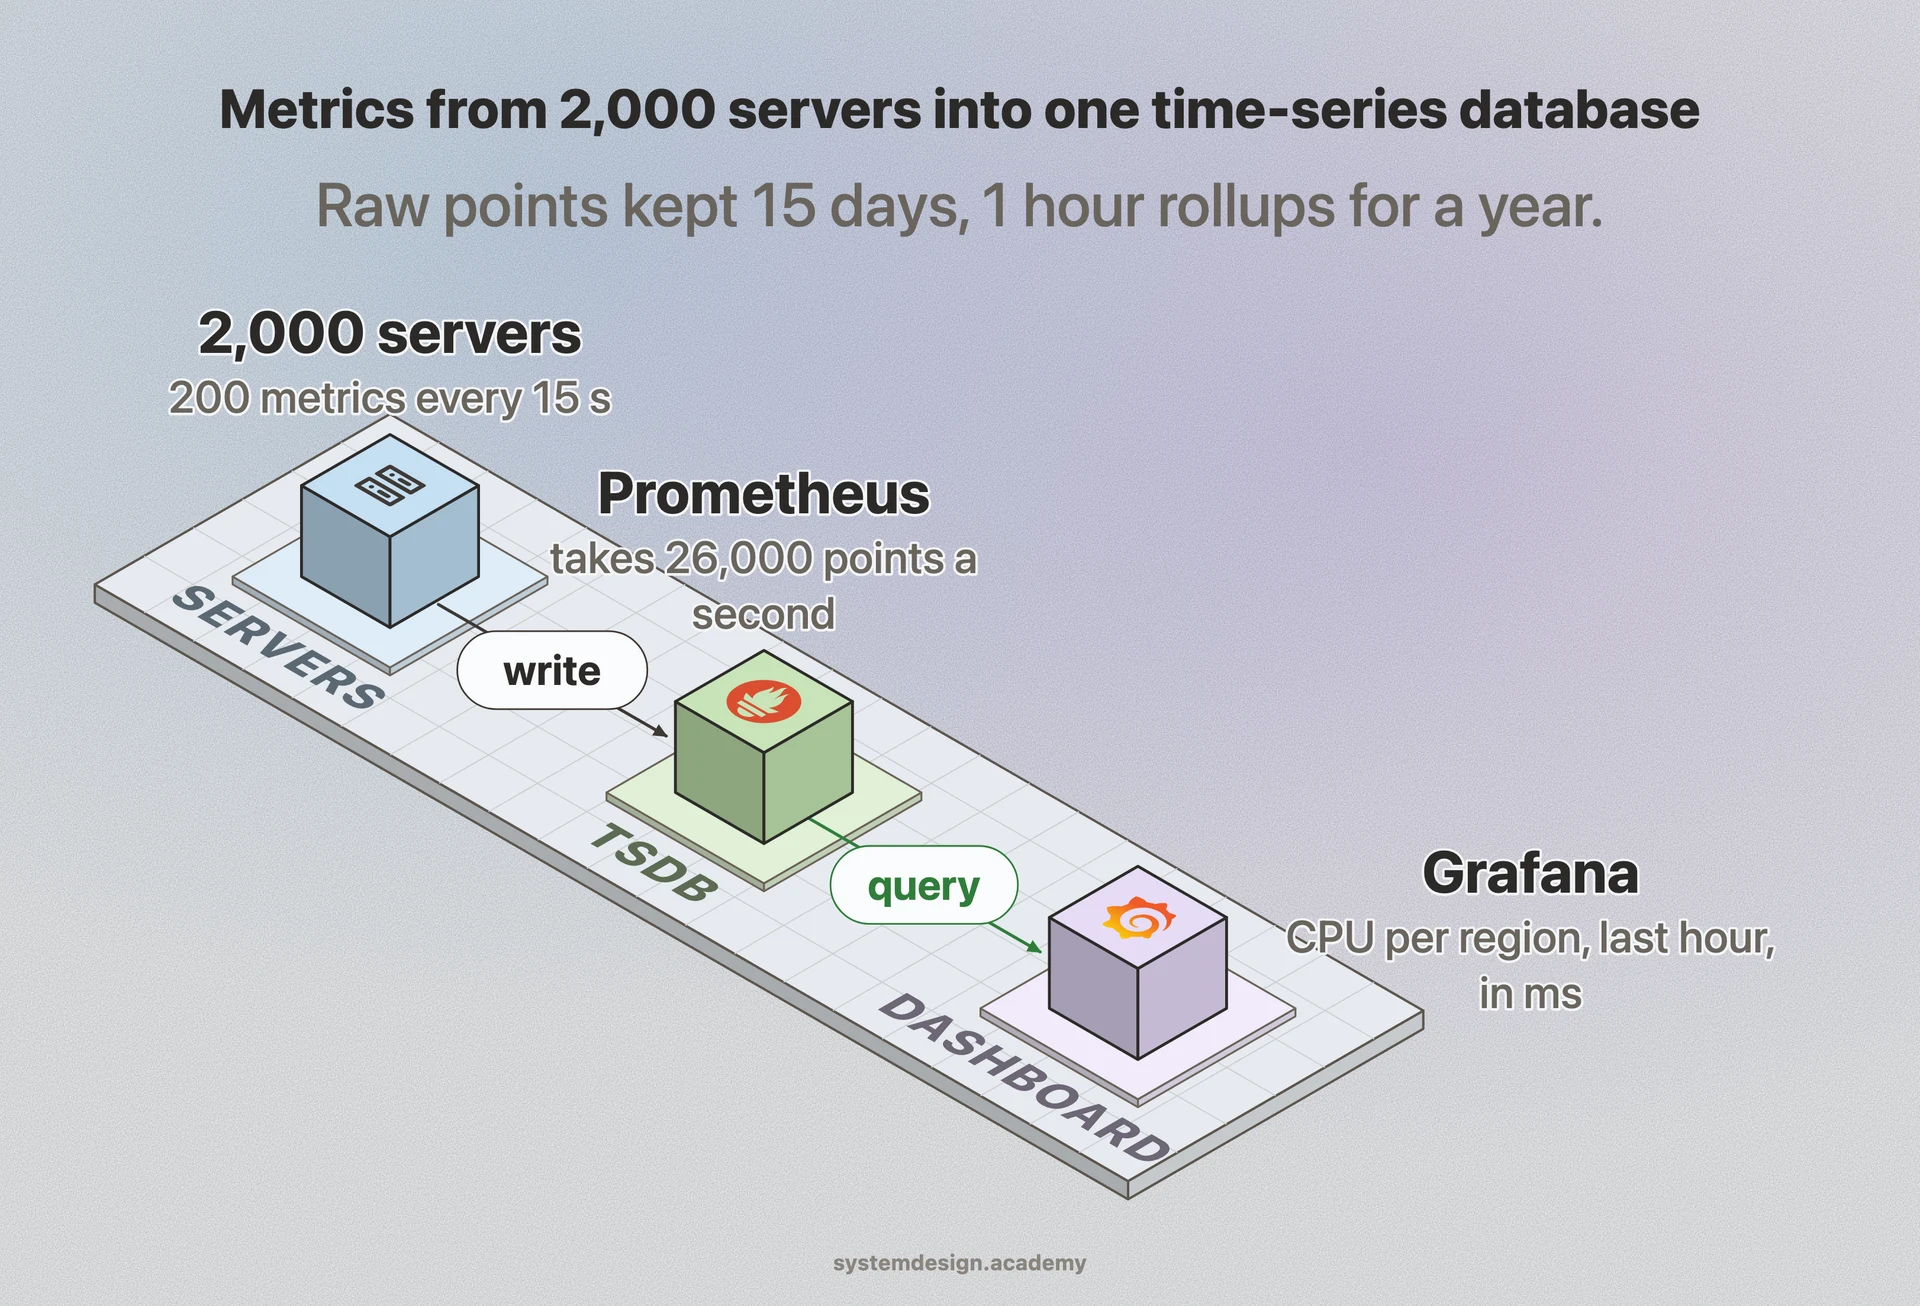
Reach for a TSDB when your data is naturally a stream of timestamped measurements and your queries are time-bounded: infrastructure monitoring, application metrics, IoT and sensor telemetry, financial ticks, event analytics, and real-time dashboards. The payoff is high ingest throughput, strong compression, and built-in time functions like rate, moving average, and bucketed aggregation.
The trade-offs are real. A TSDB is not a general purpose store. Updating or deleting individual points is slow or unsupported. High-cardinality labels (for example, a unique user id attached to every metric) can blow up the index and memory use, which is the single most common way teams break Prometheus and InfluxDB. Joins across unrelated datasets are weak compared to a relational database.
A useful middle path is TimescaleDB, which runs inside PostgreSQL. You keep full SQL, joins, and your existing tooling, and the extension transparently partitions tables into time-based chunks for TSDB-style performance. If you already run Postgres, that often beats adopting a separate system.