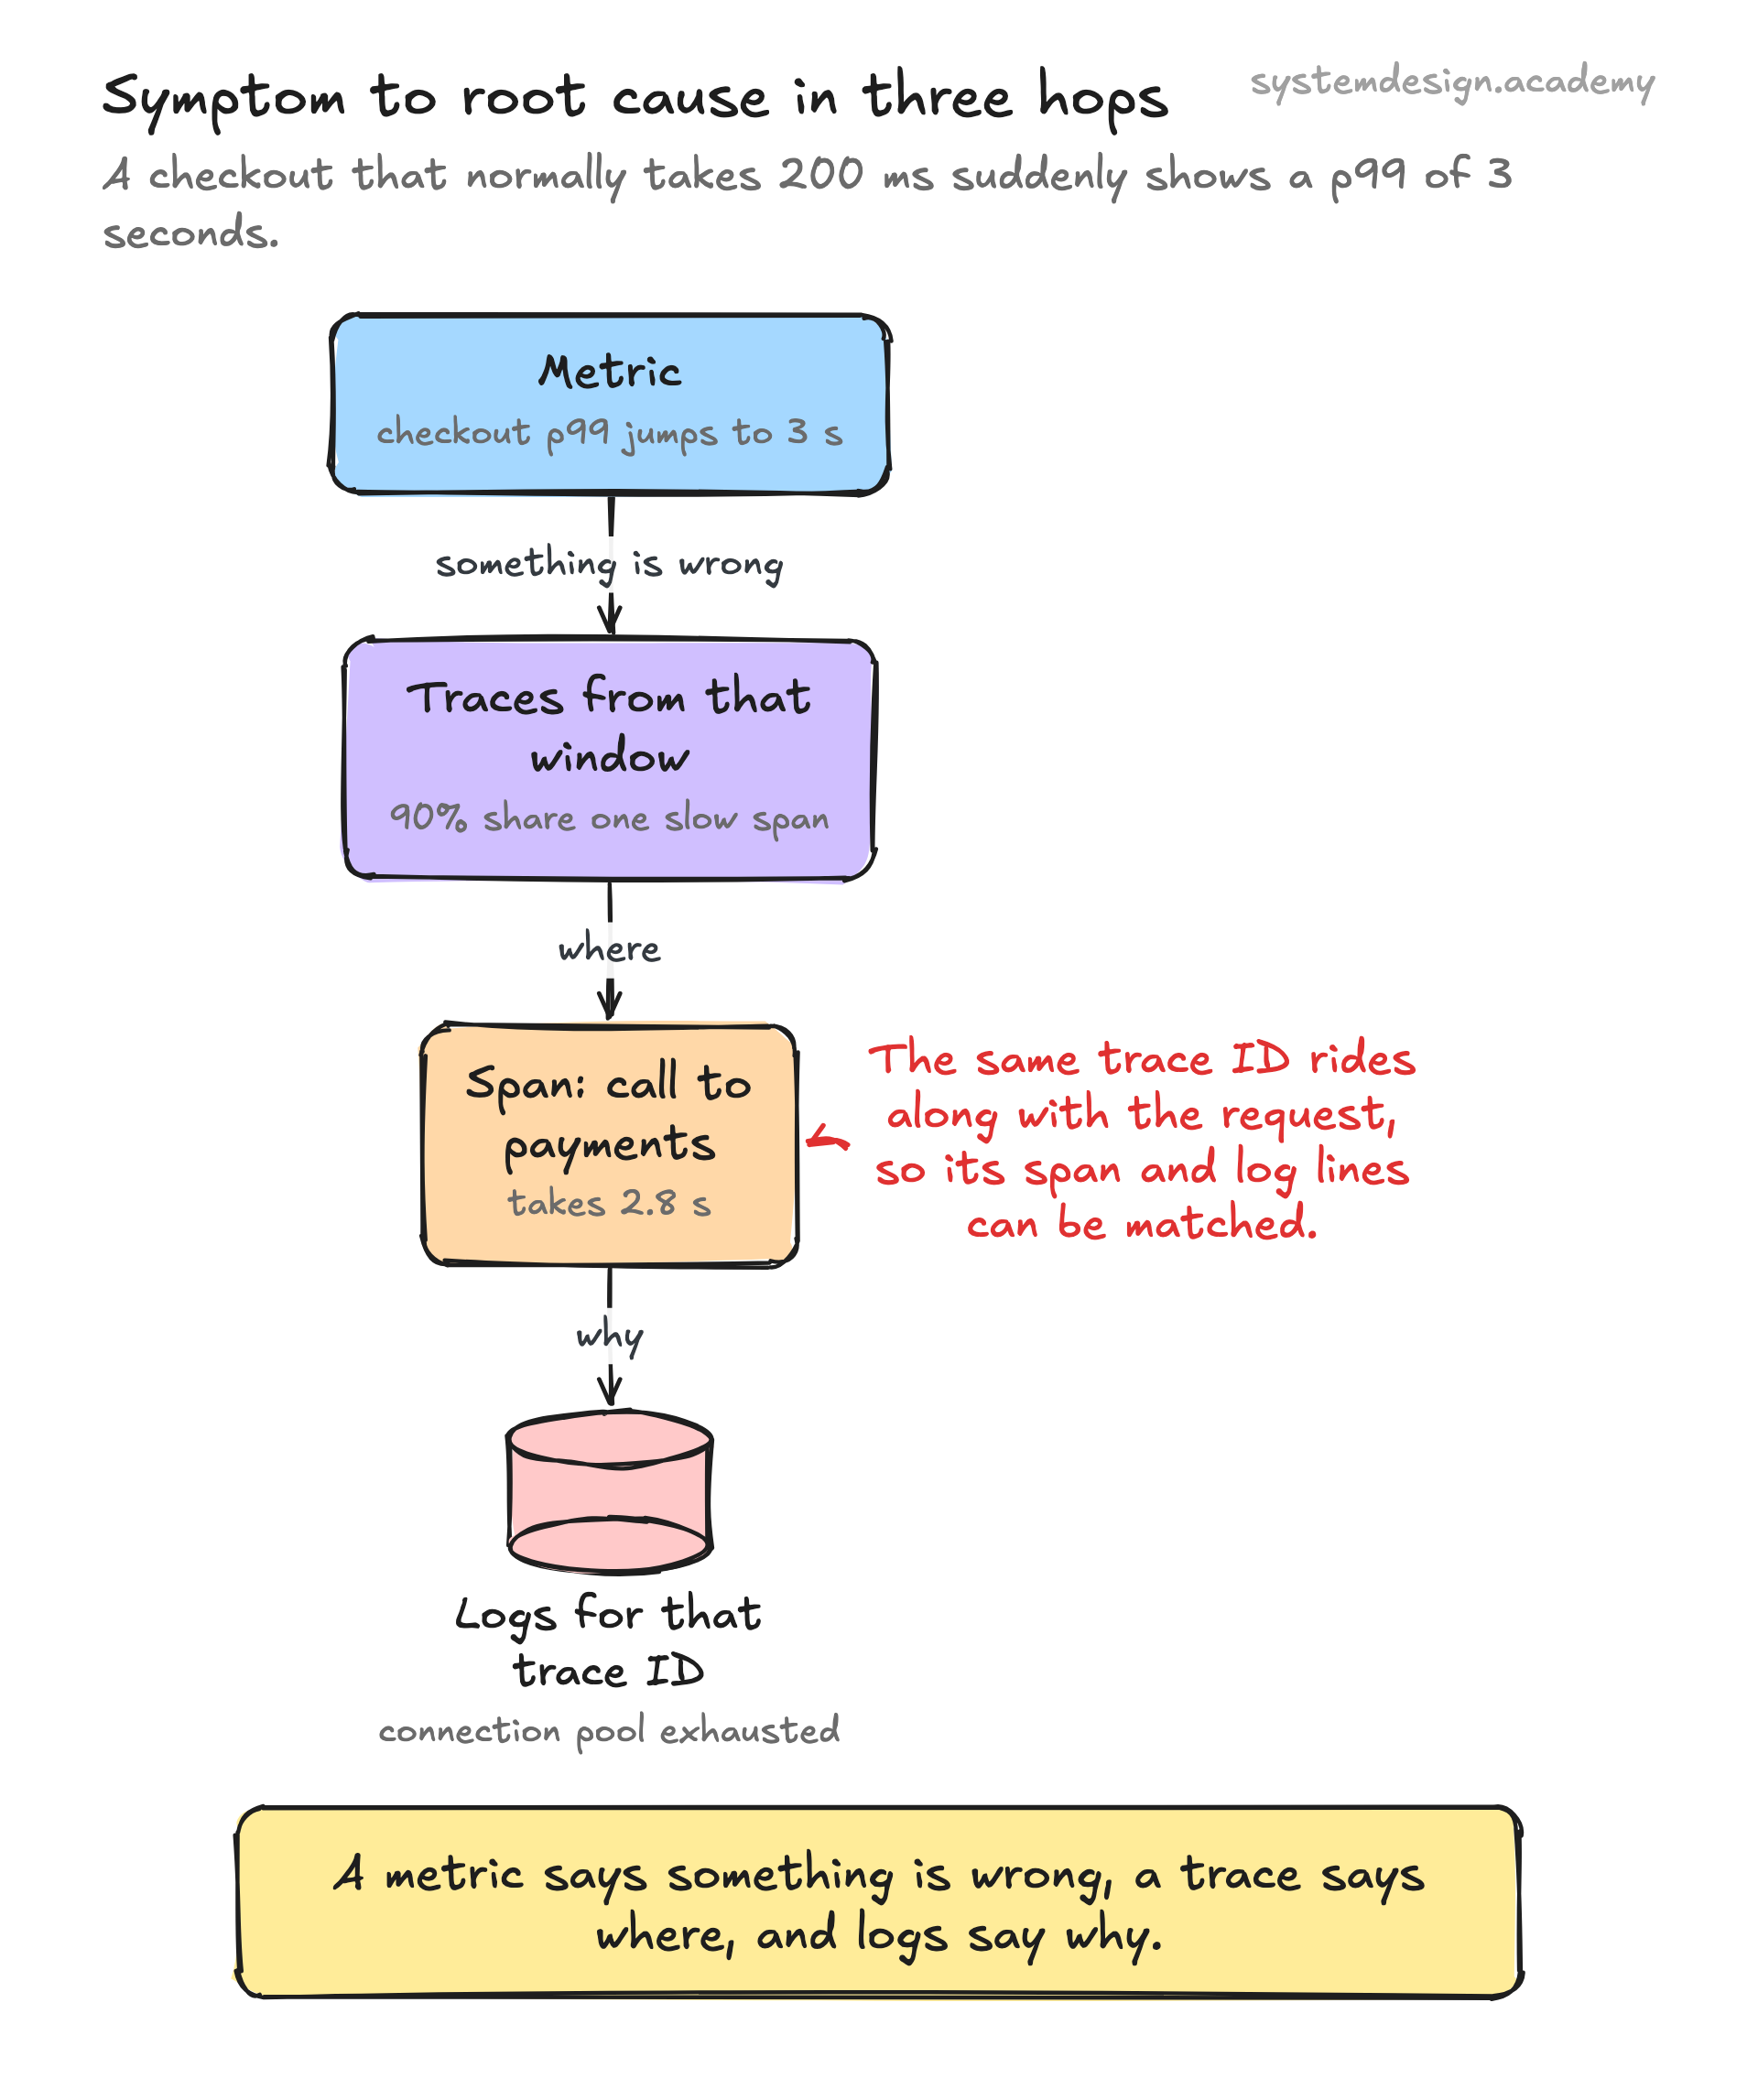
Metrics are numeric measurements aggregated over time, like request count, p99 latency, or queue depth. They are cheap to store because they are just numbers in time buckets, so you can keep months of them and run fast queries and alerts. The cost is that they lose detail: a counter tells you 500 errors happened, not which user or which request caused them.
Logs are discrete, timestamped records of events, ideally structured as key value pairs (JSON) rather than free text so machines can search and group them. They carry rich context per event but are expensive at volume, which is why high traffic systems sample or rate limit them. A single Google or Netflix scale service can produce terabytes of logs per day.
Traces follow one request as it hops across services. Each unit of work is a span, and spans are linked by a shared trace ID and parent span IDs so the full call tree can be reconstructed. A trace shows you that a 900ms checkout spent 600ms waiting on a downstream inventory call, which a metric alone would never reveal. The open standard for emitting all three is OpenTelemetry, which most vendors now ingest.
The glue is context propagation. A trace ID and request attributes are carried through HTTP headers and message metadata so that the metric, the log line, and the span for the same request can be correlated after the fact.