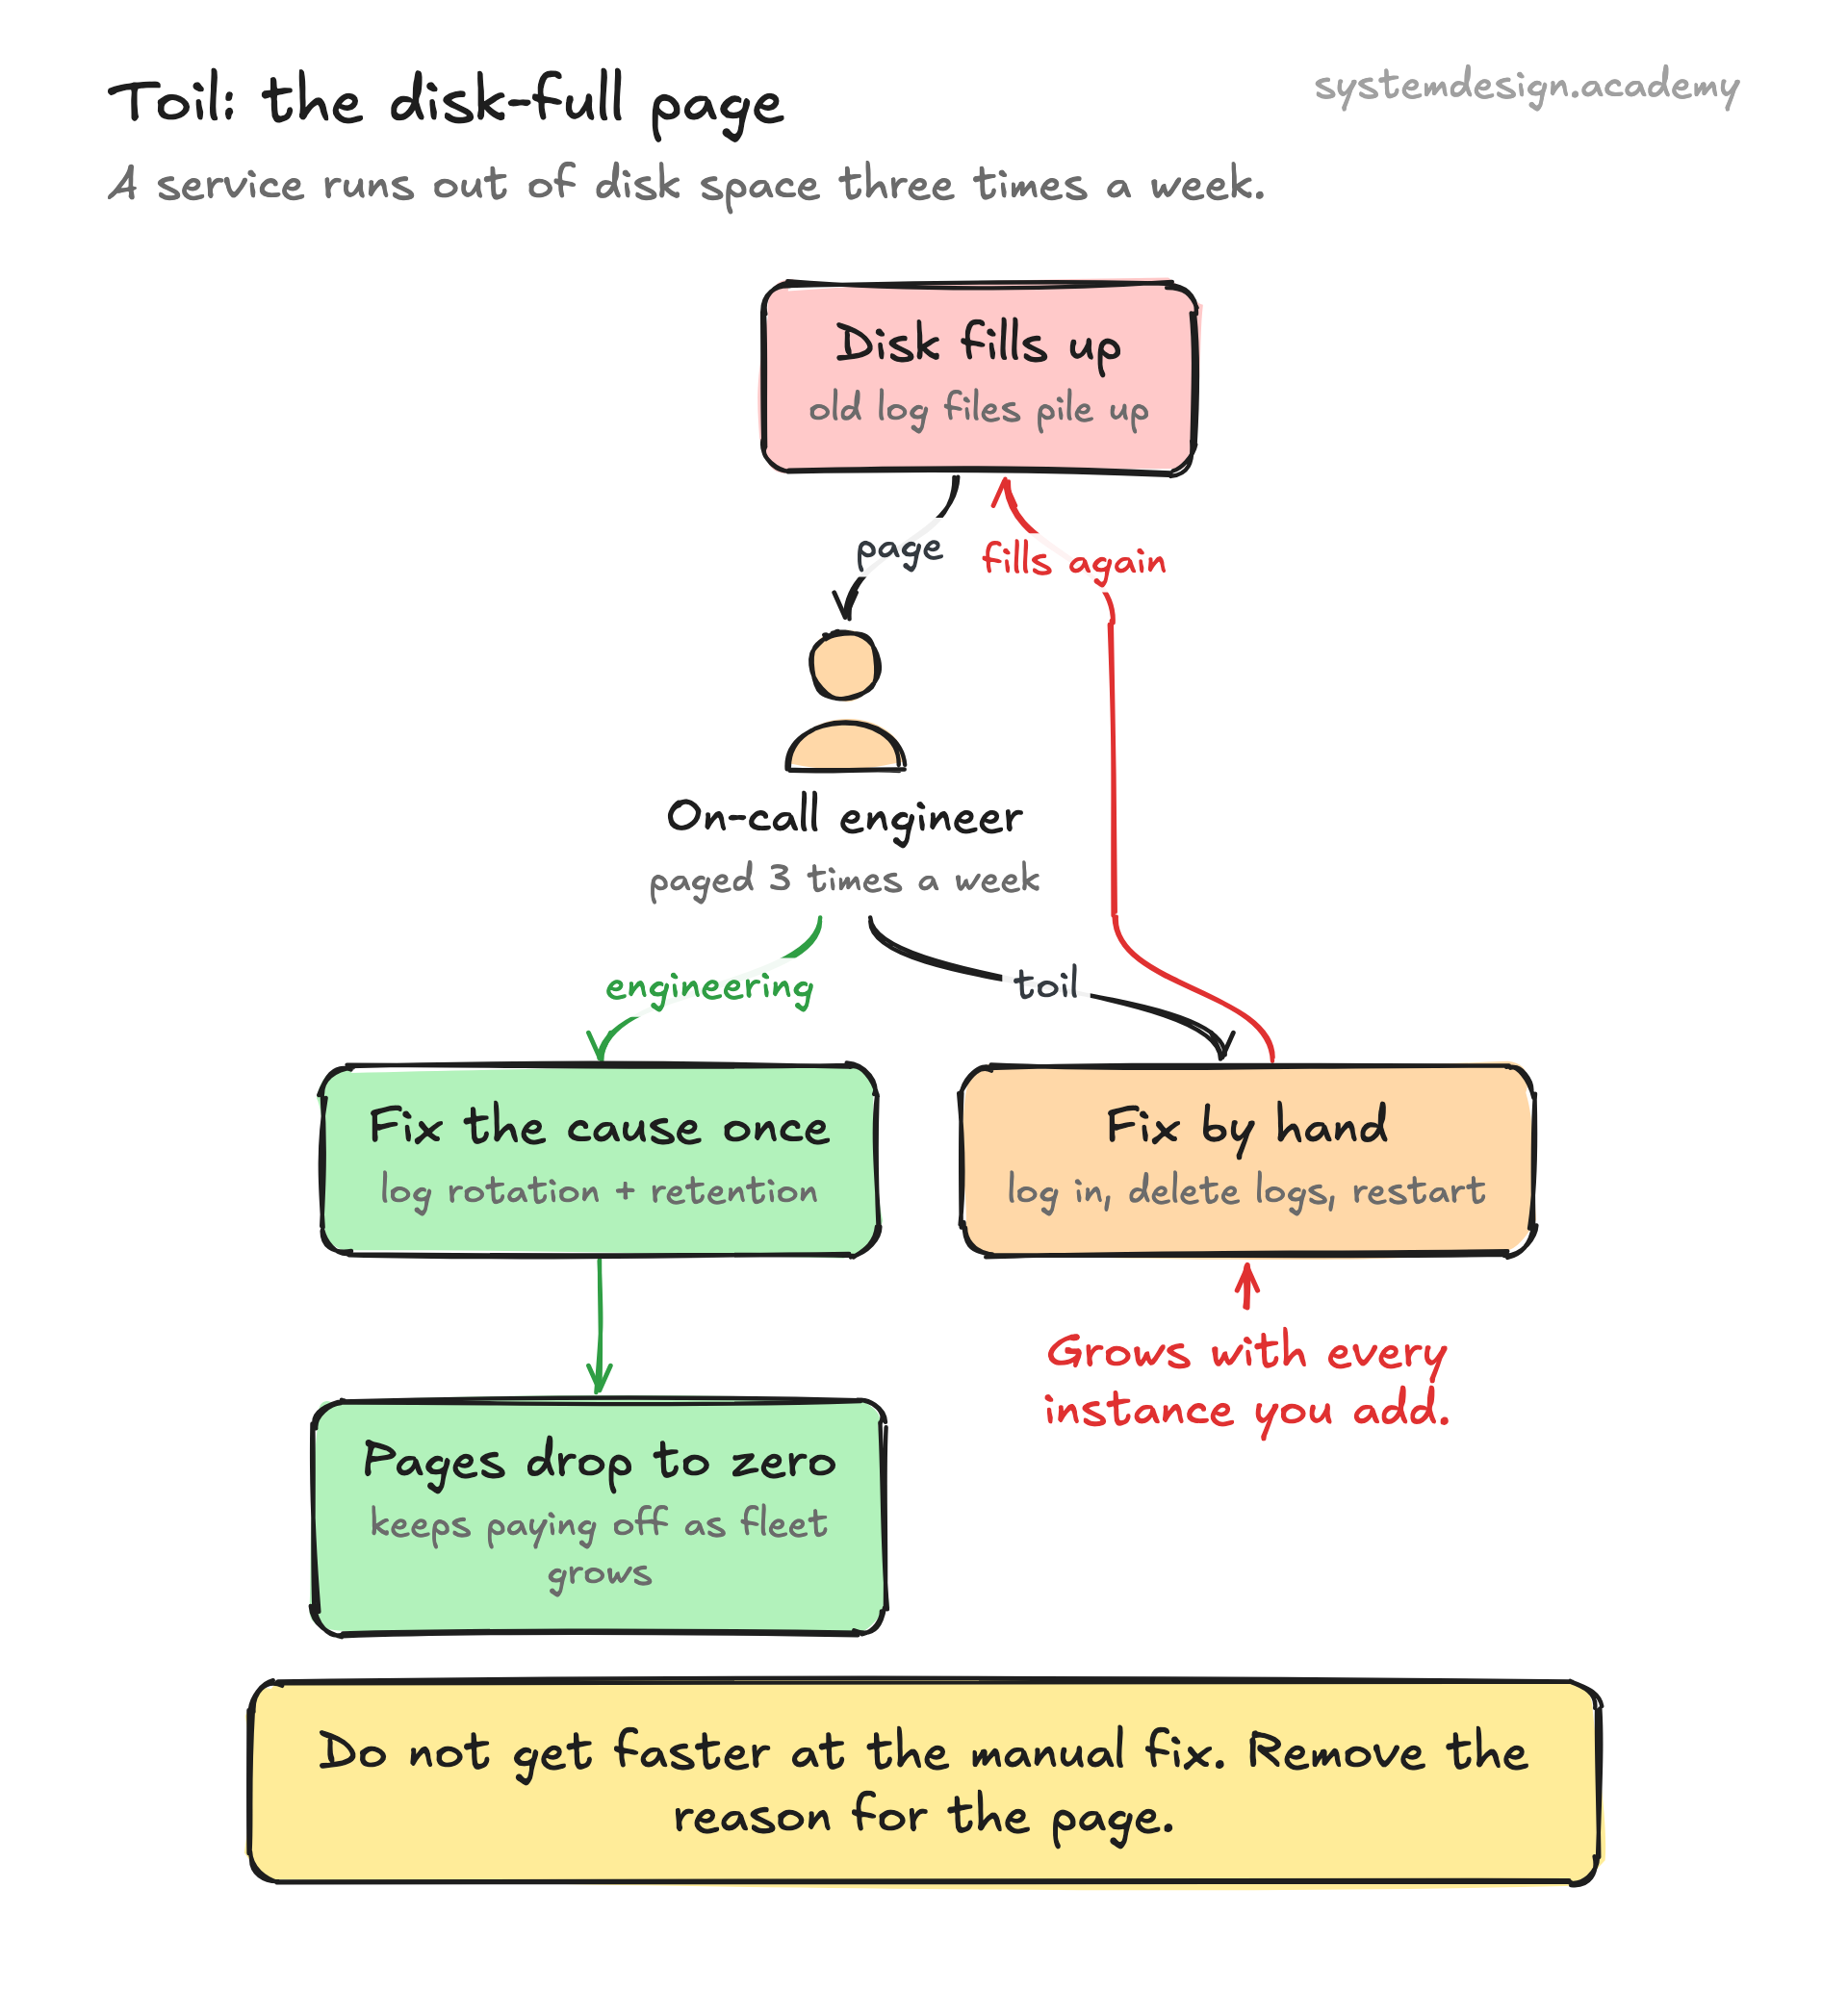
Toil is the grunt work of keeping a service alive. The classic definition from Google's Site Reliability Engineering book lists specific traits: the work is manual, repetitive, automatable, reactive rather than proactive, has no enduring value, and grows in proportion to traffic or service size. If a task hits most of those marks, it is toil.
Concrete examples are easy to spot once you know the shape. Manually restarting a stuck process every night. Approving the same quota request by hand ten times a week. Applying a config change across 200 servers one SSH session at a time. Acknowledging a pager alert, running a known fix, and closing the ticket, then doing it again tomorrow because nothing changed.
The important contrast is with overhead and with real engineering. Overhead is things like email, meetings, and expense reports, which are not tied to running a service. Engineering work produces something permanent: a script, a feature, a self-healing system that makes the toil go away for good. Toil sits in between, and the danger is that it quietly fills your day while leaving nothing behind.