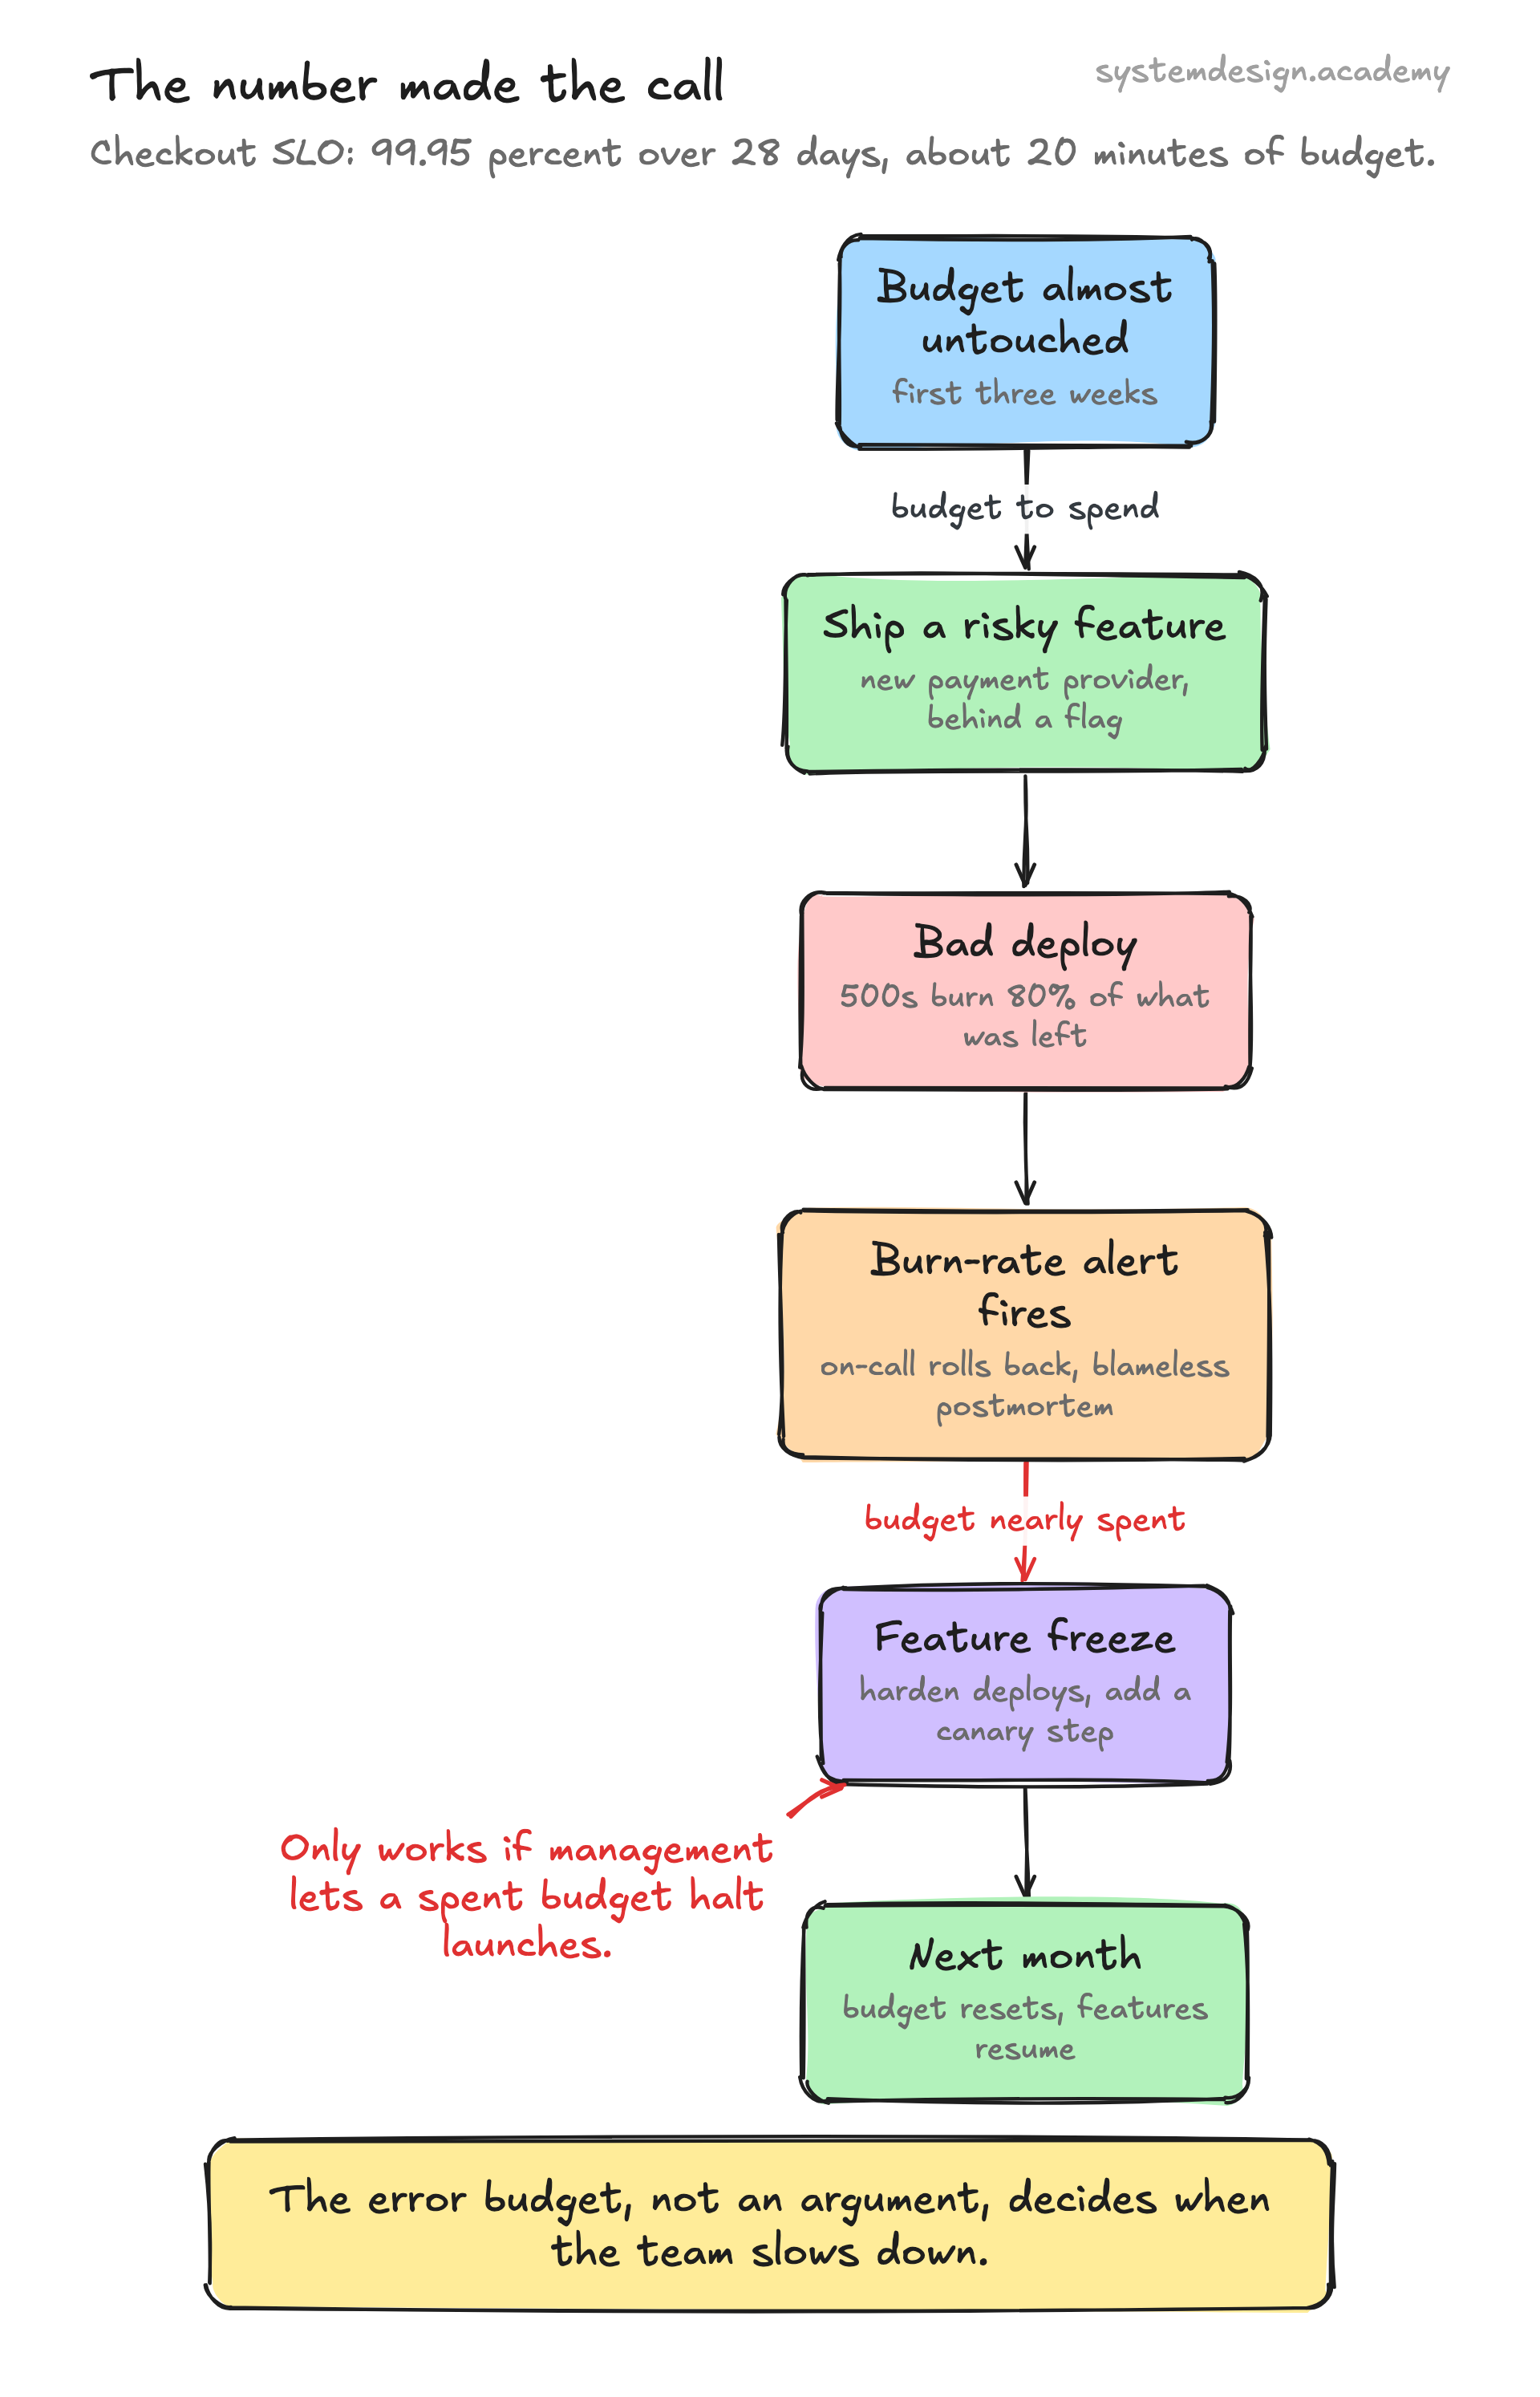
The center of SRE is the Service Level Objective (SLO). An SLO is a number you commit to, such as 99.9 percent of requests succeed in under 300 ms, measured over 28 days. It is built from Service Level Indicators (SLIs), which are the raw measurements like success rate and latency. The SLO is what the business and the engineers agree is good enough.
Once you have an SLO, you get an error budget for free. If the SLO is 99.9 percent, the budget is the remaining 0.1 percent of allowed failure. Over a 30-day month that is about 43 minutes of downtime. The budget turns reliability into a currency. If the service is well inside its budget, the team can ship features fast and take risks. If the budget is spent, feature launches stop and everyone focuses on reliability until the budget refills. This kills the old fight between developers who want to ship and ops who want stability, because the number decides.
The other pillar is fighting toil. Toil is manual, repetitive operational work that scales linearly with traffic and produces no lasting value, like restarting a stuck server by hand or running the same deploy steps every release. Google's published guideline is that SREs should spend no more than 50 percent of their time on toil, with the rest going to engineering that reduces future toil. The team also runs blameless postmortems after incidents, focusing on the system that allowed the failure rather than punishing a person.