systemdesign.academyAI EngineeringFree lessonsSign inGet the course
  1. Home
  2. AI Engineering: Data, RAG and Agents
Previous lessonThe RAG Scale Cliff: What Breaks Between 100 and 5 Million DocumentsNext lessonReranking: The Highest-Return Change in Your RAG Stack

System Design

  • Foundation
  • Intermediate
  • Advanced
  • Capstone

AI Engineering

  • Foundation
  • Data, RAG and Agents
  • Evaluation, LLM Ops and Security

systemdesign.academy

  • Home
  • Glossary
  • Interview prep
  • Reviews
  • About
  • Pricing
  • Privacy
  • Terms
  • Refunds
  • Delivery
  • Contact
  • Retrieval and RAG in Production
  • Chunking: The First Lever on Retrieval Quality
  • AI Engineering · Retrieval Rag

    Chunking: The First Lever on Retrieval Quality

    Free preview: the first part of this 11-part lesson.

    Already bought the course? Sign in to read the whole lesson.

    this lesson is part of

    AI Engineering

    Unlock this lesson and the 199 other paid lessons

    • 210 lessons in 16 chapters
    • 118 lessons built on a lab that really ran
    • An AI tutor beside every lesson that answers and draws
    • Lifetime access, every new lesson included

    $49 once, by PayPal

    See the AI Engineering course

    The rest of this lesson

    1. Why the Boundary Sets the Ceiling
    2. Two Ways to Get It Wrong, Pulling in Opposite Directions
    3. Overlap: Stop the Answer From Falling in the Seam
    4. Where to Cut: Fixed Size, Structure, or Meaning
    5. One Size Does Not Fit All Content
    6. The 512-and-50 Default Is a Starting Point, Not a Law
    7. Watch a Fact Fall in the Seam, Then Watch Overlap Save It
    8. Store More Than Text and a Vector on Every Chunk
    9. How Teams Handle This in Production
    10. Knowledge Check

    read the rest of this lesson in

    AI Engineering

    Unlock this lesson and the 199 other paid lessons

    • 210 lessons in 16 chapters
    • 118 lessons built on a lab that really ran
    • An AI tutor beside every lesson that answers and draws
    • Lifetime access, every new lesson included

    $49 once, by PayPal

    See the AI Engineering course

    Continue this lesson

    in Retrieval Rag

    This lesson is part of the AI Engineering course. Unlock the full course, a separate one-time payment, for lifetime access.

    One-time payment. Lifetime access. No subscription.
    Global
    $49/lifetime

    One-time payment via PayPal

    Get Lifetime Access
    Foundation lessons free, try before you buy
    India Special
    India
    ₹999/lifetime

    One-time payment: UPI, card or netbanking

    Get Lifetime Access
    Foundation lessons free, try before you buy
    Every ML Platform lesson, Foundation to Advanced
    Real architecture diagrams with real tool logos
    MLOps, LLMOps, and data engineering in depth
    Quizzes with instant feedback
    Built and reviewed by senior engineers
    Lifetime access, all future content included

    Foundation lessons of this course are free, no payment needed. Try them now

    The Answer Was in the Document. Retrieval Could Not Return It.

    Here is a failure that feels impossible the first time you meet it. A user asks a assistant a question the docs plainly answer, what is the maximum file size an upload accepts, and the assistant says it does not know. The sentence with the answer is right there in the upload guide, one clear line. Retrieval never brought it back, so the model never saw it, so it could not answer. Nothing was broken and no error was thrown. The fact simply fell on the wrong side of a chunk boundary.

    They spend a day suspecting the model. They try a bigger one. Same result. They add a reranker to reorder the retrieved results. Same result. Nothing helps, because none of those things touch the actual problem. The sentence with the file-size limit had been cut in half when the document was chopped into pieces for the index. Half of it landed at the end of one chunk and half at the start of the next. Neither piece, on its own, reads like an answer to the question, so neither piece got retrieved.
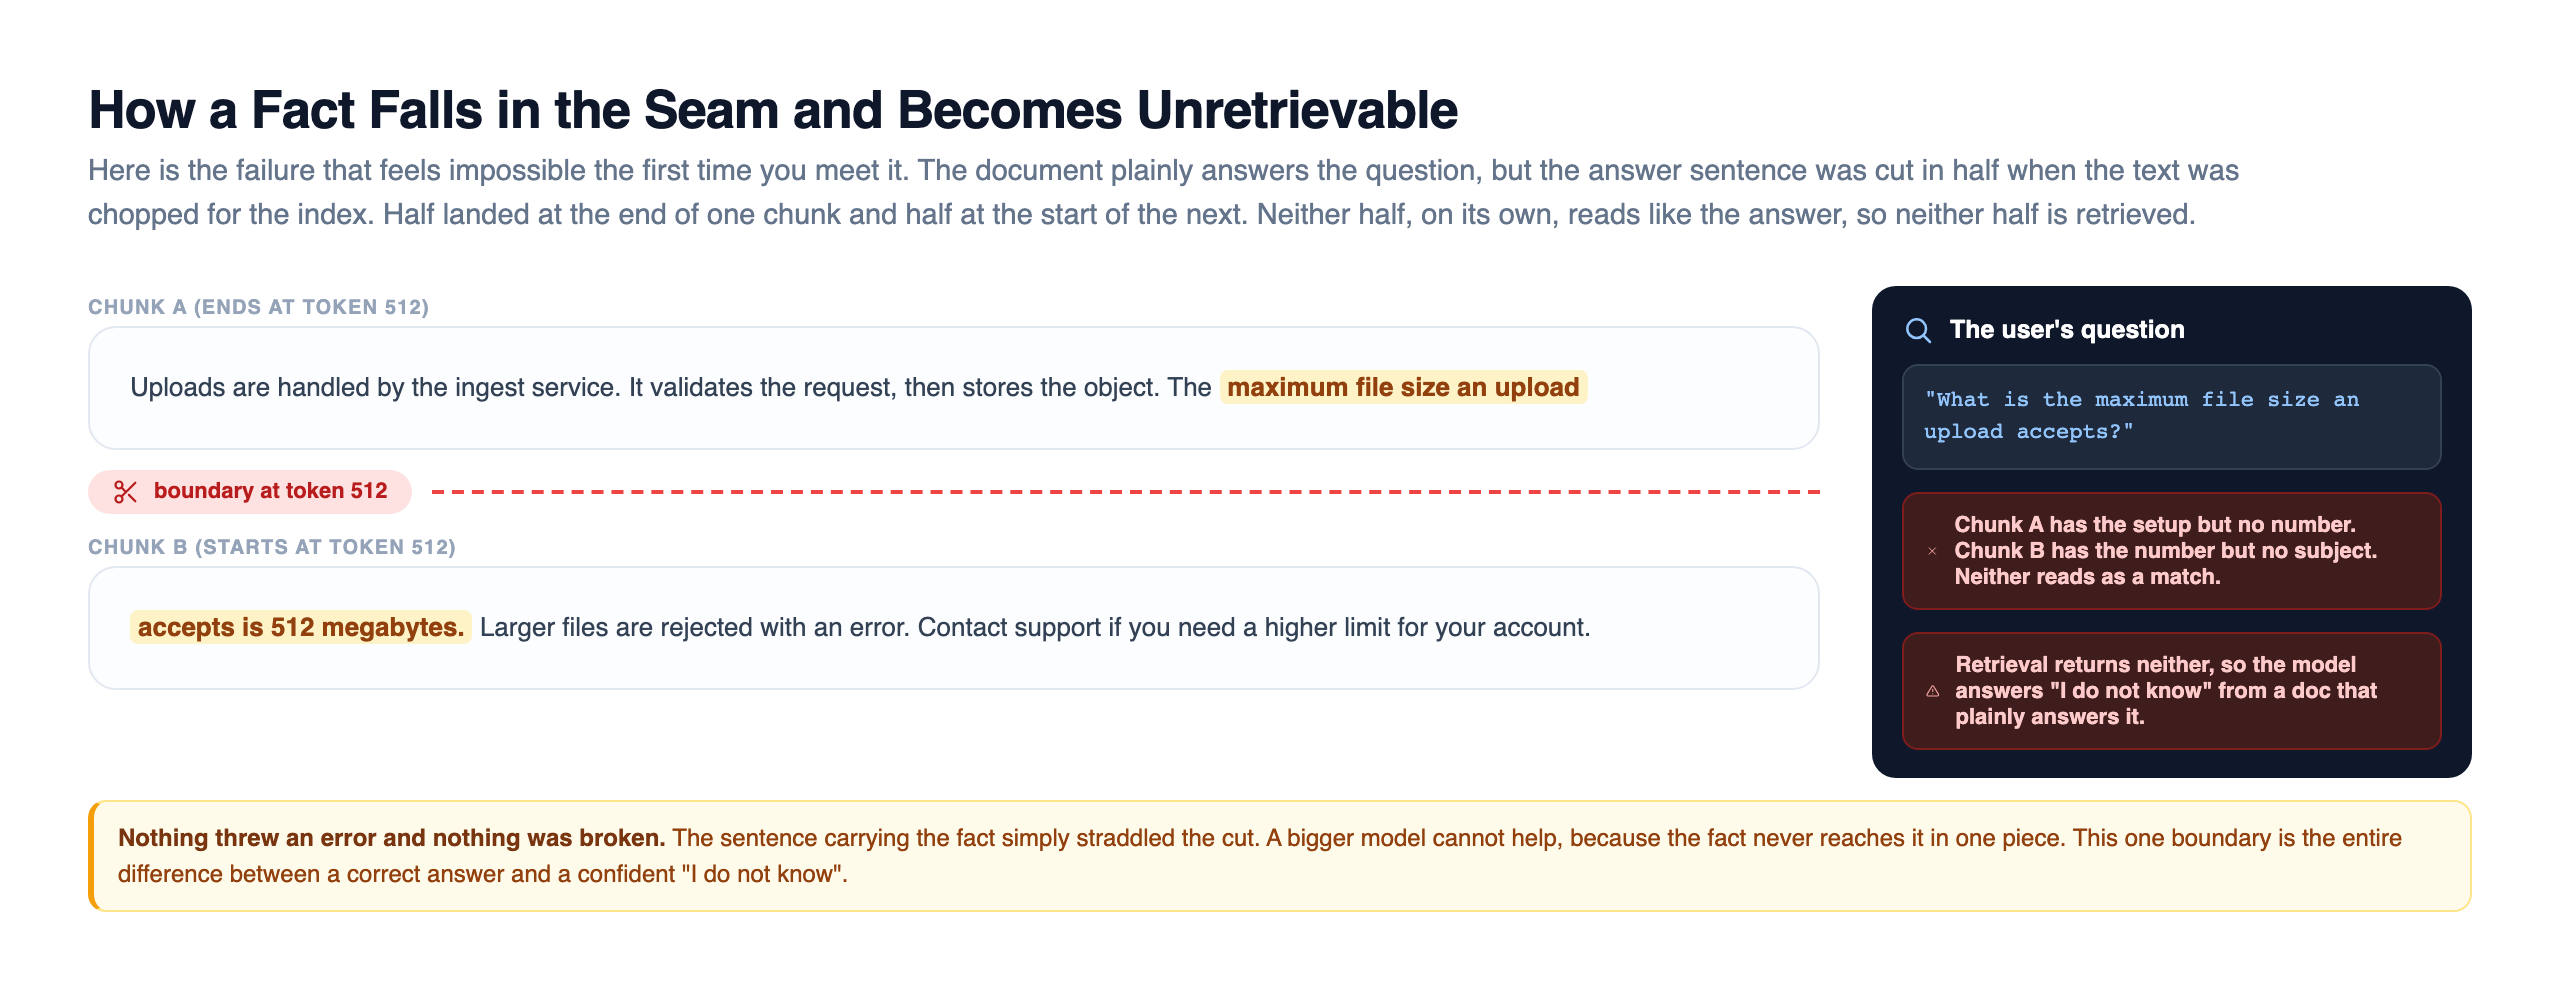
    How a fact falls in the seam: an annotated upload guide split at token 512, where the sentence stating the maximum file size an upload accepts is cut so its subject stays in chunk A and the number 512 megabytes lands in chunk B, with a side panel showing the user question and why neither half reads as a match so retrieval returns nothing and the model answers I do not know

    This is the part people skip past on their way to the model and the prompt. Retrieval can only ever hand the model text that lives inside a chunk. The chunk boundaries decide what text can be retrieved together, which means they decide the ceiling on how good any answer can be. Choose them badly and there is no reranker, no prompt trick, and no frontier model that can recover a fact the boundary already split apart.

    Chunking is unglamorous. It is also the first real lever you have on retrieval quality, and it is the one that quietly caps everything downstream. This lesson is about pulling it on purpose instead of by accident.