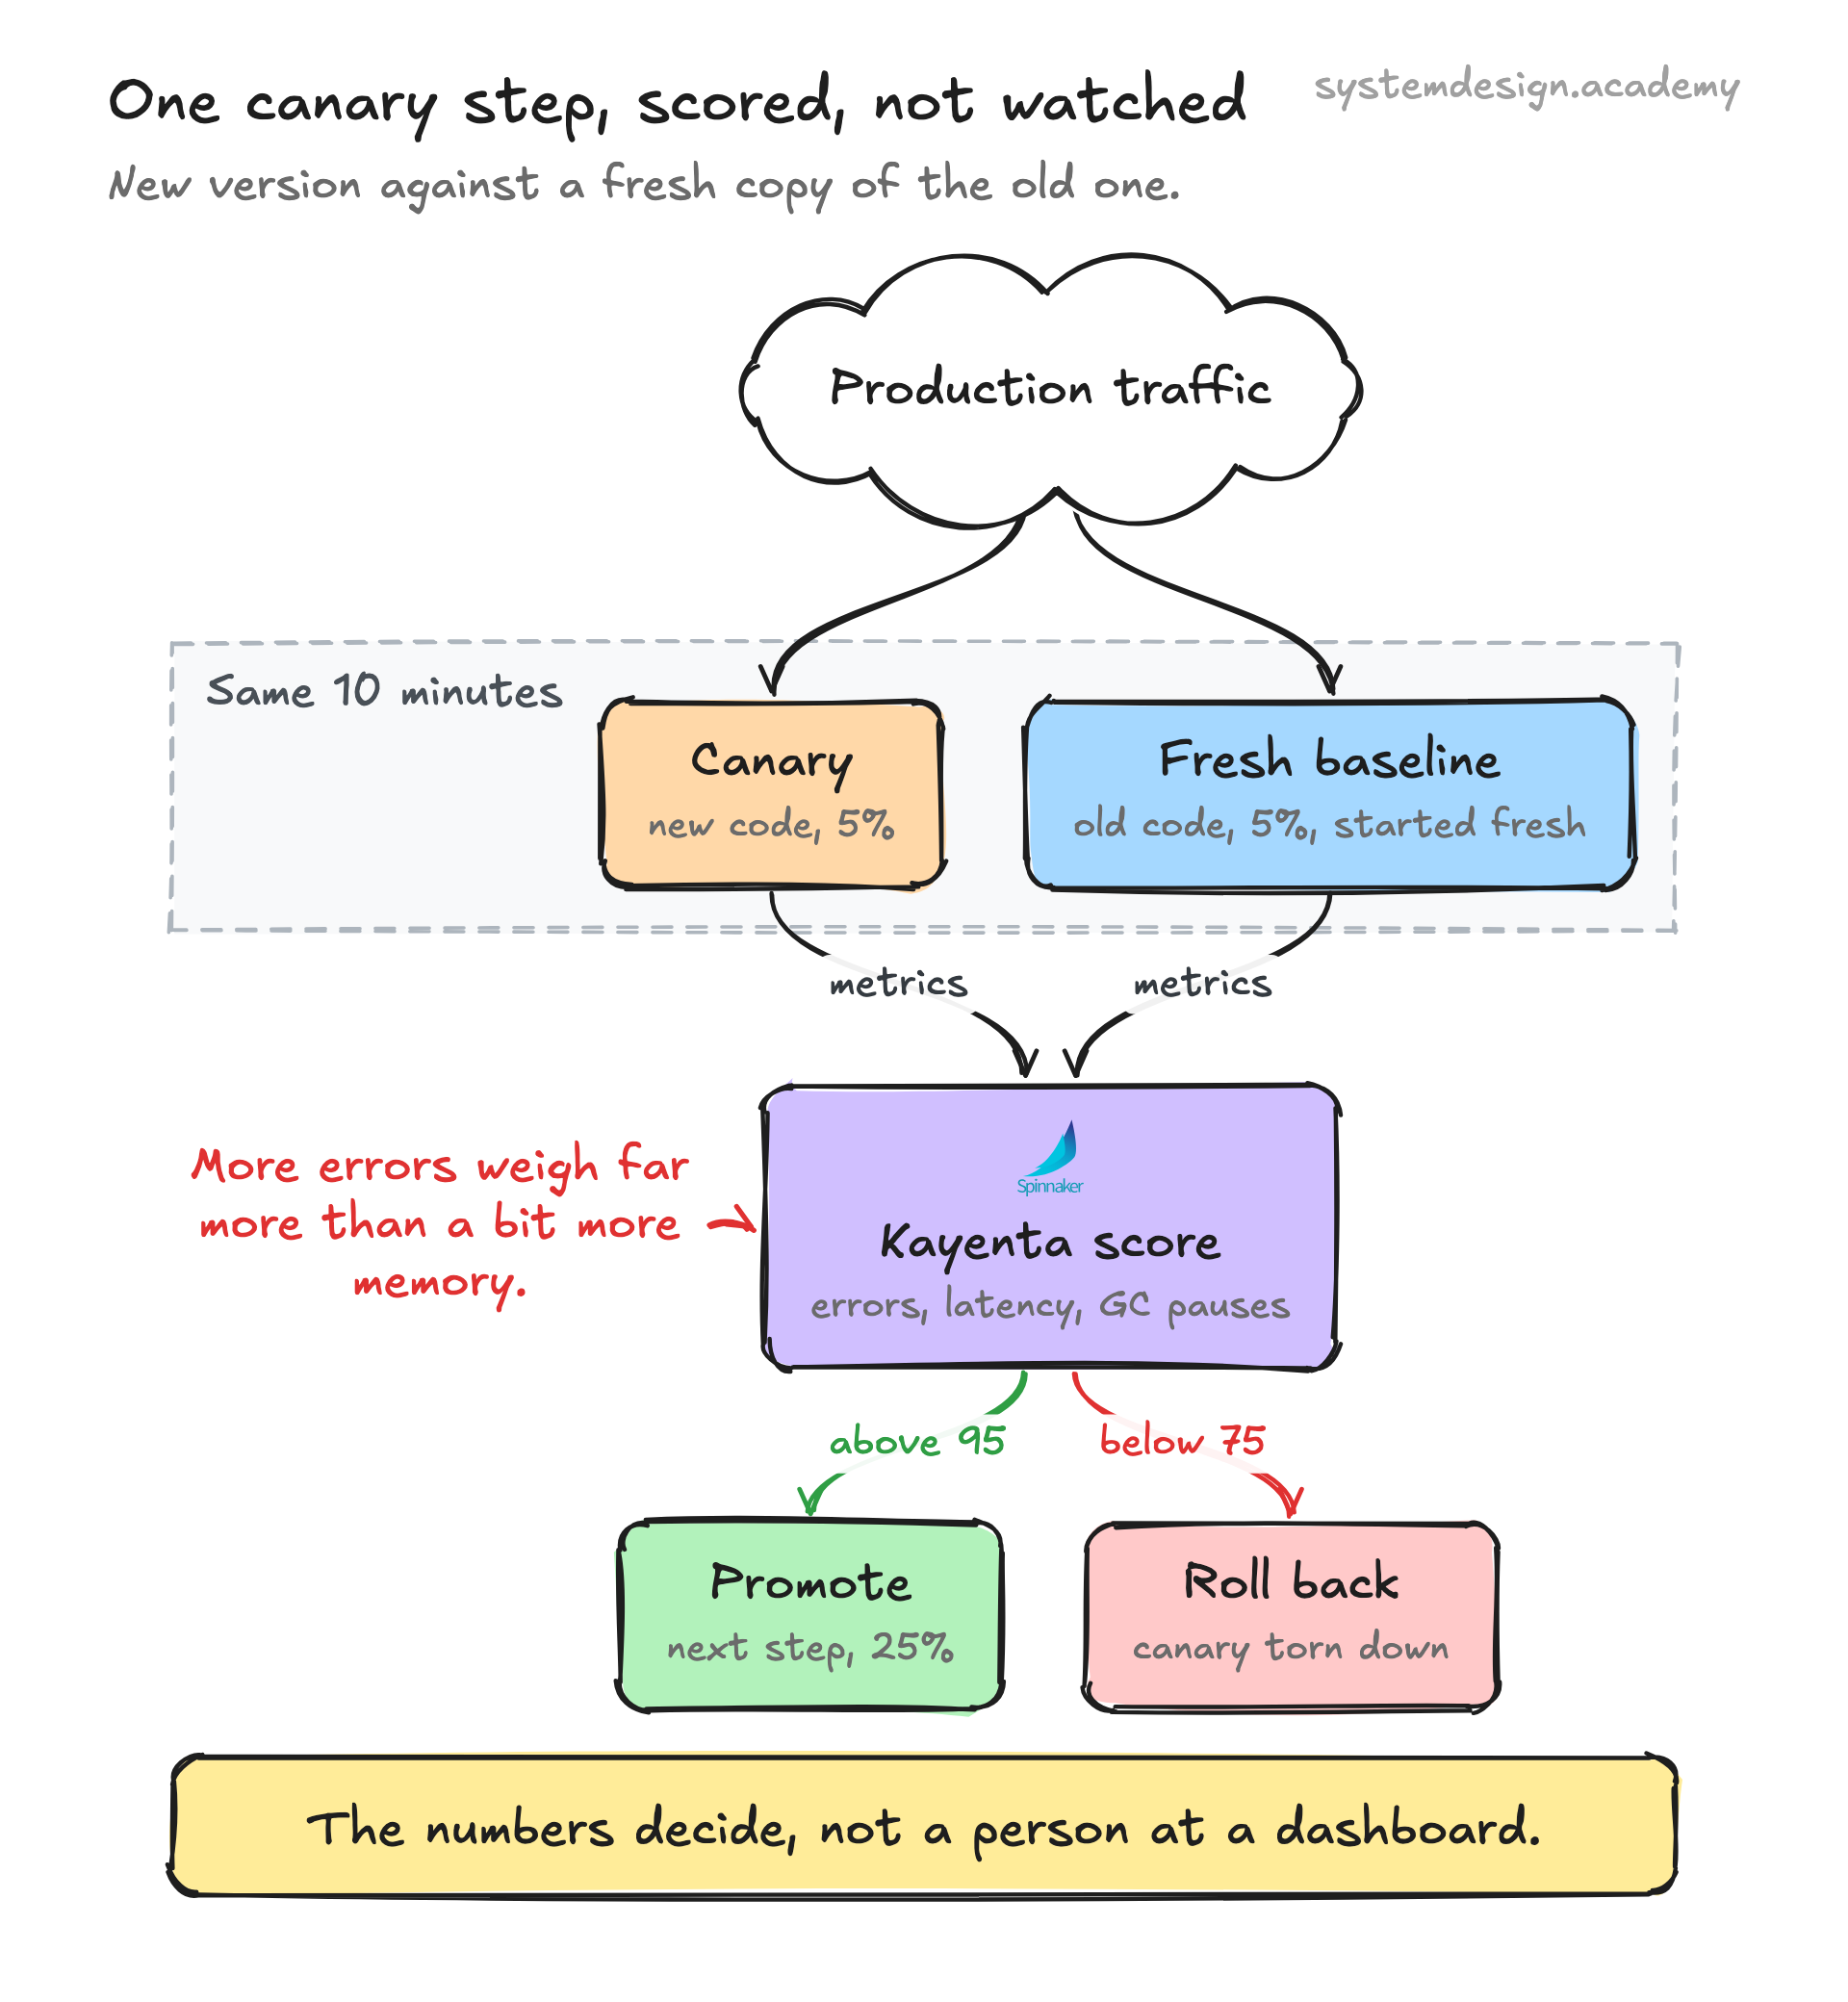
The core technique is comparing two populations of metrics over the same window of time. The canary and baseline receive comparable traffic, so any difference in their behavior should come from the code change, not from time-of-day load or a noisy neighbor. Tools collect metrics like HTTP 5xx rate, p99 latency, CPU, memory, and custom business signals from both, bucketed into intervals.
For each metric the system runs a statistical comparison. A common approach is the Mann-Whitney U test, a non-parametric test that asks whether the canary's distribution of samples is meaningfully worse than the baseline's, without assuming the data is normally distributed. Each metric gets a result of pass, high (canary is worse), or low, and metrics are weighted so a spike in error rate counts far more than a small jump in memory.
Those per-metric results roll up into an aggregate score, often 0 to 100. The pipeline applies thresholds: above, say, 95 the canary is promoted; below 75 it is rolled back; in between it may hold for more data. Many setups compare the canary against a fresh copy of the baseline (a second instance of the old version started at the same time) rather than the long-running production fleet, so both have the same warm-up state and cache behavior. This avoids false alarms from a cold canary losing to a warm baseline.
Runs happen in steps. A typical schedule sends 5 percent of traffic, analyzes for 10 minutes, then 25 percent, analyzes, then 50 percent, and finally 100 percent, with an automatic rollback at any failing step. Spinnaker with the Kayenta engine, Argo Rollouts, and Flagger all implement this loop on top of Kubernetes or cloud load balancers.