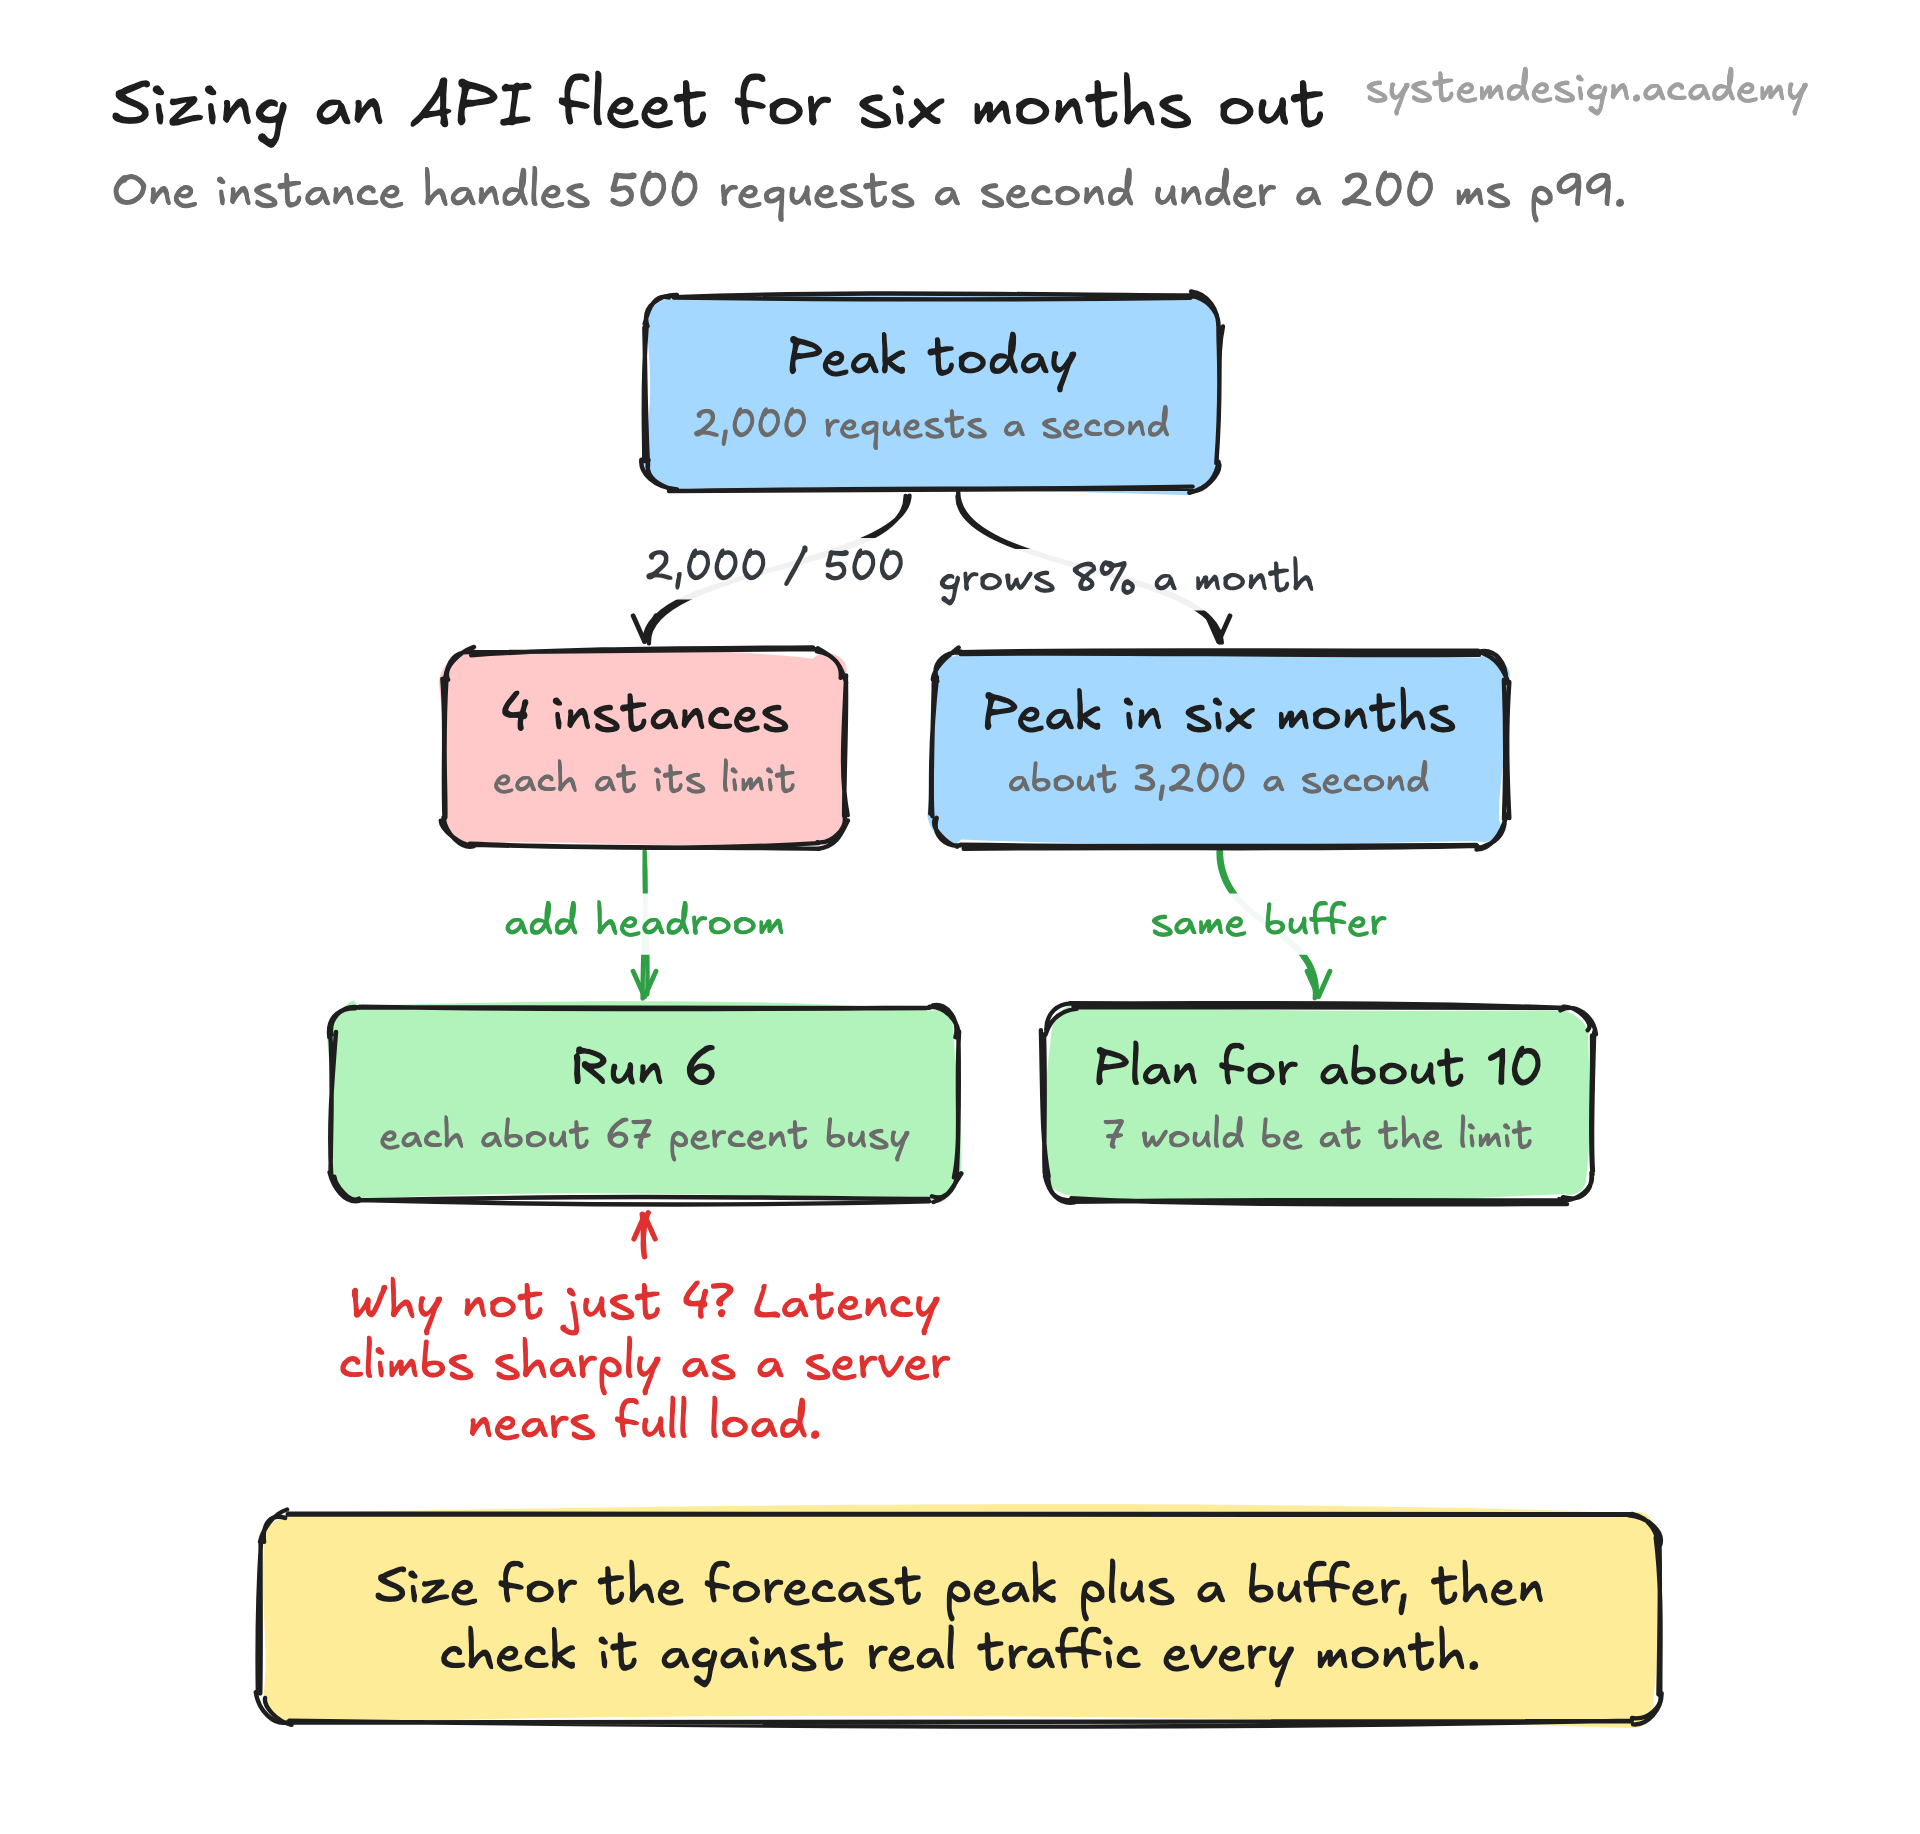
Every service has a ceiling. A database can take only so many writes per second, a web server can hold only so many open connections, a disk fills up. Capacity planning is the work of finding those ceilings, watching how fast you are approaching them, and adding headroom before you hit them. It turns a vague worry like "are we going to fall over during the sale?" into a number you can act on.
The output of capacity planning is concrete: an instance count, a database tier, a storage allocation, an autoscaling minimum and maximum. You start from a measured baseline (requests per second, CPU utilization, memory, IOPS, queue depth), you attach a growth assumption (10 percent month over month, or a Black Friday spike of 8x), and you size resources so that even at peak you stay under a chosen utilization target with room to spare.
It is different from scaling. Scaling is the mechanism that adds or removes resources. Capacity planning is the decision about how much you need and when, so that scaling has the right limits set and the budget exists to back it.