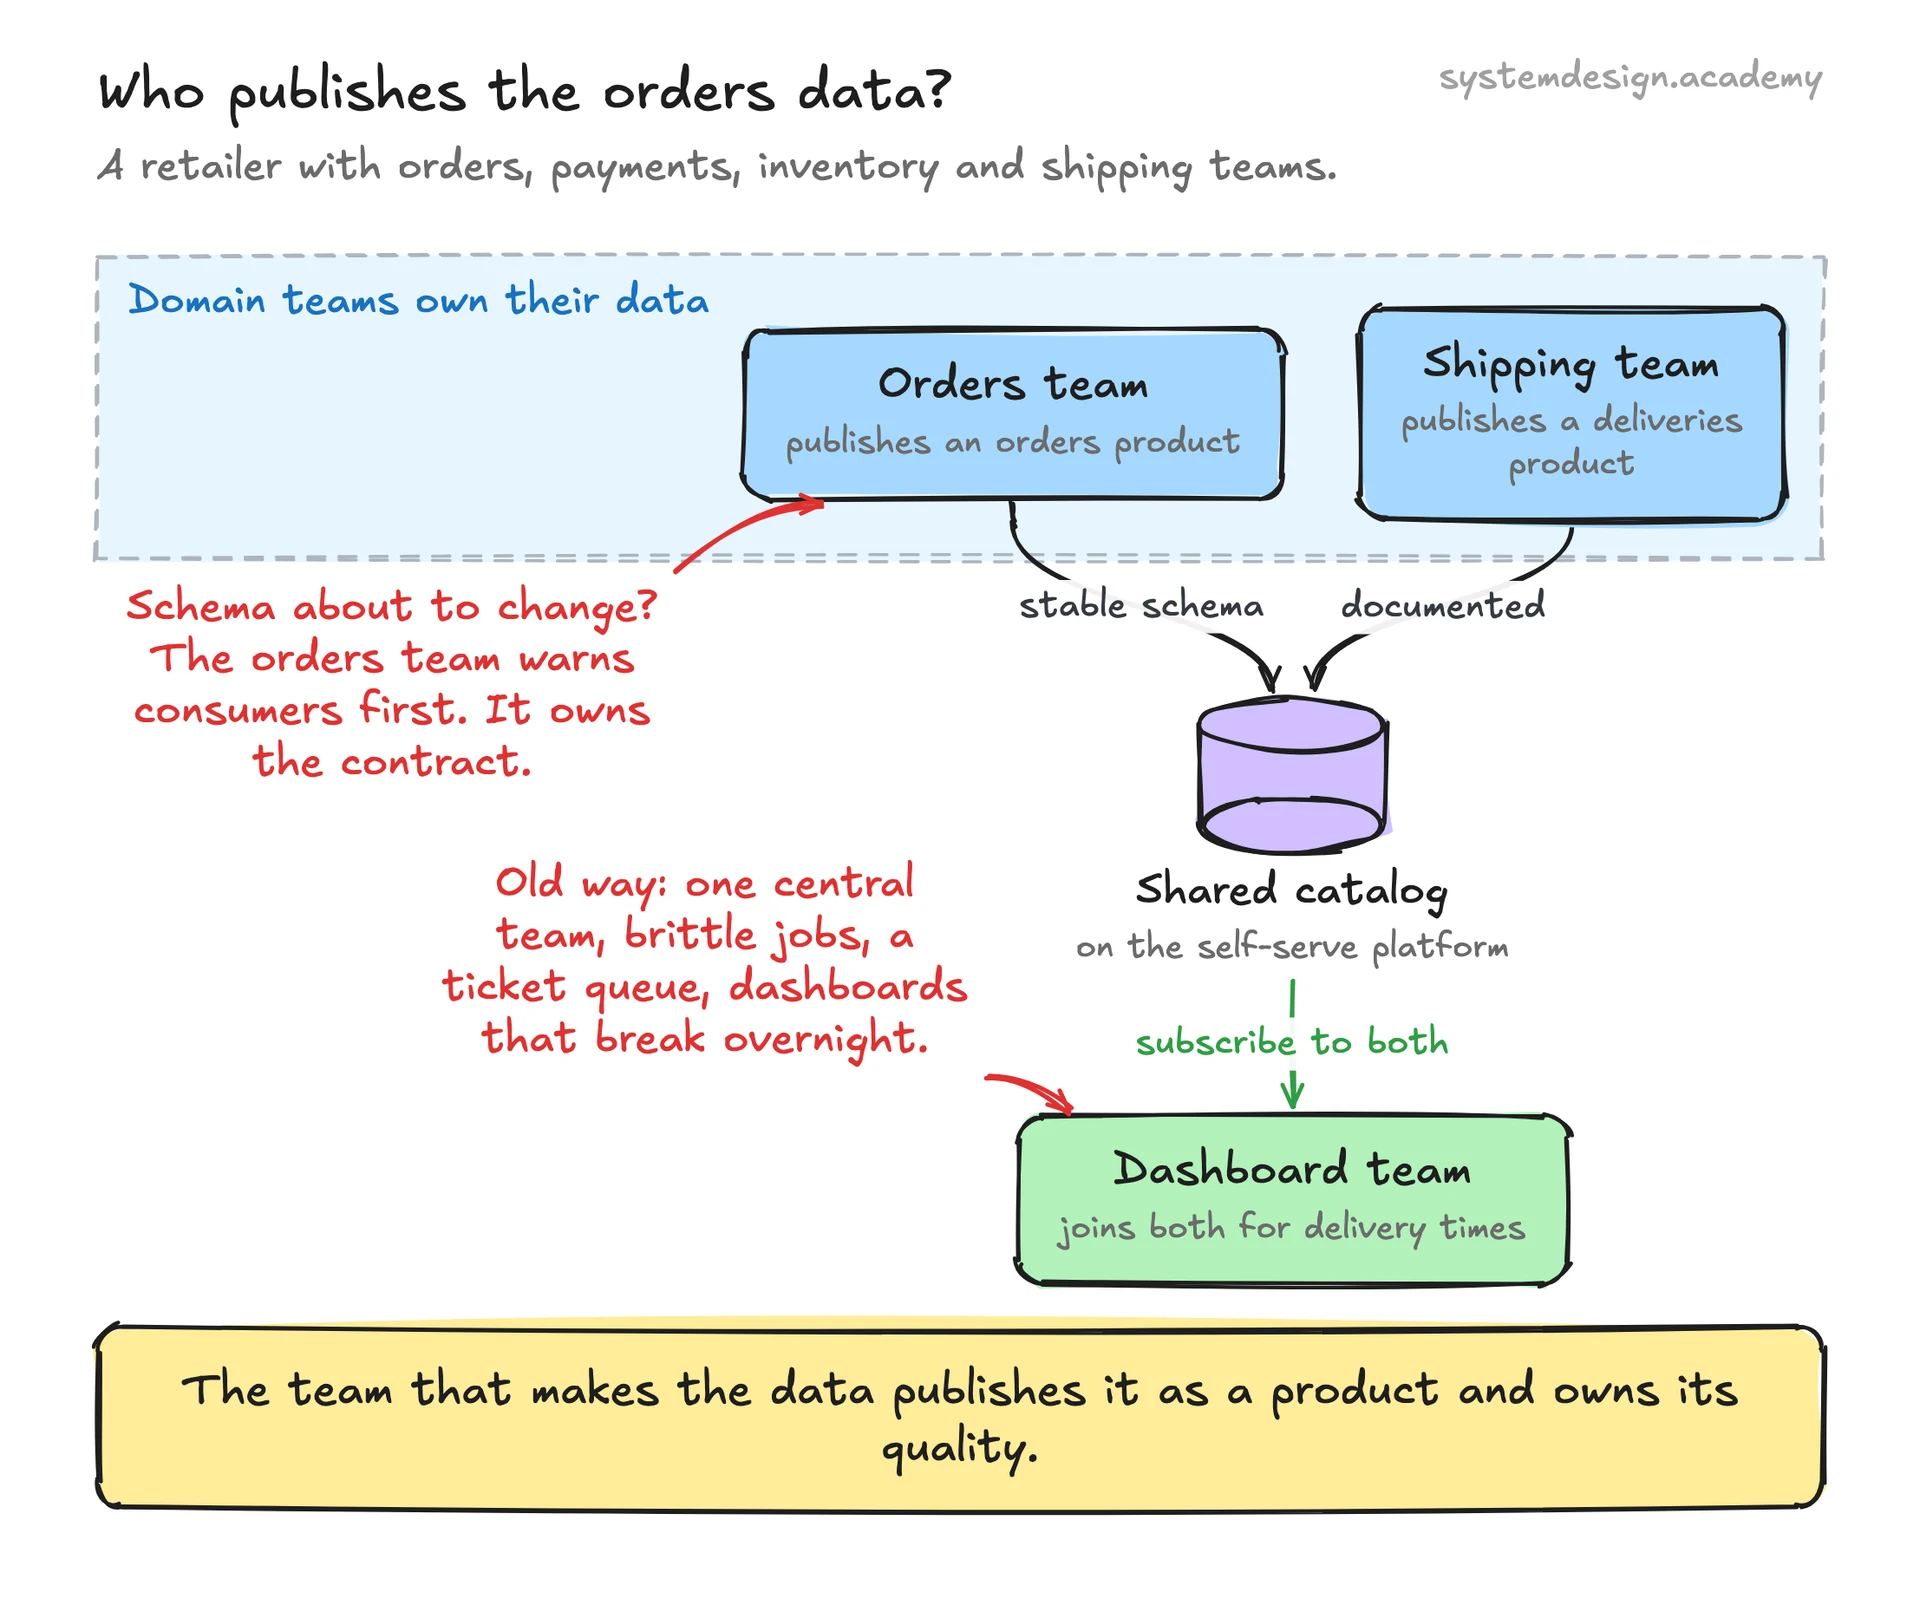
A data product is more than a table. It bundles the actual data, the metadata describing it, the code that produces it, the access policies, and a contract for how consumers read it. Each product exposes well-defined output ports, often an object-store dataset in Parquet or Iceberg, a streaming topic, or a queryable view, plus a schema and a service level objective for freshness and quality.
The self-serve platform is the piece that makes this scale. Without it, asking 40 domain teams to each run their own pipelines, catalogs, and access controls would create 40 snowflakes. So a central platform team builds the paved road: standard ways to register a data product, provision storage, run transformations, attach quality tests, and publish to a shared catalog. Domain engineers use that platform without writing infrastructure from scratch.
Federated computational governance is enforced by code, not by a committee writing PDFs. Policies like PII tagging, encryption at rest, retention windows, and a shared identifier format are baked into the platform and checked automatically when a product is published. A governance group made of domain representatives decides the global rules; the platform makes following them the easy path.