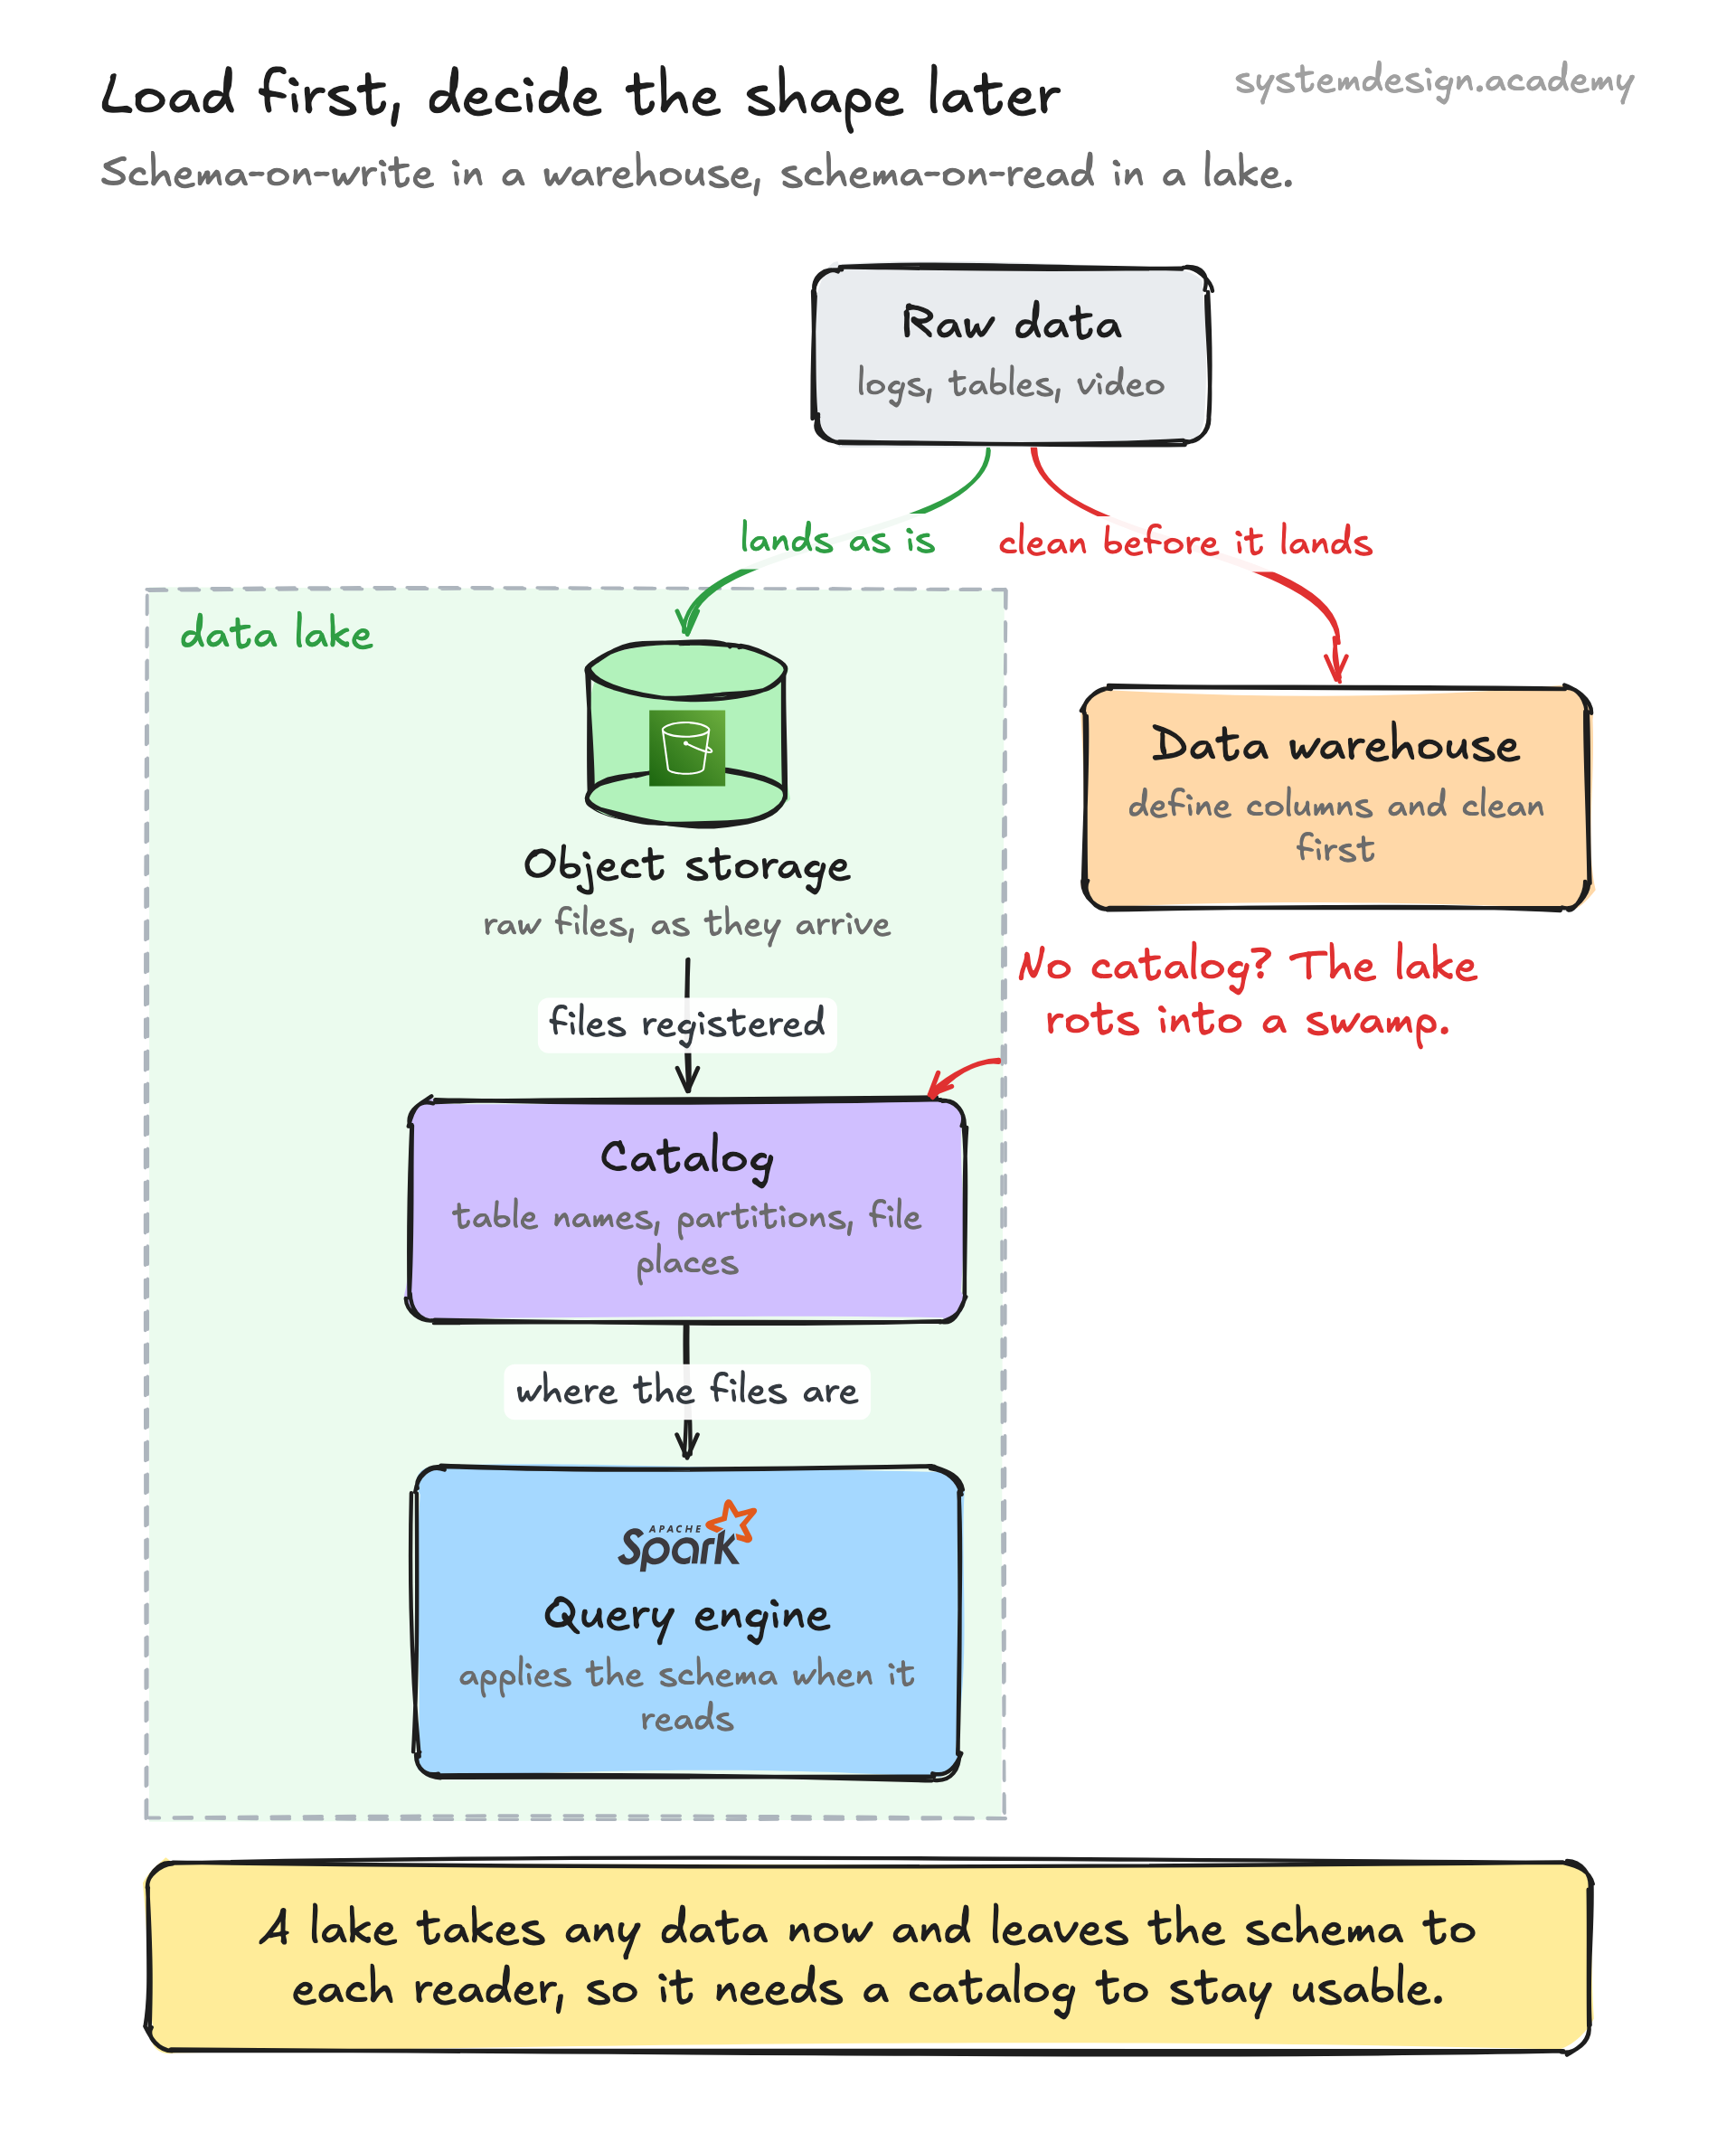
A data lake is not a single product, it is a layered design on top of object storage. The bottom layer is the raw files in S3 or equivalent. On top sits a table format such as Apache Iceberg, Delta Lake, or Apache Hudi that tracks which files belong to which table and adds ACID transactions, schema evolution, and time travel.
A separate metadata catalog records table names, partitions, and file locations so query engines can find data without scanning everything. AWS Glue Data Catalog and Apache Hive Metastore are typical choices. Without a catalog, a lake degrades into a pile of files nobody can query efficiently, often called a data swamp.
Query engines like Trino, Apache Spark, Amazon Athena, and Presto read the files directly. Because compute is separate from storage, you can spin up a hundred Spark workers for a nightly job and shut them down afterward, paying only for the minutes you used. Columnar file formats like Parquet and ORC make these scans fast by reading only the columns a query needs.