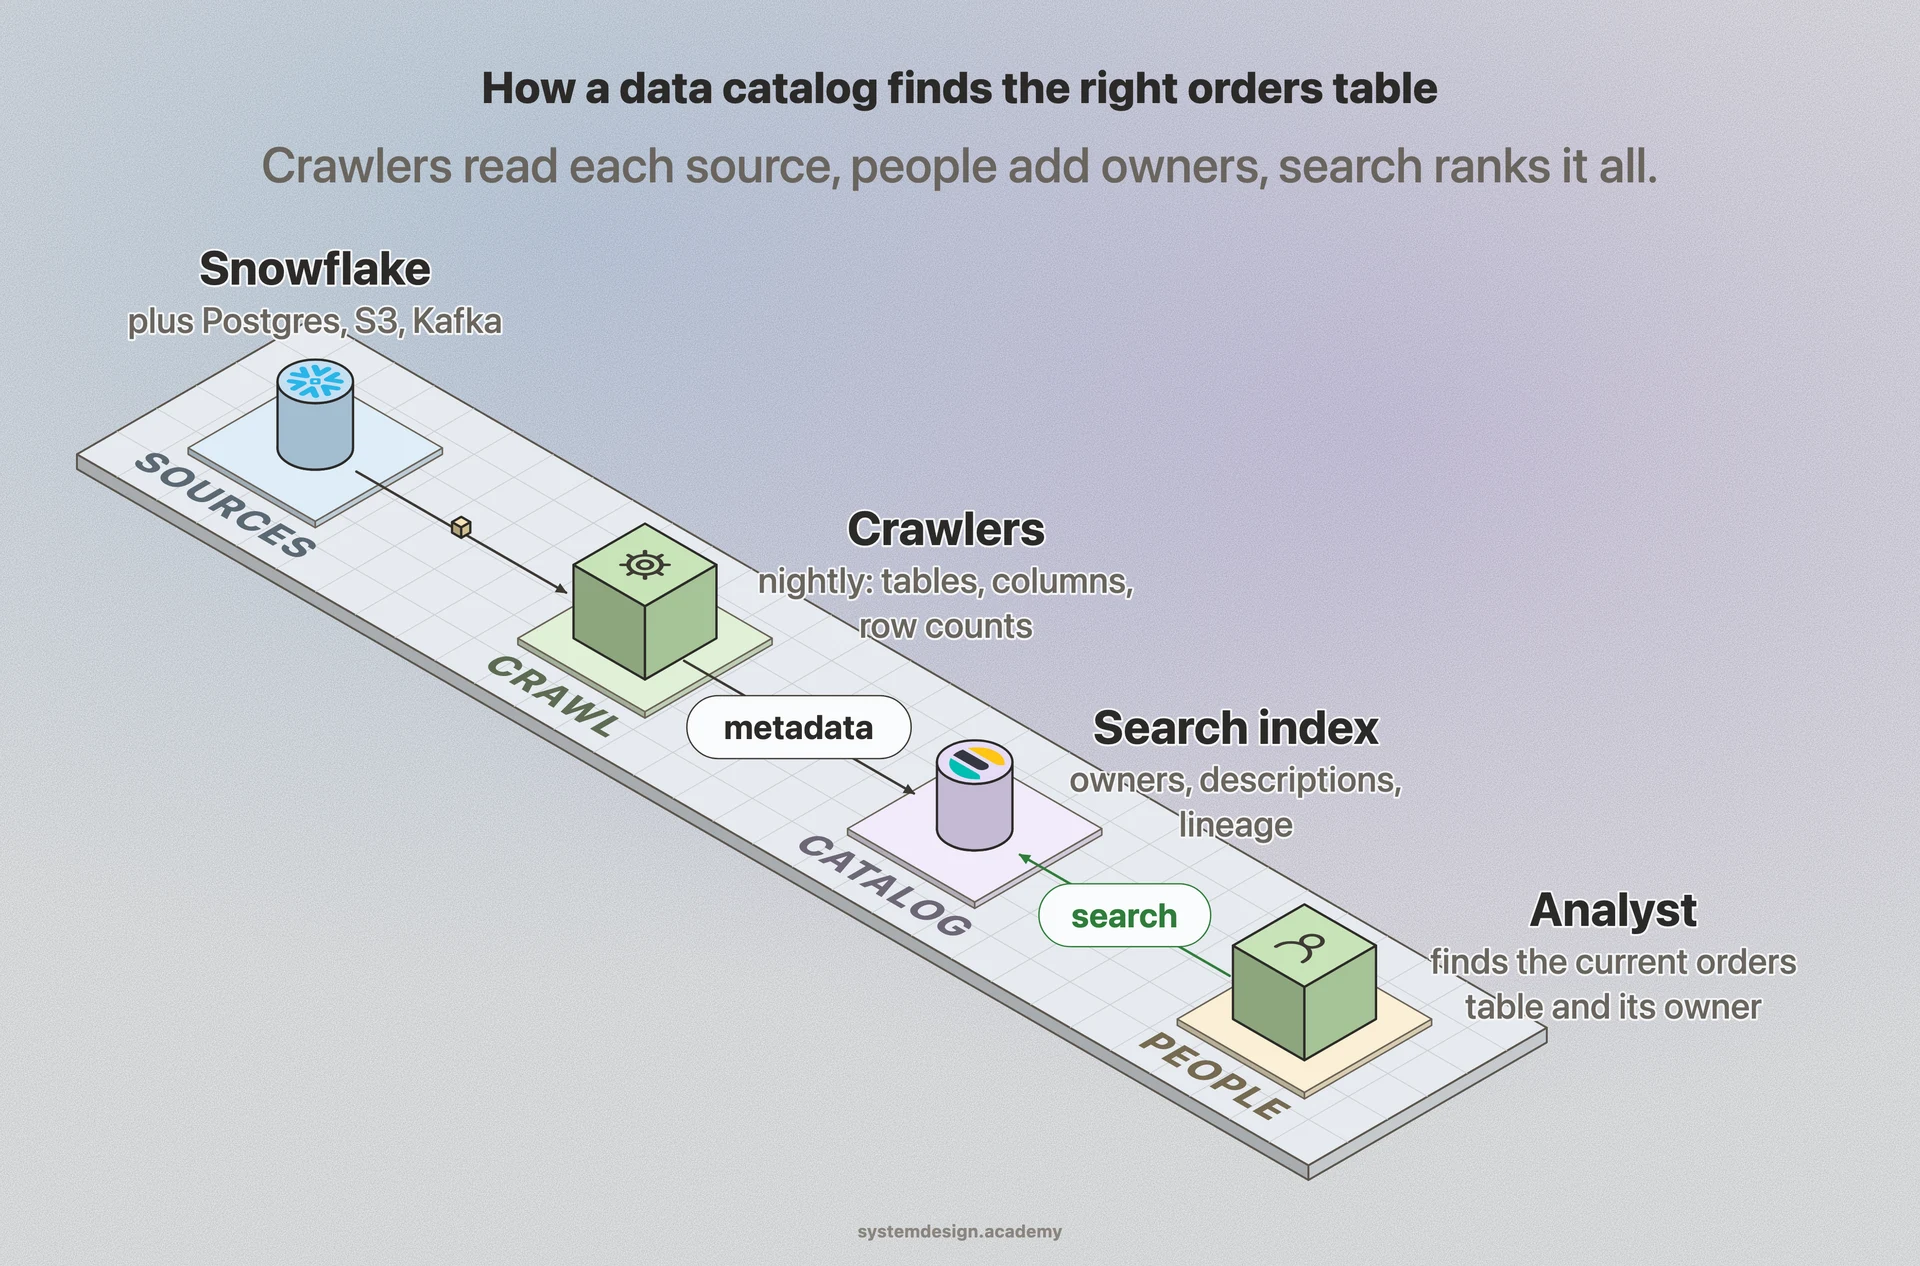
Catalogs build their index through crawlers, also called connectors or scanners. A crawler connects to a source such as Snowflake, Postgres, S3, or Kafka, reads its system tables and information_schema, and pulls back the technical metadata: table names, columns, types, partition layout, and row counts. This runs on a schedule, often nightly, so the catalog stays close to the real state of the warehouse.
On top of that the catalog stores business metadata that humans add: descriptions, owners, glossary terms, and tags like sensitive or deprecated. Lineage is the third big piece. By parsing SQL query logs and pipeline definitions, the catalog builds a graph showing that raw_events feeds daily_sessions which feeds the executive dashboard, so you can trace any number back to its source and see what breaks downstream if a table changes.
All of this gets indexed in a search engine, usually Elasticsearch or a similar full text store, with a metadata model behind it. Modern catalogs also expose APIs and event streams so metadata can be pushed in automatically from dbt, Airflow, or Spark jobs rather than only pulled by crawlers.