The core trick is deciding which node owns which key. Naively you could do hash(key) % N where N is the node count, but that breaks badly when you add or remove a node because almost every key suddenly maps somewhere new and the whole cache effectively empties. To avoid that, distributed caches use consistent hashing (Memcached clients) or hash slots (Redis Cluster splits the keyspace into 16384 fixed slots and assigns slots to nodes). Adding a node then only moves a small fraction of the keys.
Clients usually compute the target node themselves and connect directly, so there is no central router to bottleneck on. Reads and writes go straight to the owning node.
To survive failures, nodes are replicated. In Redis Cluster each primary (master) shard has one or more replicas that receive a copy of its writes; if the primary dies, a replica is promoted. Memcached has no built-in replication, so a lost node means that slice of cached data is simply gone and gets refilled from the database on the next request.
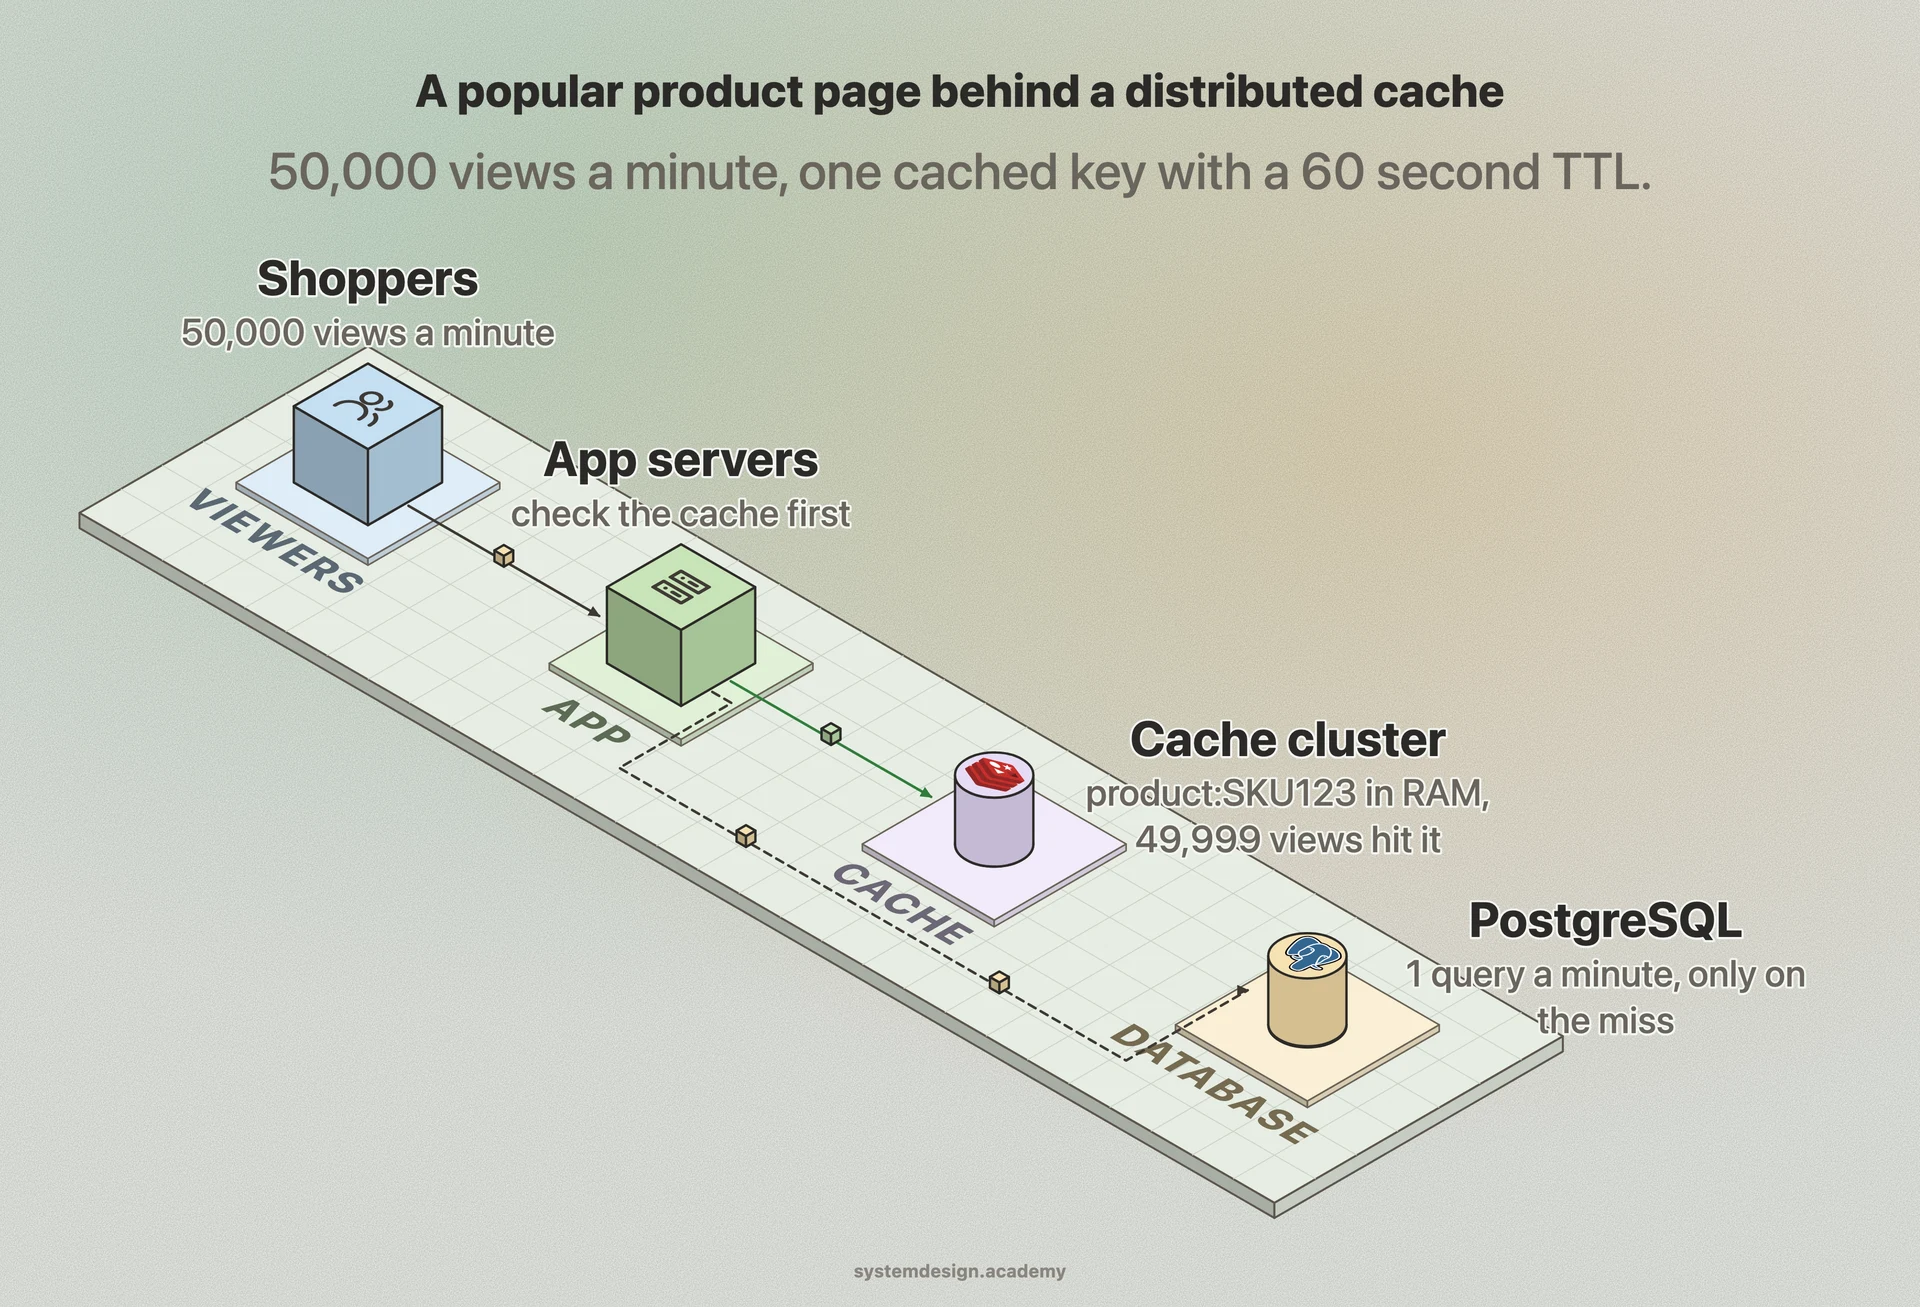
The application is responsible for keeping the cache in sync with the database. The common pattern is cache-aside: on a read, check the cache, and on a miss load from the database and write the value back into the cache with a TTL (time to live) so stale entries eventually expire. On a write, update the database and either delete or update the cached key.