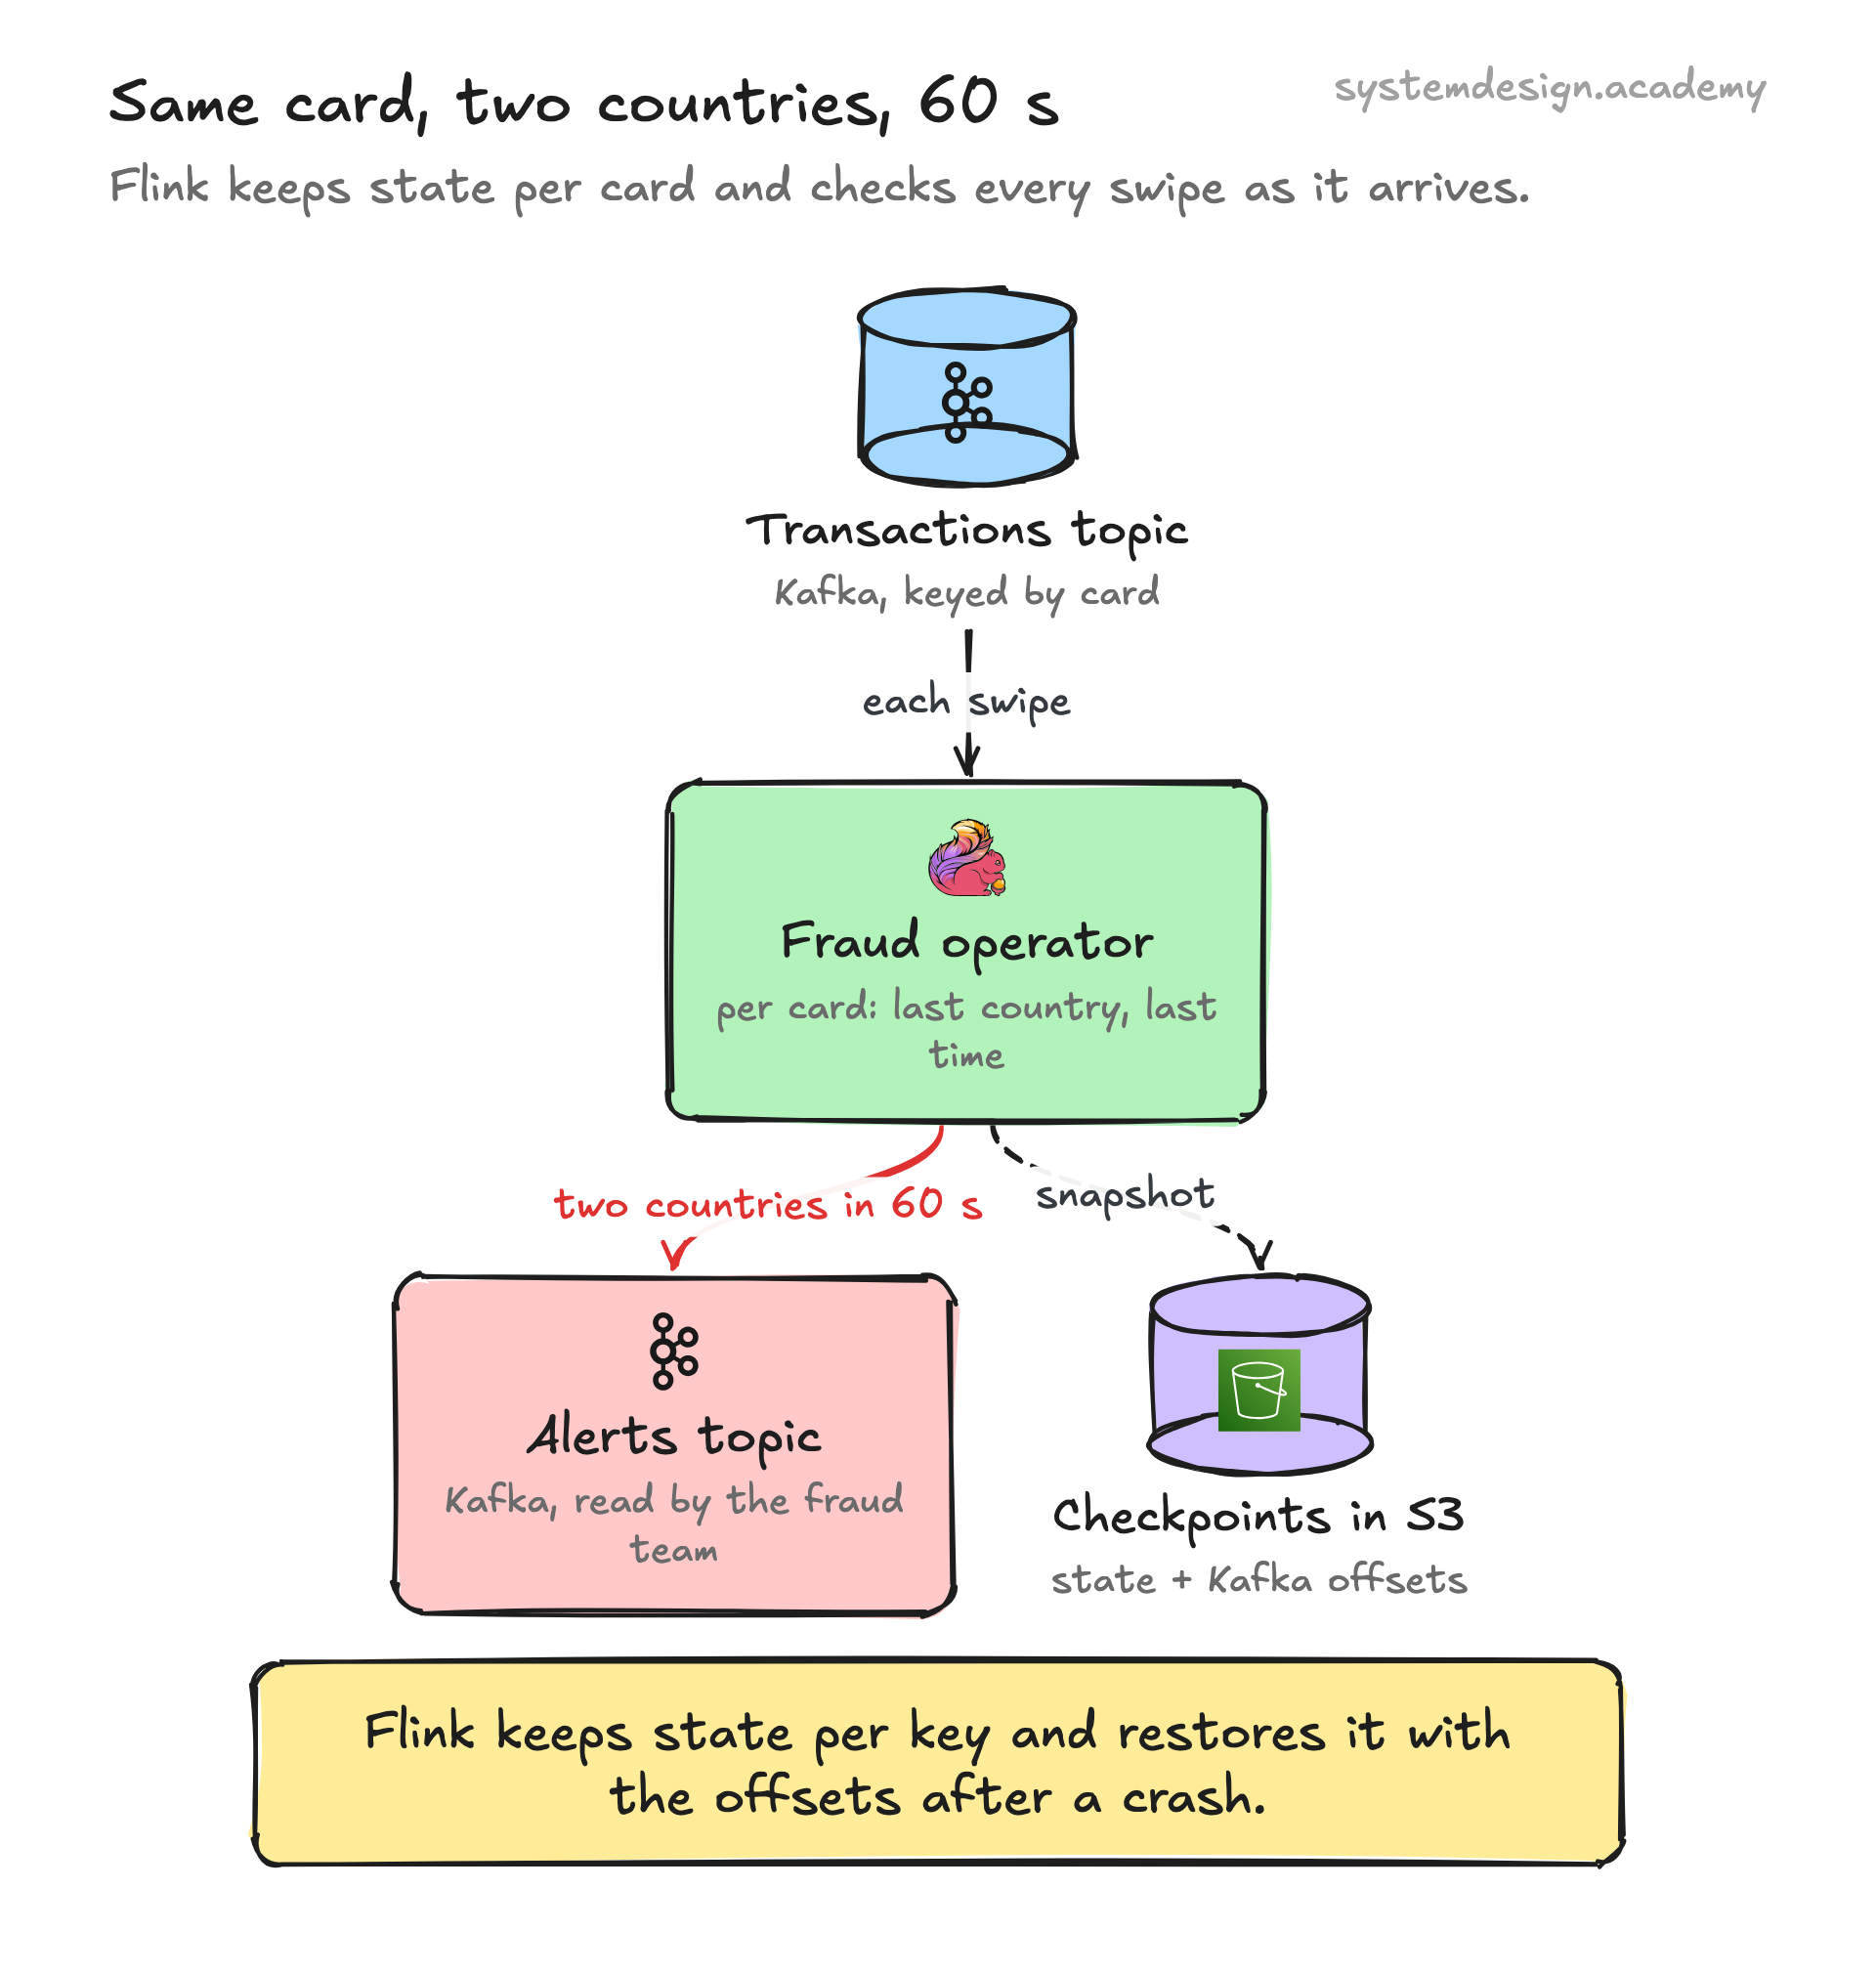
You write a job as a graph of operators: sources read events, transform operators map and filter and aggregate, and sinks write results out. Flink turns that graph into parallel tasks and spreads them across worker processes called TaskManagers, coordinated by a JobManager. Each operator instance handles a slice of the data, partitioned by a key such as user ID.
State lives next to each operator, either in memory or, for large state, on local disk through an embedded RocksDB store, so reads and writes stay fast. To survive failures, Flink runs the Chandy-Lamport algorithm: it injects markers called barriers into the stream, and when a barrier flows through every operator, Flink writes a consistent snapshot of all state to durable storage like S3 or HDFS. These snapshots are called checkpoints and run every few seconds.
When a machine dies, Flink rolls every operator back to the last completed checkpoint and replays the events that came after it. Because the source position and the state are restored together, each event affects the result exactly once. This is the exactly-once guarantee, and it is the main reason teams pick Flink over simpler tools.
Flink also understands event time, the timestamp baked into each event, separate from when it was processed. Watermarks tell Flink how far event time has progressed so it can correctly close time windows even when events arrive late or out of order, which is normal in real networks.