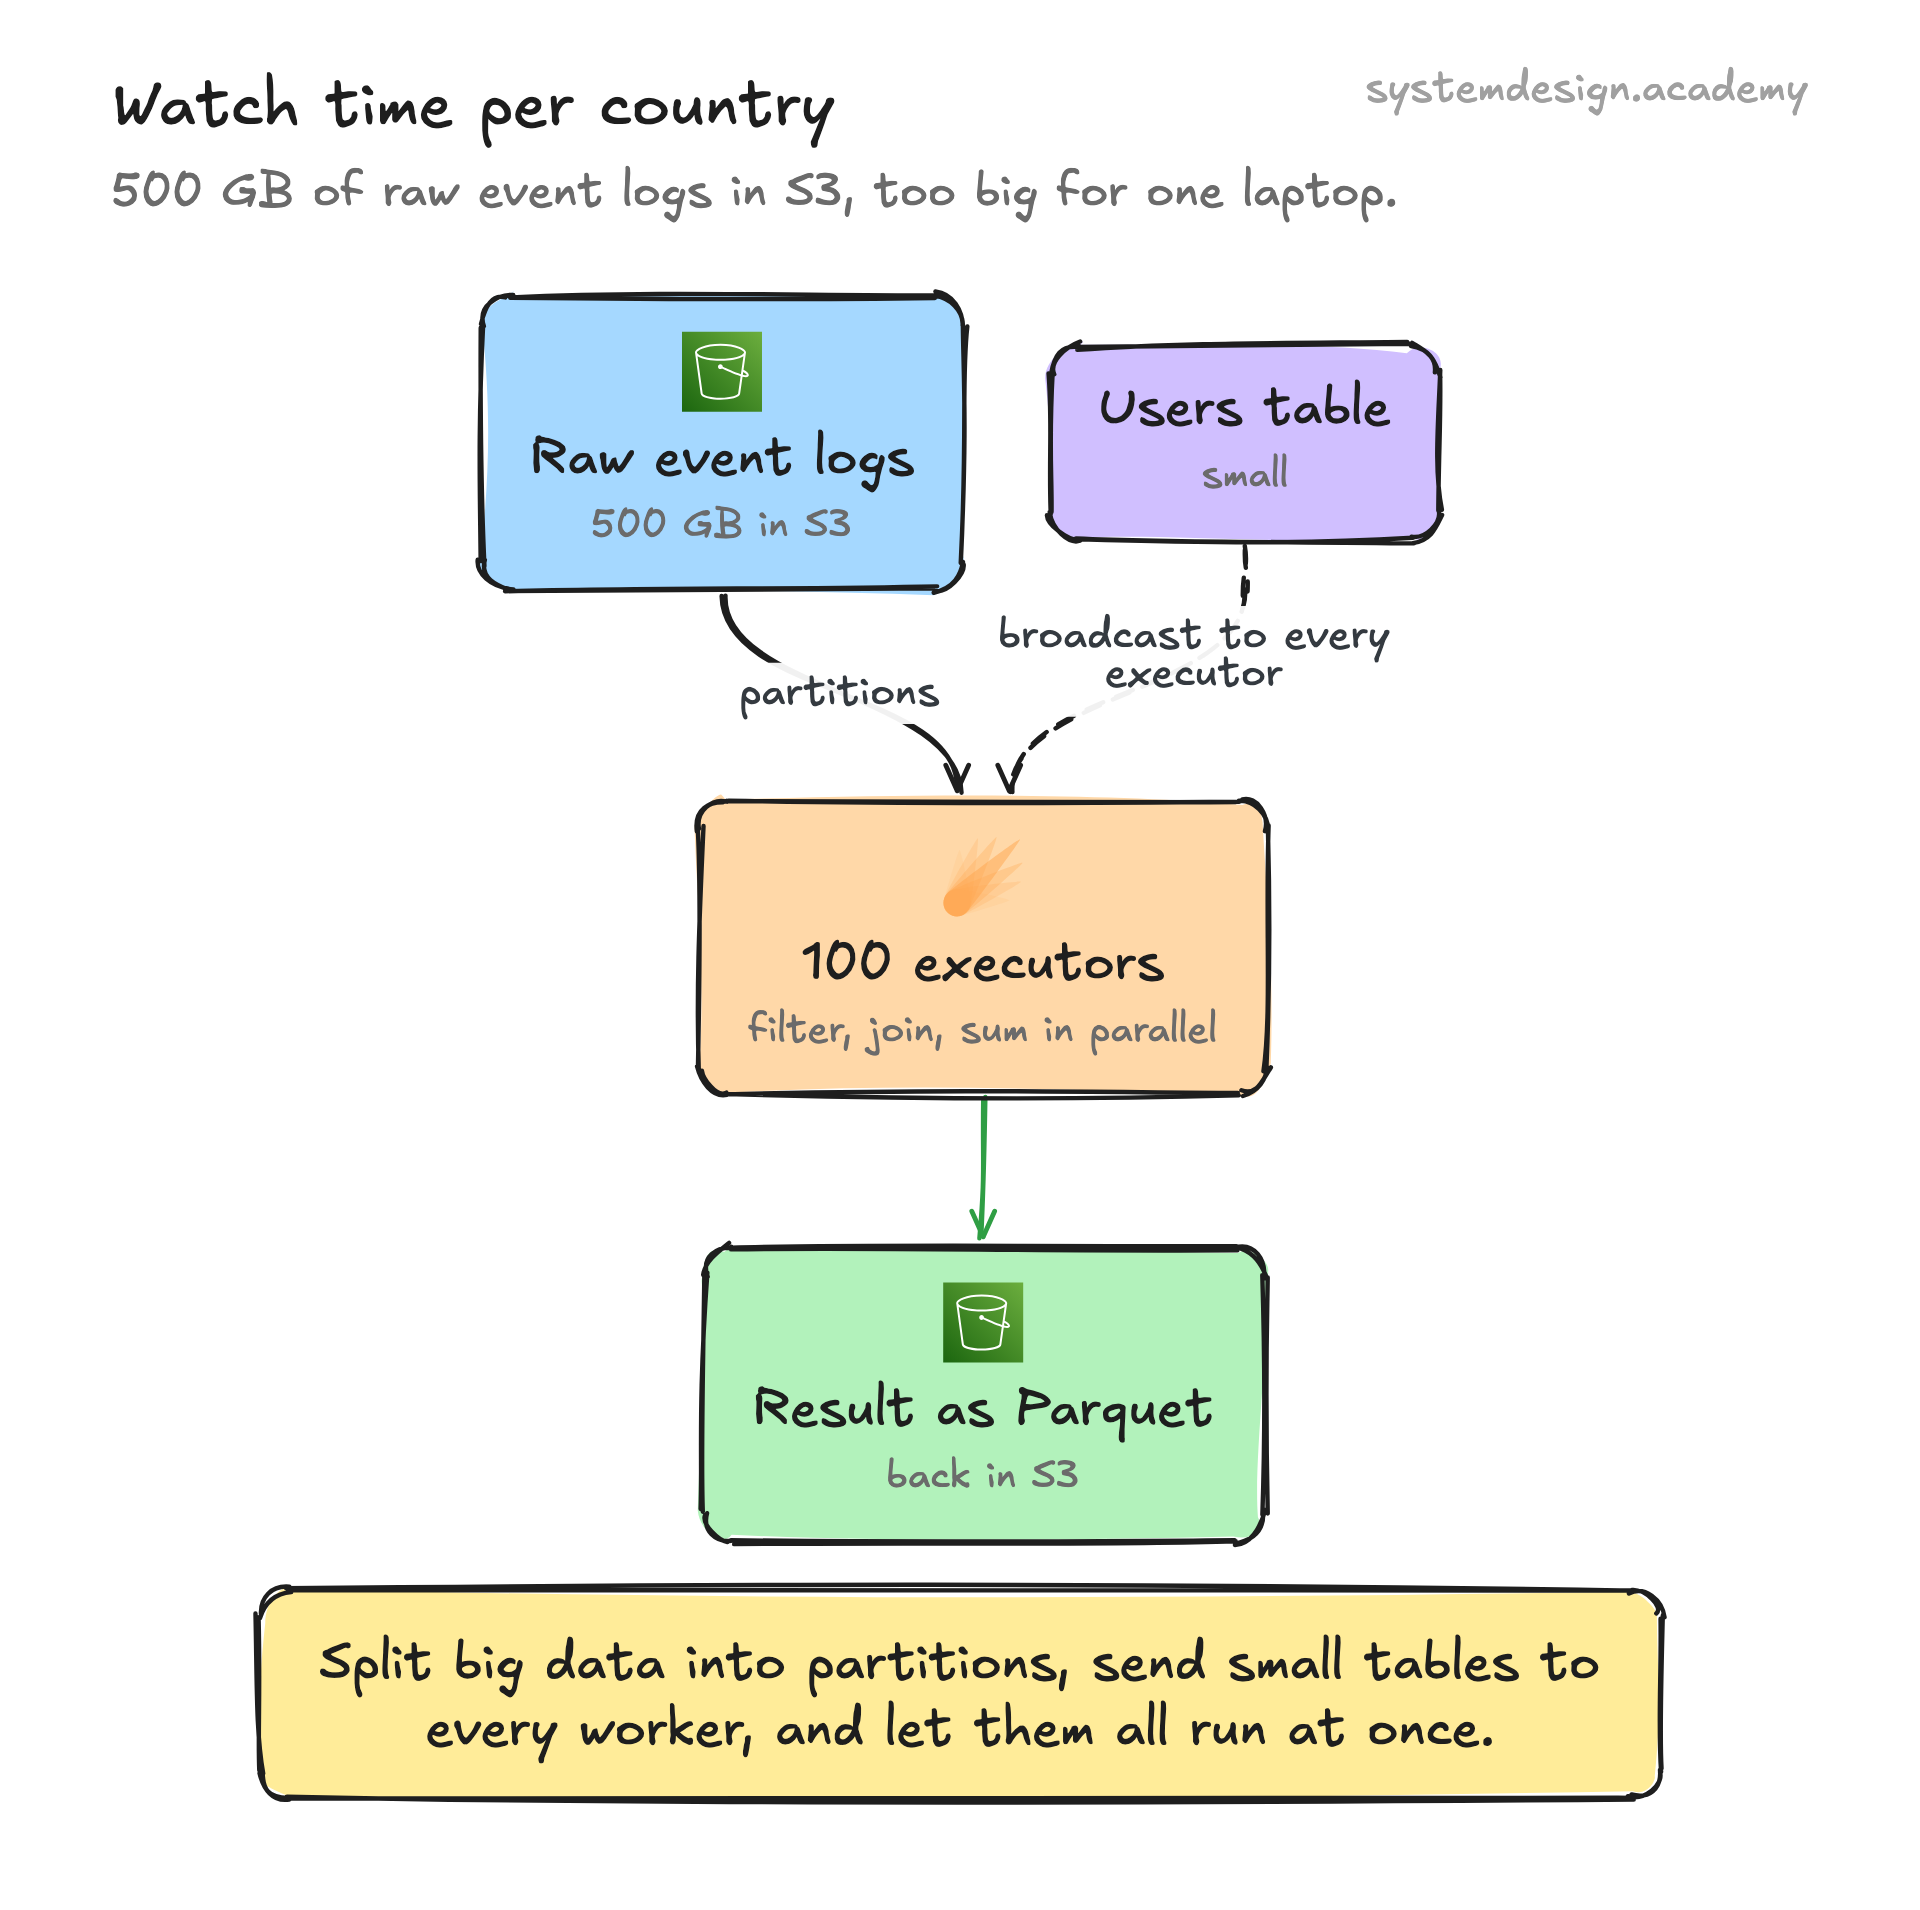
A Spark application has one driver and many executors. The driver is the process running your code; it builds the plan and hands out work. Executors are JVM processes on the worker machines that actually run the tasks and hold data in memory. A cluster manager like YARN, Kubernetes, or Spark standalone decides which machines the executors land on.
Spark is lazy. When you call transformations like filter, map, or join, nothing runs yet. Spark just records them as a graph of steps, called the DAG (directed acyclic graph). Only when you call an action, like count, collect, or write, does Spark look at the whole DAG, optimize it, split it into stages, and launch tasks. One task processes one partition of the data, so a dataset split into 200 partitions becomes 200 tasks.
The core abstraction is the partitioned dataset. Older code uses the RDD (resilient distributed dataset). Modern code uses DataFrames and the Dataset API, which go through the Catalyst optimizer. Catalyst rewrites your query into a faster plan, for example pushing a filter down so less data is read, before it ever runs. This is why a DataFrame is usually faster than hand written RDD code.
Fault tolerance comes from lineage. Spark remembers the recipe that produced each partition. If a machine dies mid job, Spark recomputes only the lost partitions from their inputs instead of restarting the whole thing. The expensive step is a shuffle, where data has to be repartitioned across the network, for example during a join or a group by; minimizing shuffles is most of Spark performance tuning.