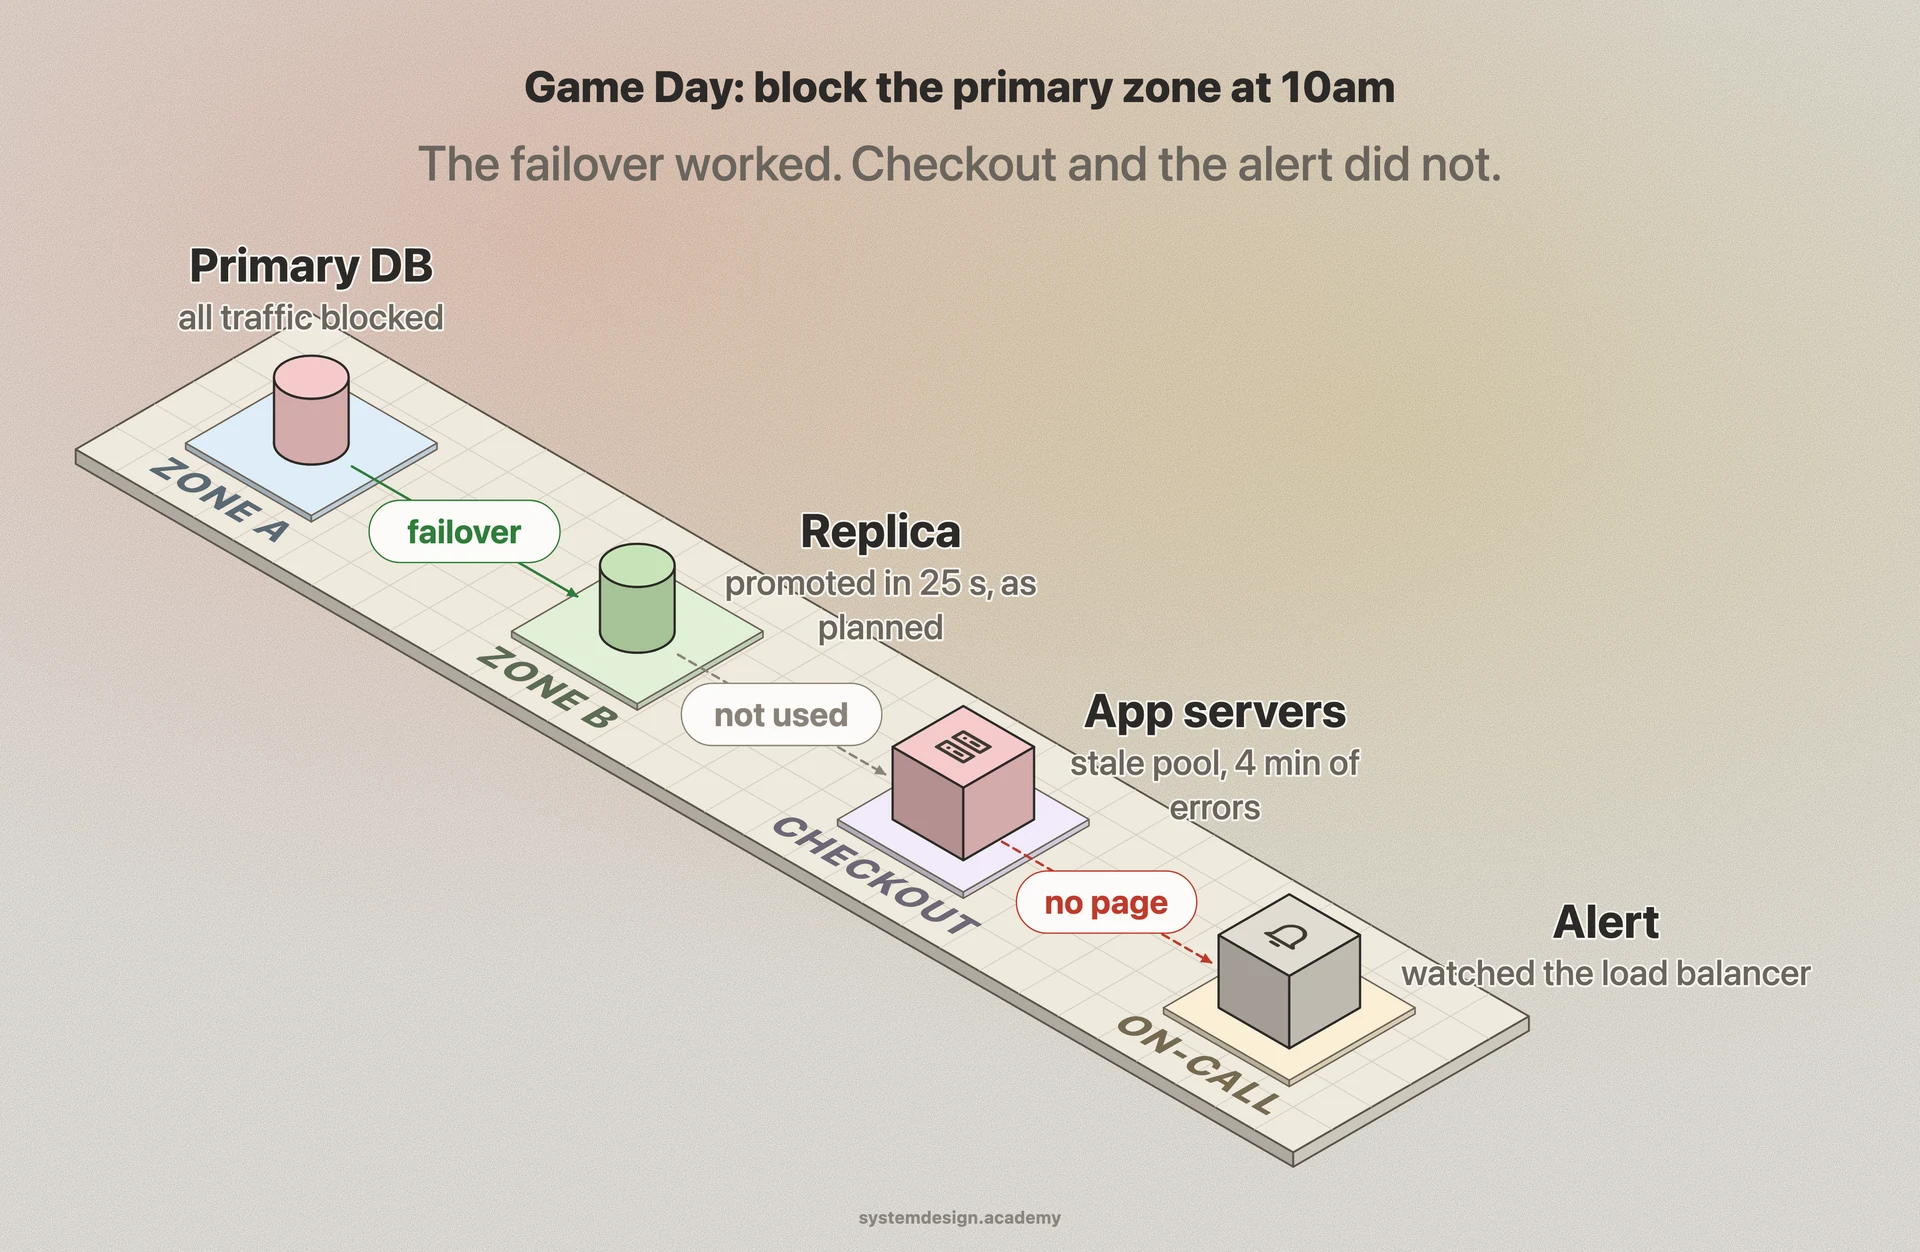
It starts with a hypothesis. The team writes down what they expect: for example, if the primary Postgres node dies, the replica should be promoted within 30 seconds, traffic should reroute automatically, and PagerDuty should page within 1 minute. Writing the expectation first is what turns a random outage into a useful test.
Next comes a blast-radius plan. You decide exactly what you will break, for how long, and how you will stop it. You define an abort condition, such as error rate above 5 percent for paying customers, and a one-command rollback. Running on a real but low-traffic window, or on a staging copy carrying mirrored traffic, keeps the risk contained.
Then the team triggers the failure, often using a chaos engineering tool to inject it precisely. They observe dashboards, alerts, and human actions in real time. After recovery, the most important part is the debrief: every gap becomes a ticket. A Game Day with no follow-up action items was mostly theater.
The difference from general chaos engineering is scope. Chaos engineering is often automated and continuous; a Game Day is a scheduled, human-in-the-loop event focused as much on the team's response as on the system's behavior.