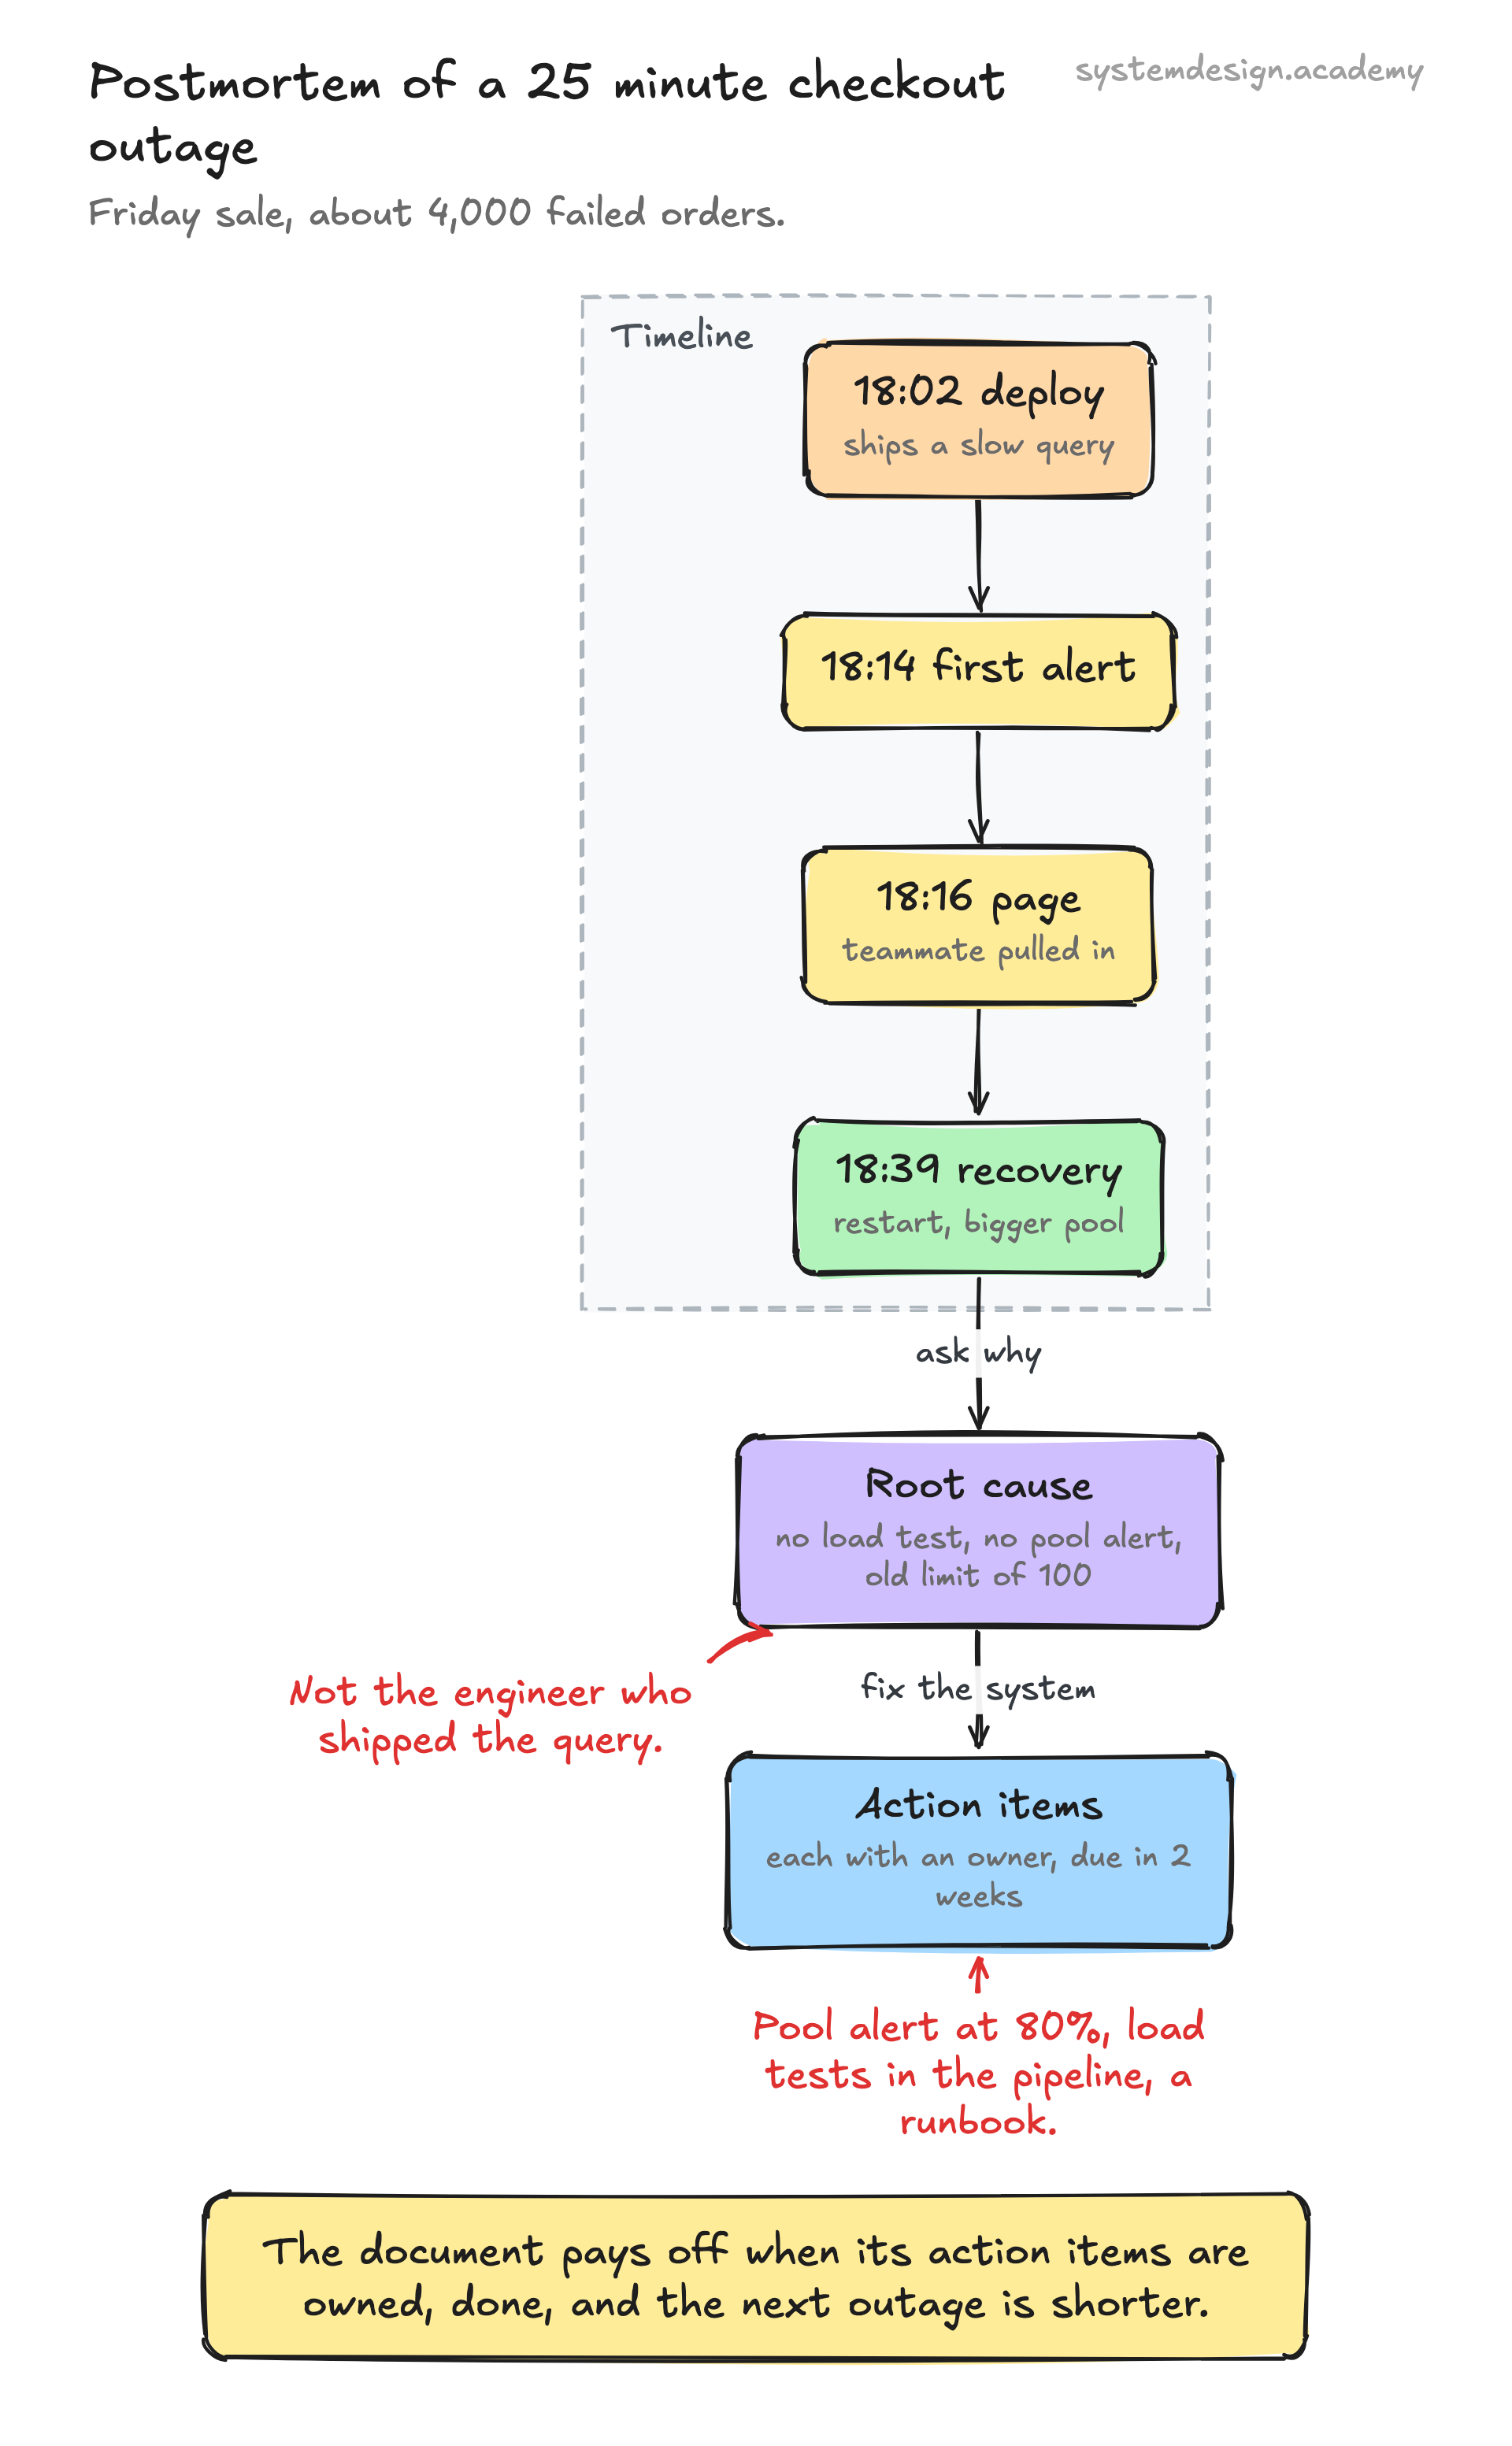
Suppose a checkout service goes down for 25 minutes during a Friday evening sale. Customers see errors, and roughly 4,000 orders fail. The on-call engineer pages a teammate, they trace it to a database connection pool that hit its limit of 100 connections, and they recover by restarting the service and raising the pool size.
The postmortem timeline shows the deploy that introduced a slow query at 18:02, the first alert at 18:14, the page at 18:16, and recovery at 18:39. The root cause is not the engineer who shipped the query. It is that the new query was not load tested, there was no alert on connection pool saturation, and the pool limit was set years ago and never revisited.
The action items become: add a connection pool saturation alert at 80 percent, add load testing to the deploy pipeline for queries touching the orders table, and document a runbook for pool exhaustion. Each gets an owner and a due date within two weeks. Three months later, when a similar slow query ships, the alert fires early and the runbook makes recovery a five-minute task instead of a 25-minute outage. That difference is the entire return on writing the document.