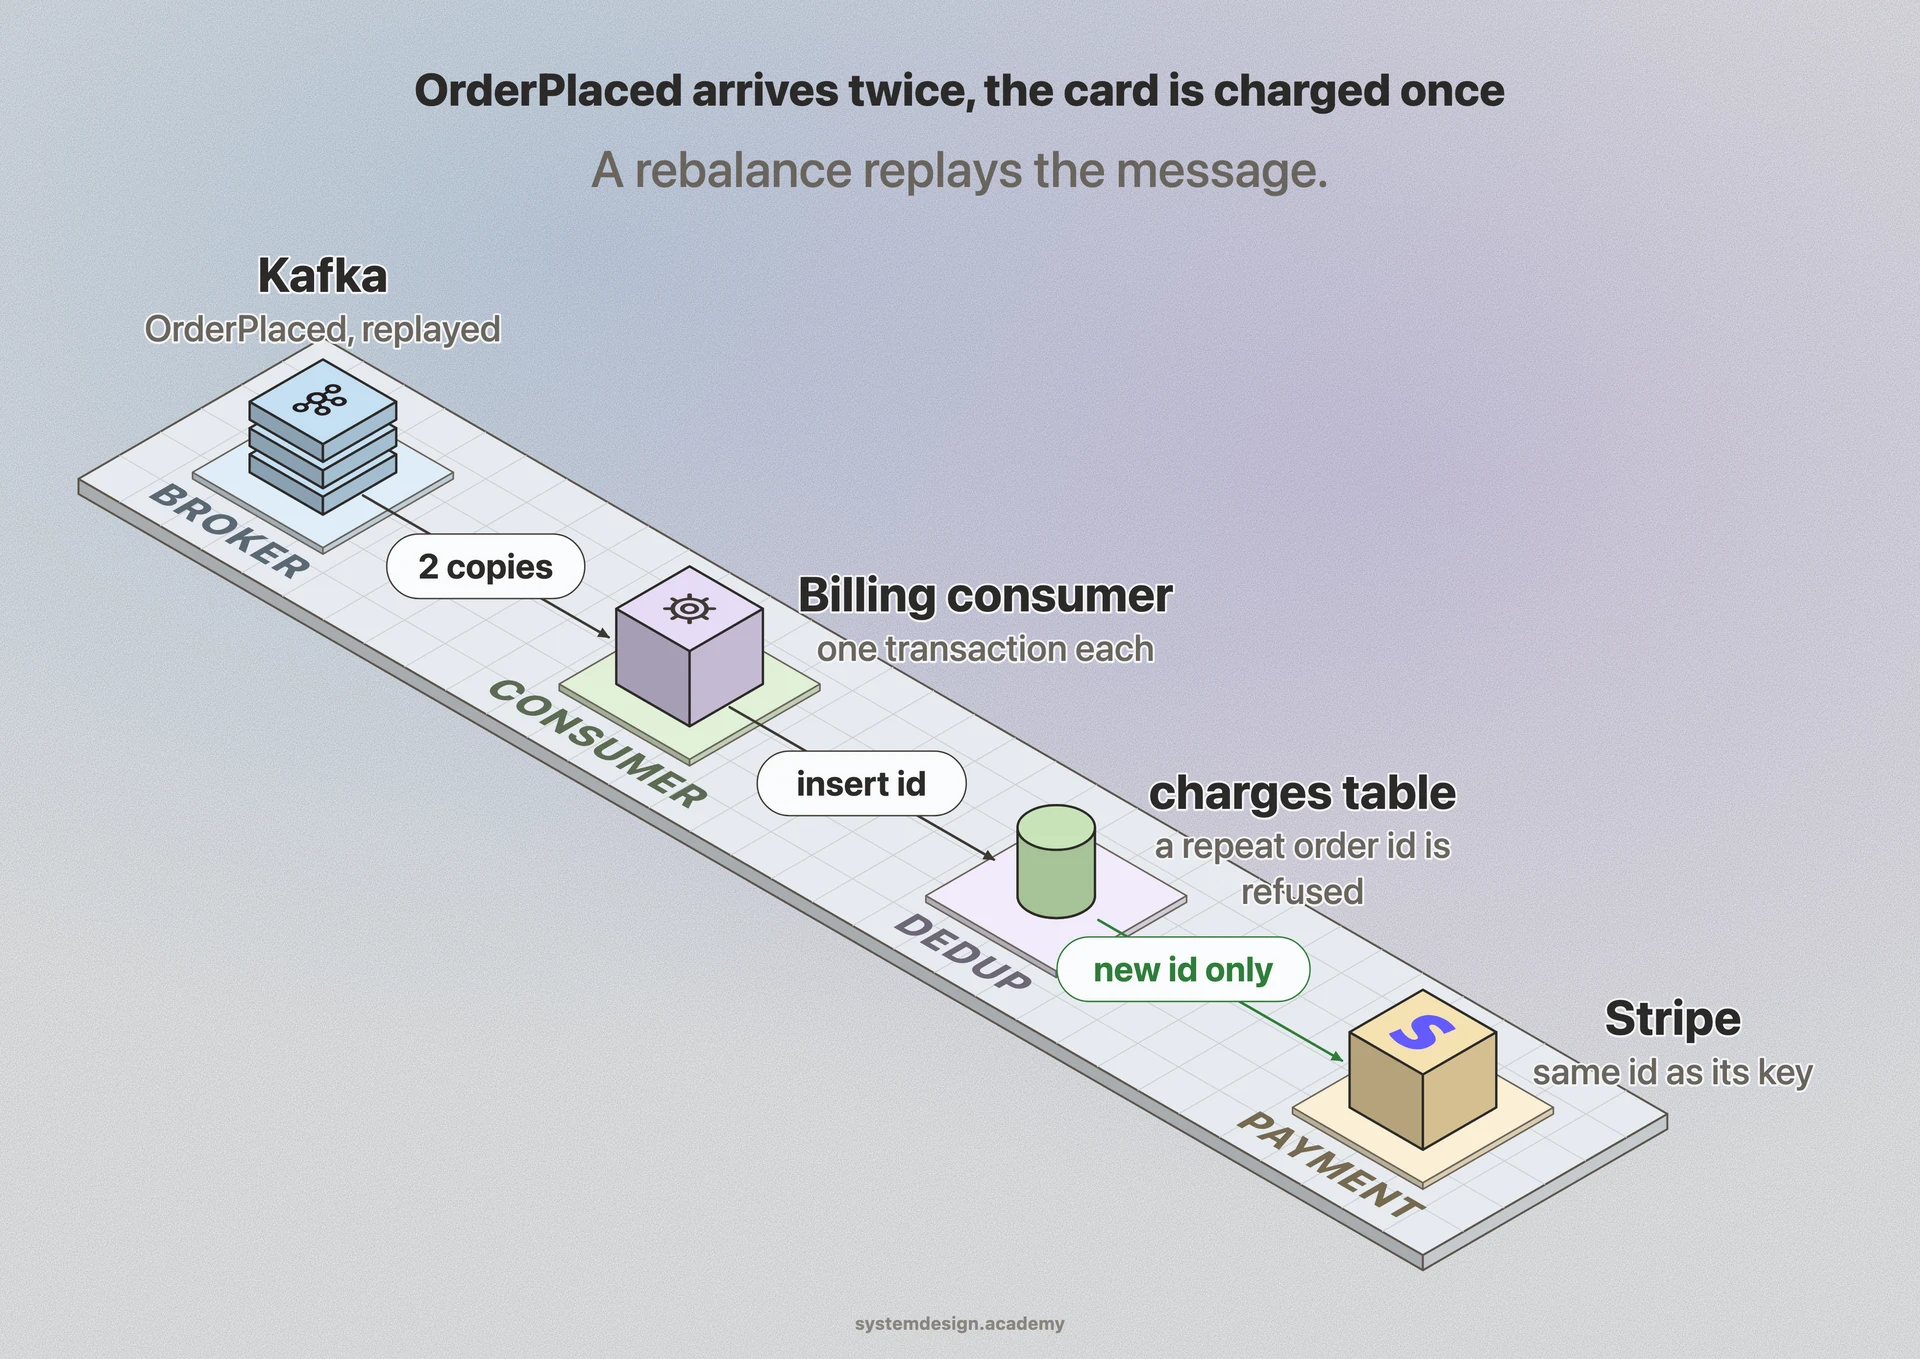
The most common approach is a dedup table, sometimes called an inbox table or a processed-messages table. Every message carries a unique ID, either assigned by the producer or derived from its content. Before doing any work, the consumer checks whether that ID already exists in the table. If it does, the message is skipped. If not, the consumer does the work and records the ID.
The catch is that the business write and the dedup record must commit together. If you process the order but crash before saving the ID, the next redelivery will process the order again. The fix is to write both inside one database transaction, so they succeed or fail as a unit. With Postgres you might do INSERT INTO processed_messages id VALUES the_id ON CONFLICT DO NOTHING in the same transaction as the order insert; if the insert hits a conflict, you know it is a duplicate and roll back the work.
The second approach is natural idempotency, where the operation is safe to repeat by its nature. Setting account status to active is idempotent because running it twice leaves the same value. Adding 50 dollars to a balance is not, because running it twice adds 100. When you can phrase the work as a set-to or an upsert keyed on a stable ID rather than an increment, you often avoid needing a dedup table at all.
Dedup tables grow forever if you let them, so production systems expire old IDs. A common pattern keeps message IDs for a window longer than the broker's maximum redelivery delay, for example 7 days, then deletes them with a TTL or a scheduled job.