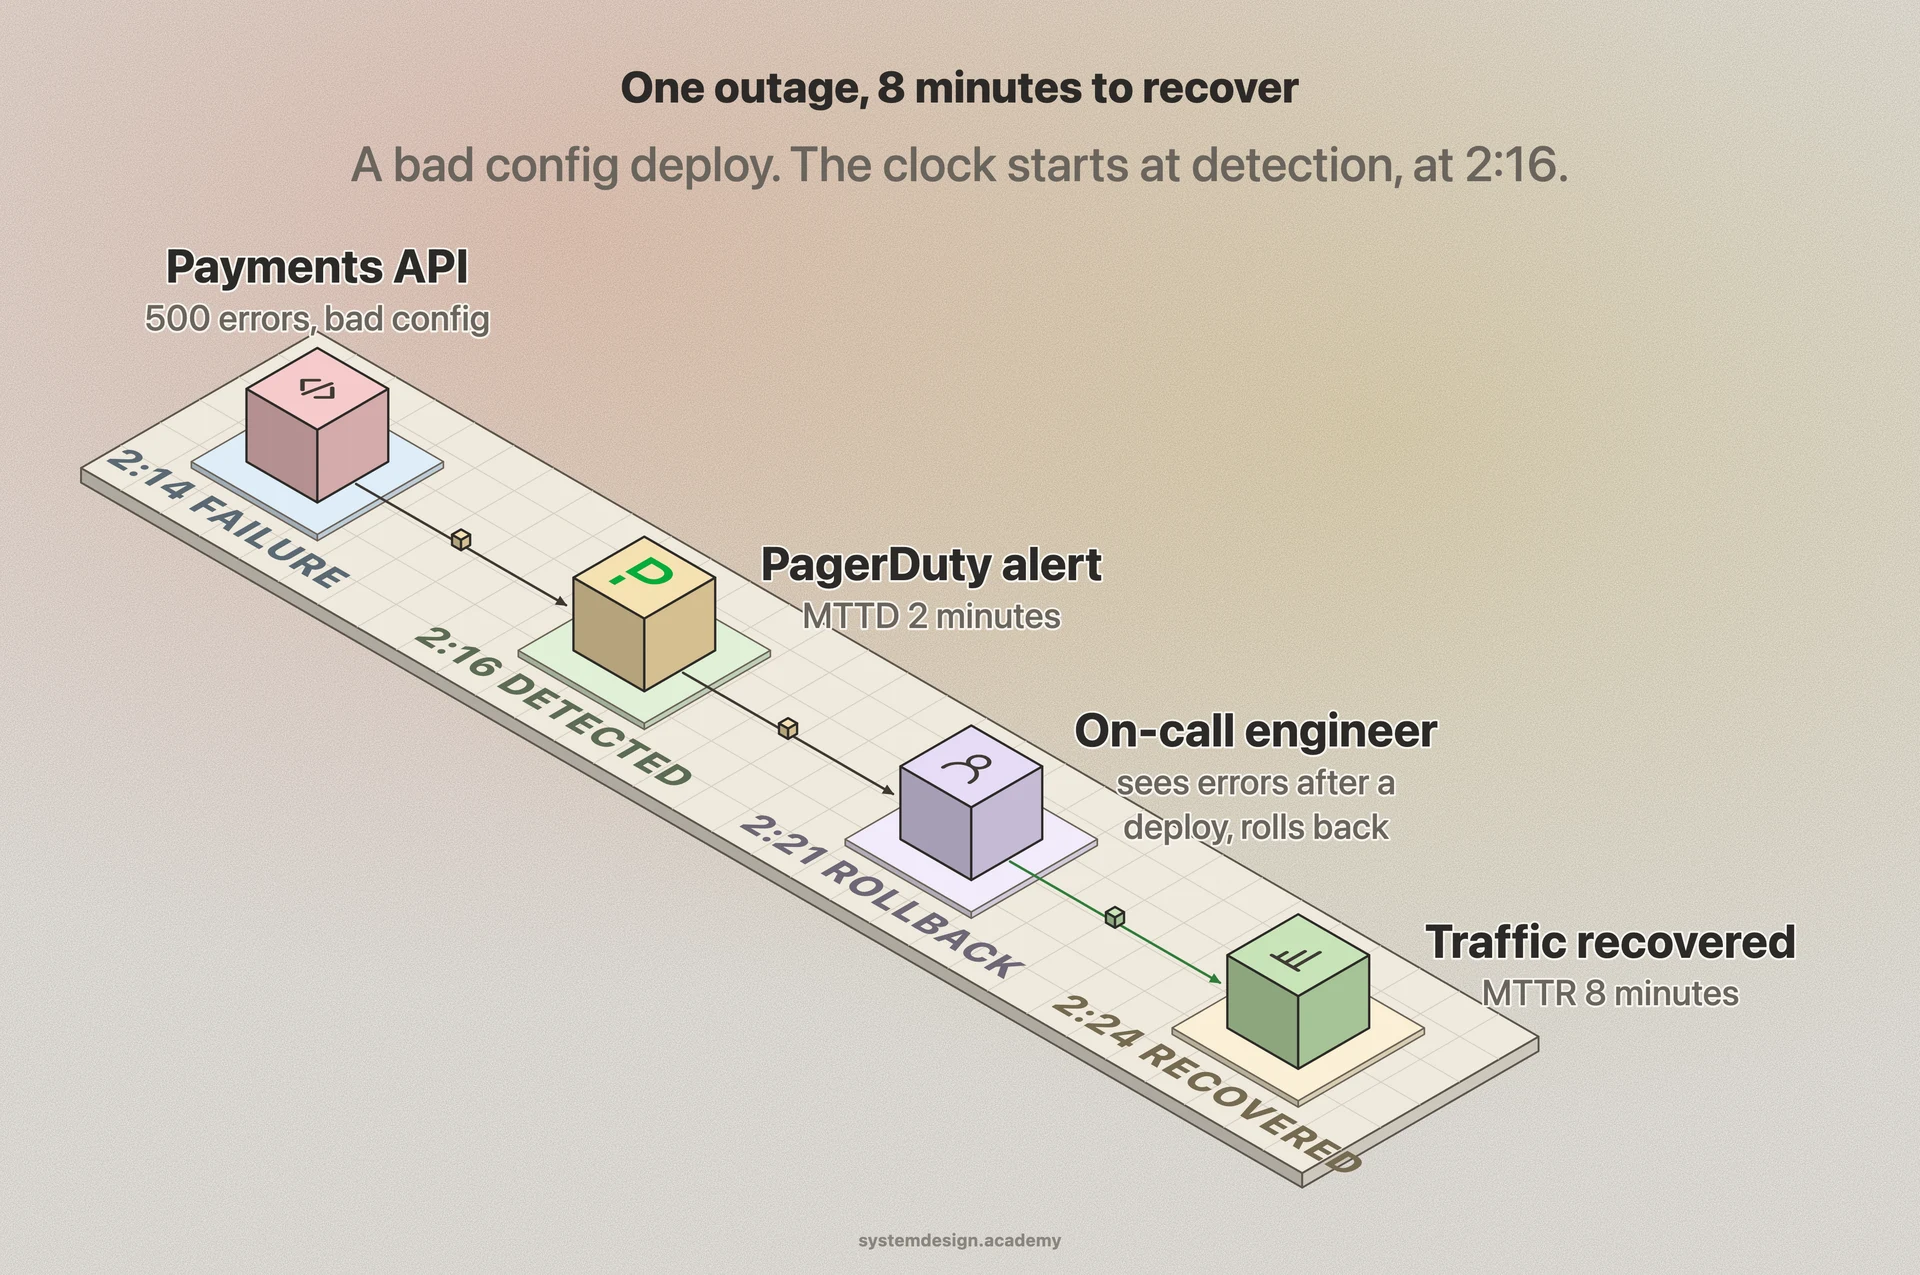
MTTR is mostly an operations and automation problem, not a code problem. The biggest wins come from cutting the time spent figuring out what broke, not the time spent typing the fix. Good observability, clear dashboards, and alerts that point at the real cause shrink the investigation phase, which is usually where the minutes pile up.
Automation is the next lever. Health checks that auto-restart a crashed container, load balancers that pull an unhealthy node out of rotation, and orchestrators like Kubernetes that reschedule failed pods all recover without a human in the loop. The fastest recovery is the one nobody had to wake up for. When humans are needed, tested runbooks turn a 40 minute scramble into a 5 minute checklist.
The other half is making rollback cheap and instant. If a bad deploy can be reverted with one command or an automatic canary rollback, recovery is near-instant. Blue-green deploys, feature flags you can flip off, and immutable infrastructure all exist largely to make MTTR small.