Horizontal scaling needs a way to route incoming requests across many identical servers. A load balancer like NGINX, HAProxy, or AWS Application Load Balancer sits in front and distributes traffic using round robin, least connections, or hashing. For this to work cleanly, the application servers should be stateless: any server can handle any request because session data lives somewhere shared, usually Redis or a database, not in local memory.
The database is almost always the part that scales last and breaks first, because it holds state. Read load is handled by adding read replicas and sending queries to them while writes go to a primary. Write load is harder. When one primary can no longer keep up, you shard: split the data across many databases by a key such as user ID, so each shard owns a slice of the rows. Discord shards by server ID, Instagram shards by user ID.
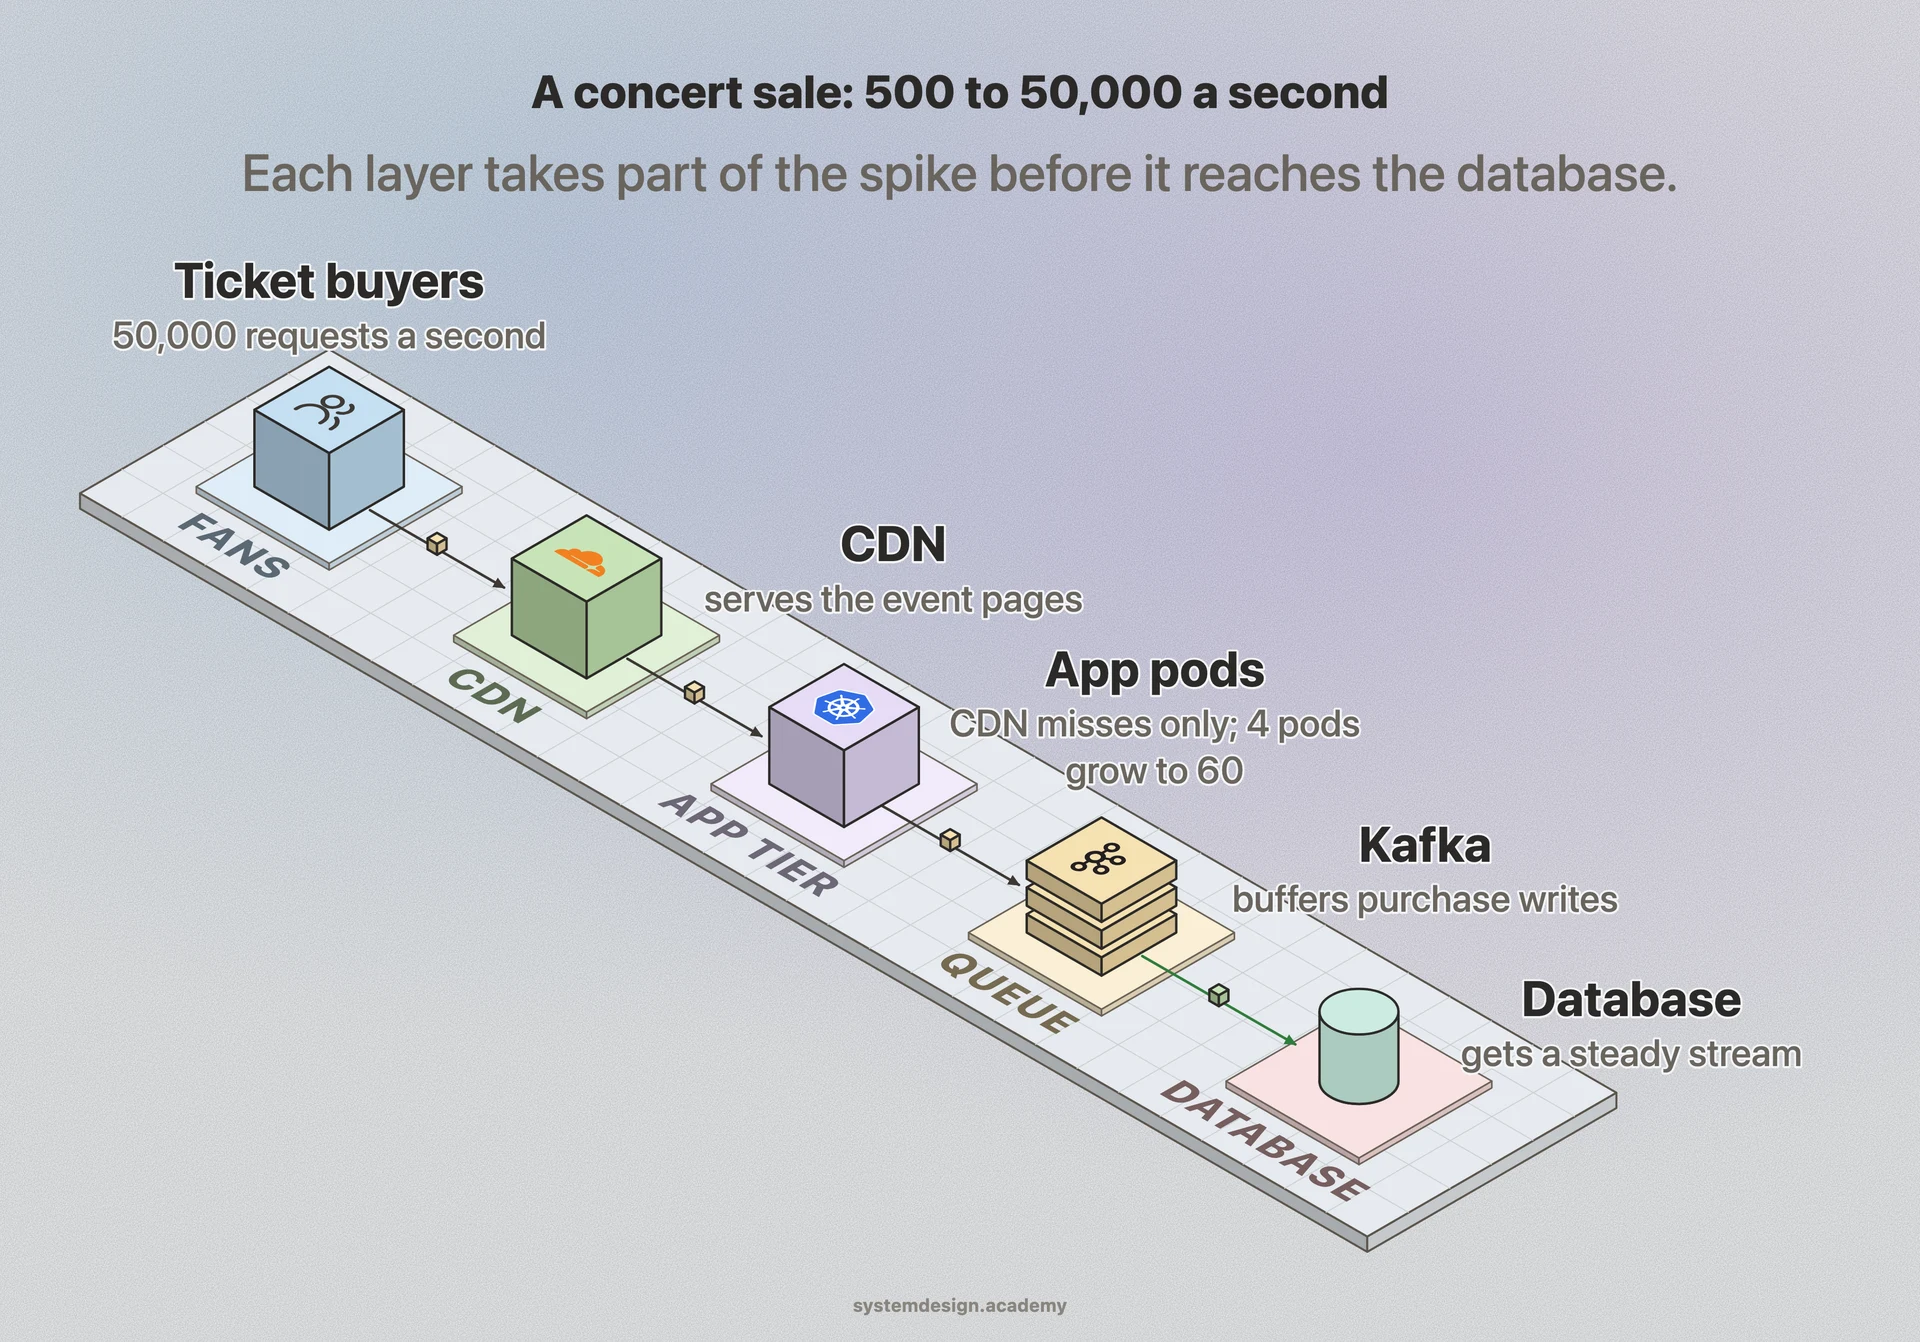
Caching is the cheapest scaling lever. Putting Redis or Memcached in front of the database, or a CDN like Cloudflare in front of static content, removes a huge fraction of work before it ever reaches the slow components. A cache hit ratio of 90 percent means the database only sees one tenth of the traffic.
The enemy of scaling is the shared bottleneck. Amdahl's law captures this: if even 5 percent of the work must happen on a single serialized resource, adding machines past a point gives almost nothing. Real scaling work is mostly hunting down and removing those single chokepoints.