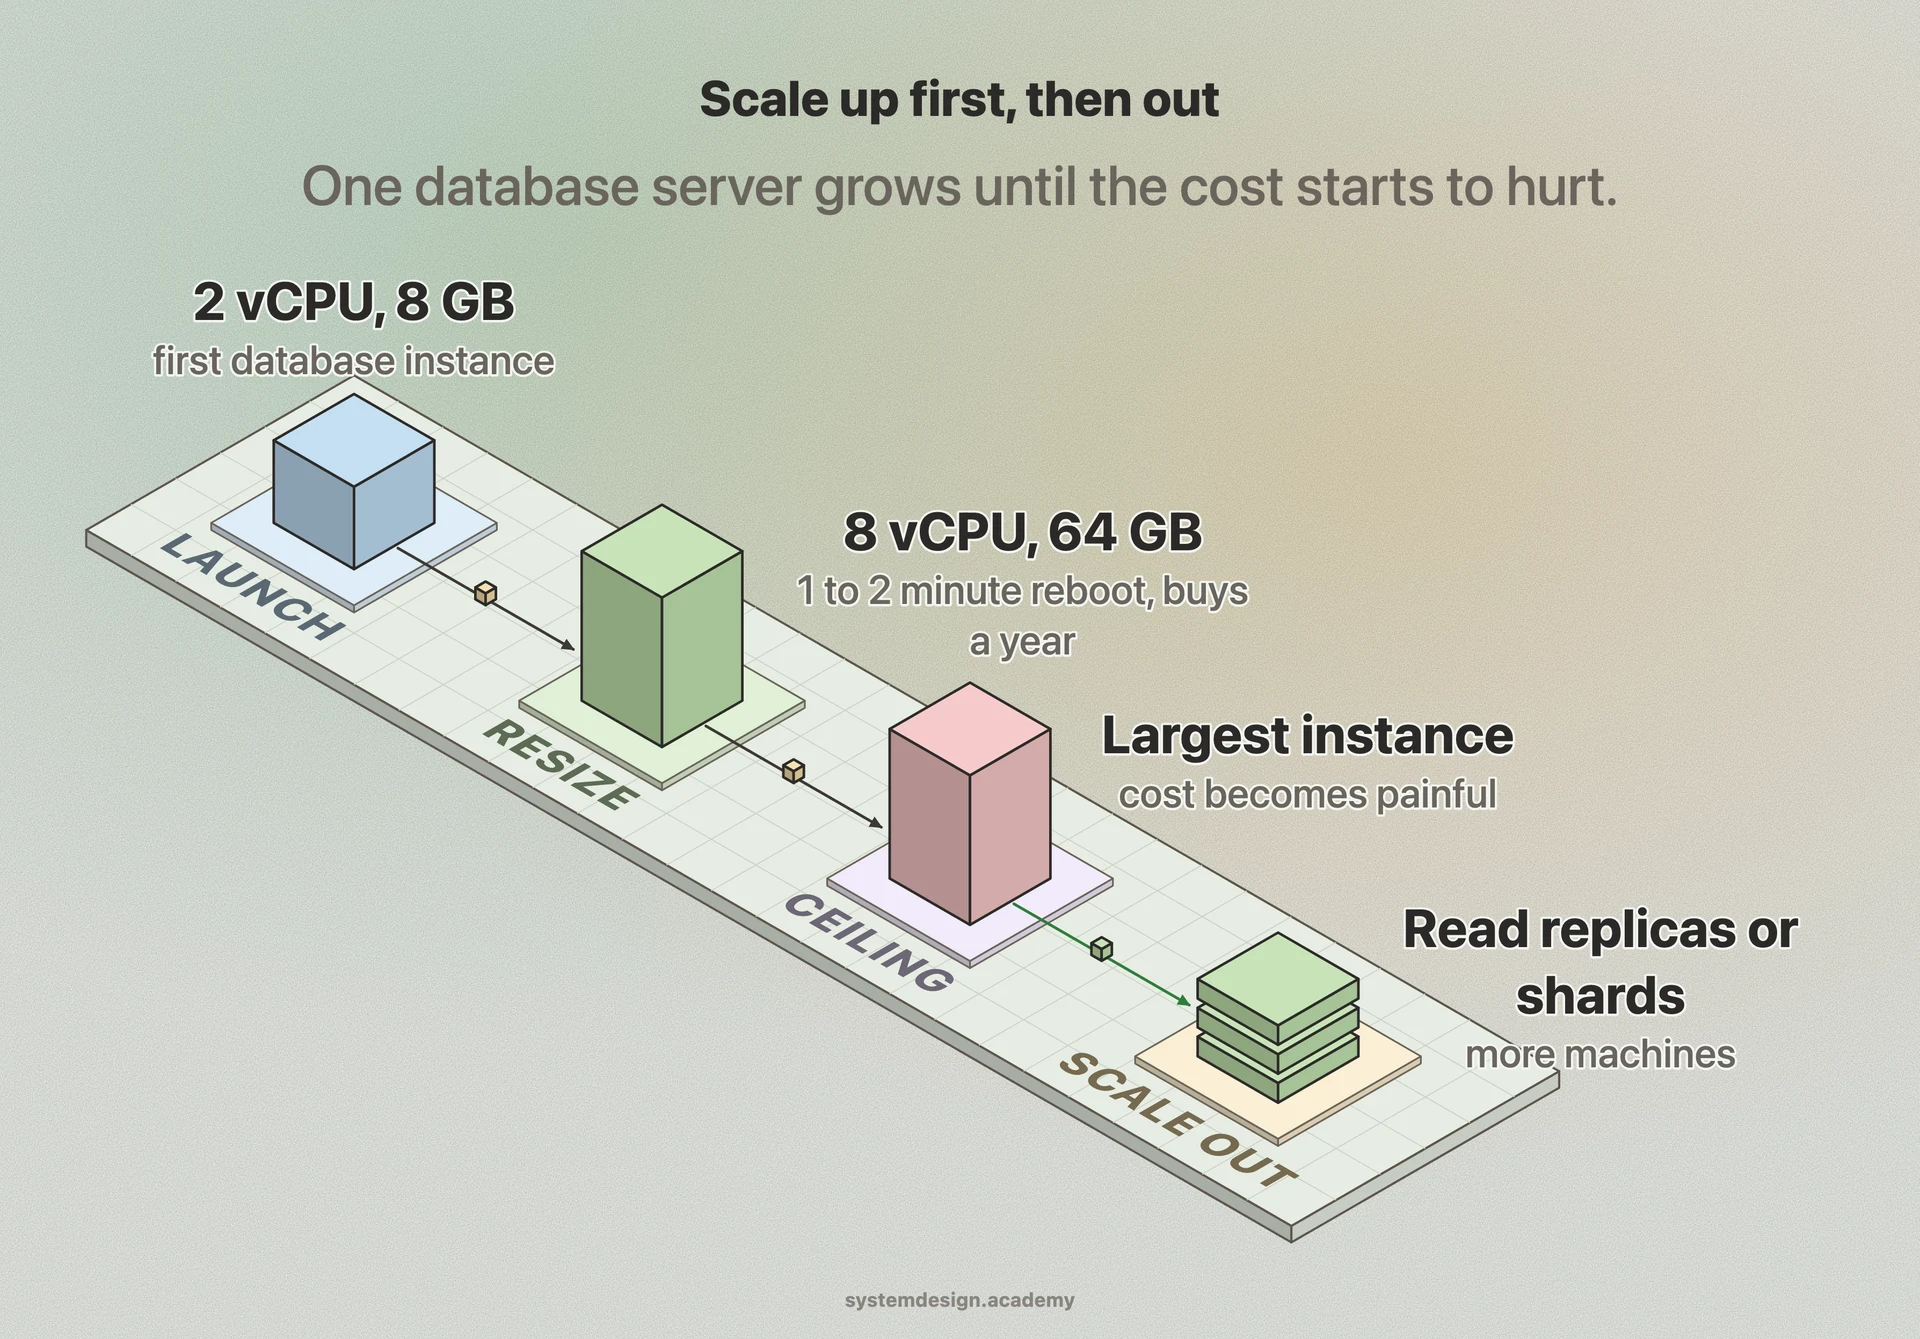
Vertical scaling is the right first move when your system is hard to split across machines. Relational databases are the classic example: keeping all the data on one primary avoids the complexity of sharding, distributed joins, and cross-node transactions. Many companies run a single large Postgres or MySQL primary into the millions of users before they ever shard, precisely because scaling up is so much simpler.
The upside is simplicity. There is no load balancer to configure, no data partitioning, no consistency problems between nodes, and the code stays exactly the same. For a small team this saves enormous engineering time.
The downsides are real. You have a hard ceiling once you reach the biggest machine available. Cost grows faster than capacity at the high end. And a single big server is a single point of failure: if it goes down, everything goes down, so you still need a replica for availability even though that replica does not add scaling capacity. Most mature systems use vertical scaling as the easy lever first, then move to horizontal scaling once one machine is no longer enough or no longer cost-effective.