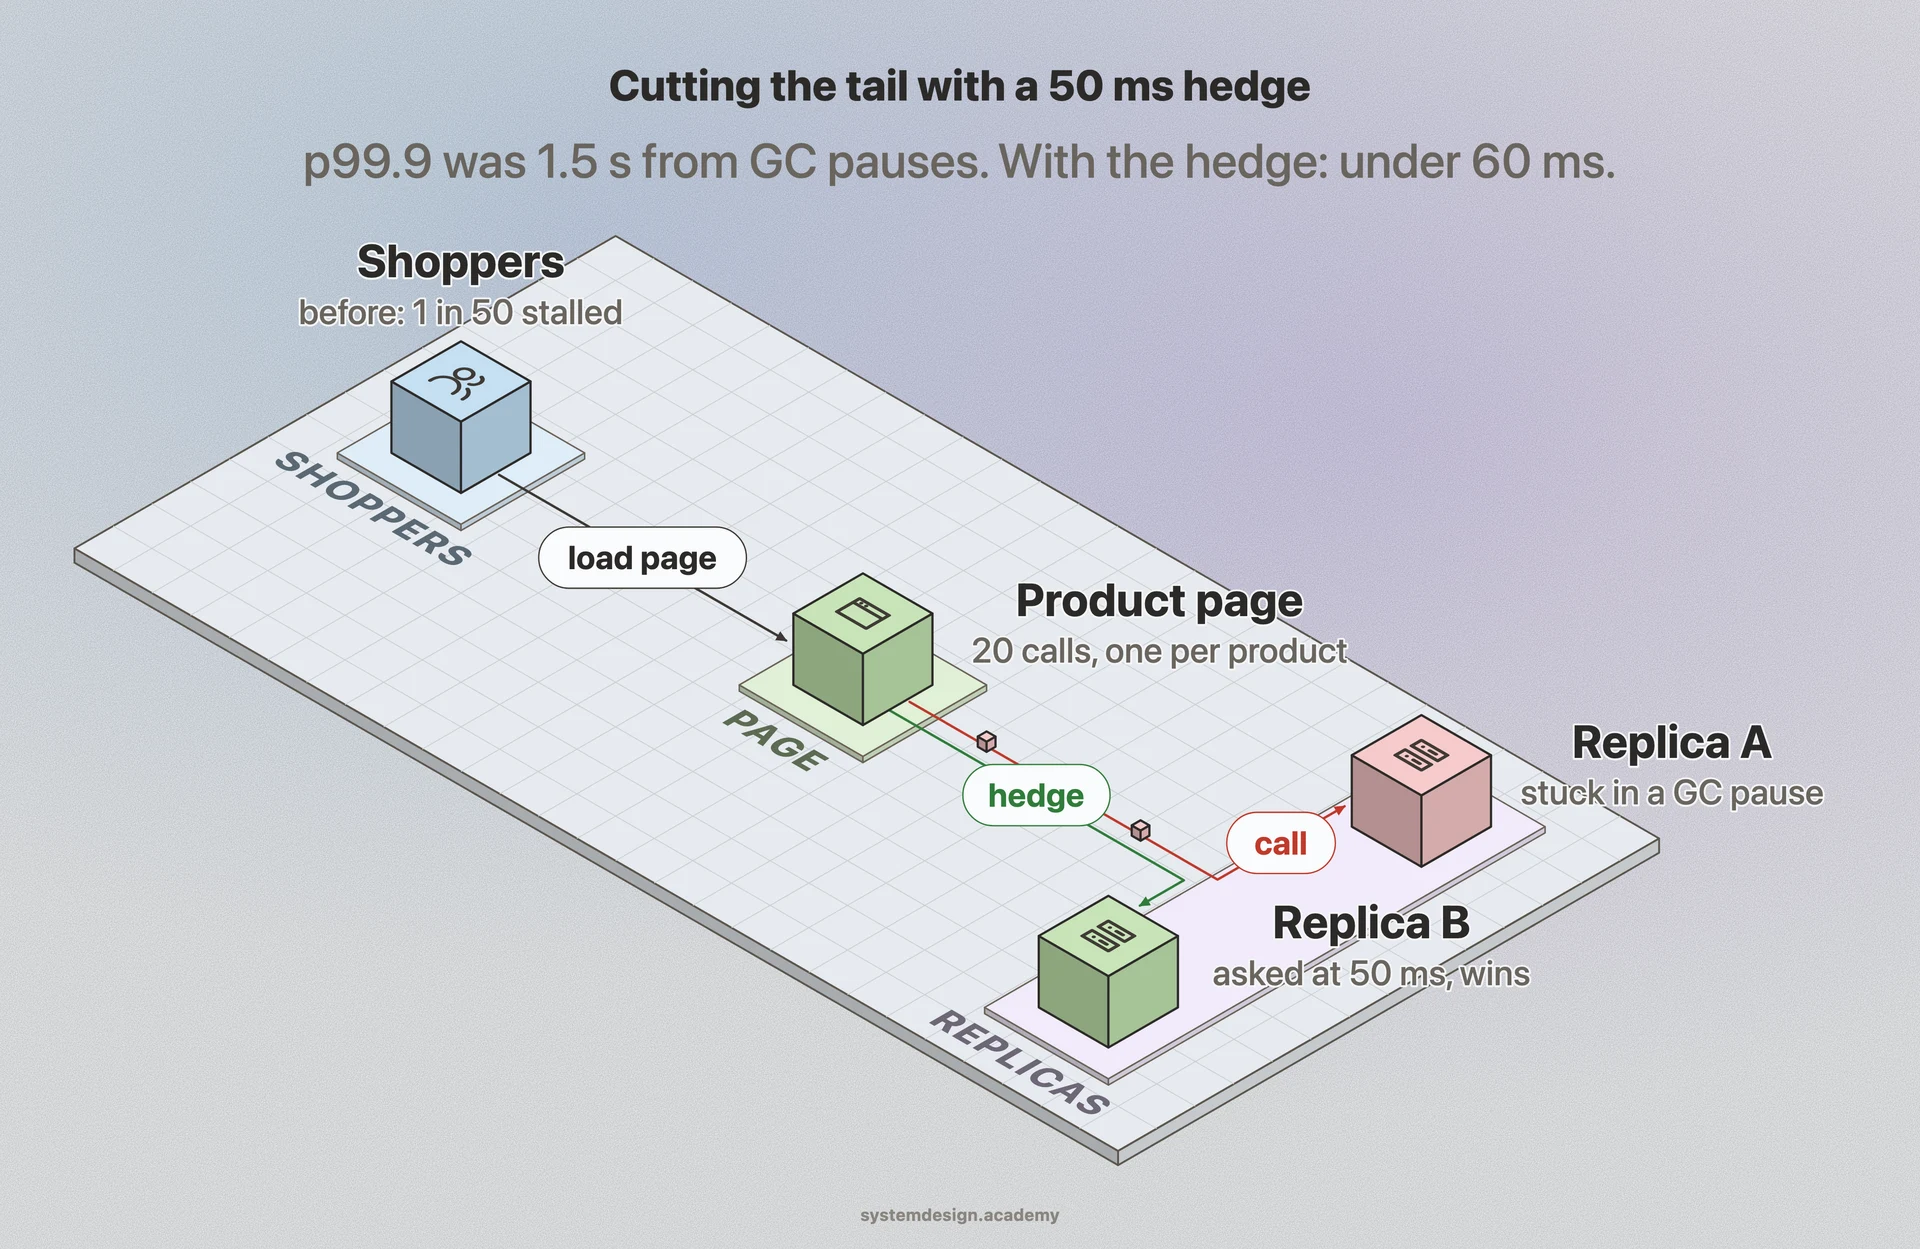
The tail is made of rare events that pile up. A single request can get unlucky and hit a garbage collection pause, a cold cache miss, a slow disk seek, a noisy neighbor on shared hardware, a lock it has to wait for, a TCP retransmit, or a server that just queued too many requests at once. None of these happen often, but with enough traffic they happen constantly to someone.
Fan-out makes it worse. If one user request triggers 50 parallel backend calls and each backend has a 1 percent chance of a slow response, the odds that at least one of the 50 is slow are about 1 minus 0.99 to the 50th power, roughly 40 percent. So a backend with a great p99 still produces a terrible end-to-end p99 once you fan out.
Common fixes target these tails directly. Hedged requests send a duplicate call to a second replica after a short delay and take whichever returns first, which Google's Jeff Dean described as cutting p99.9 dramatically. Request timeouts with retries cap how bad a single attempt can get. Load shedding rejects excess work before queues build up. Tuning the garbage collector, adding more replicas to reduce queueing, and isolating slow tenants all chip away at the worst percentiles.