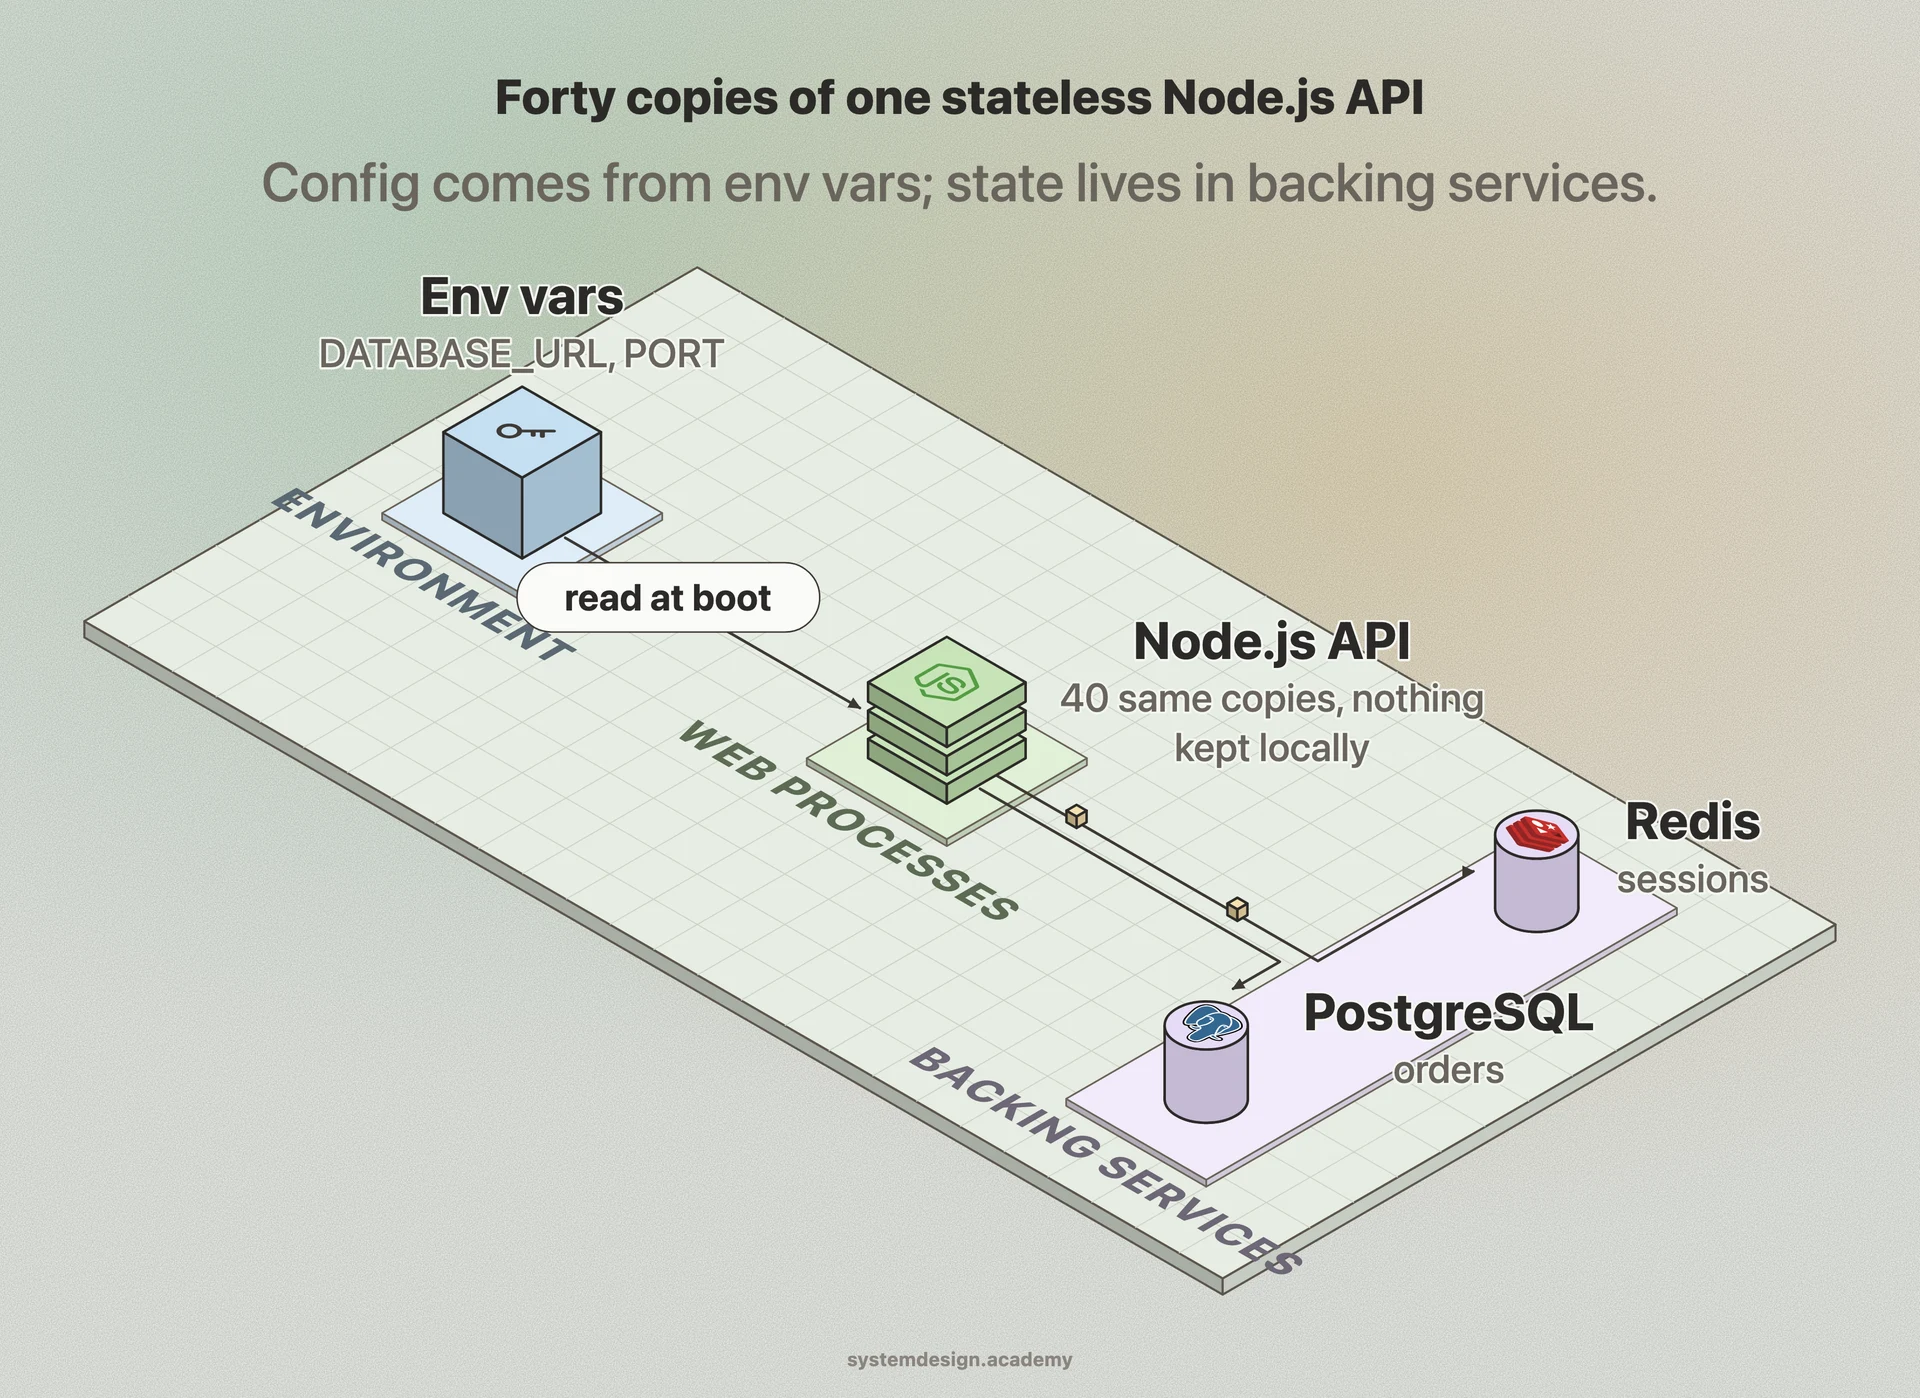
Config in the environment is the factor most people get wrong first. Database URLs, API keys, and feature flags live in environment variables, not in a settings file committed to git. The same build artifact then runs in staging and production unchanged, with only the env vars differing. This is why you set DATABASE_URL in your hosting dashboard instead of editing a .env file you commit.
Stateless processes and backing services go together. Your web process keeps nothing important in memory or on local disk between requests. User sessions go to Redis, uploaded files go to S3, and rows go to Postgres. Each of those is a backing service attached by a URL in config, so you can swap a local Postgres for Amazon RDS by changing one variable with no code change.
Disposability and the process model are what make scaling cheap. Because every process is stateless and starts in a few seconds, the platform scales by running more copies (horizontal scaling) rather than buying a bigger box. Graceful shutdown means a process catches SIGTERM, finishes its current request, and exits, so a deploy or autoscale event never drops work in flight.
Logs as event streams means the app writes plain lines to stdout and never manages log files itself. The platform captures that stream and routes it to a tool like Datadog or an ELK stack. The app does not know or care where its logs end up.