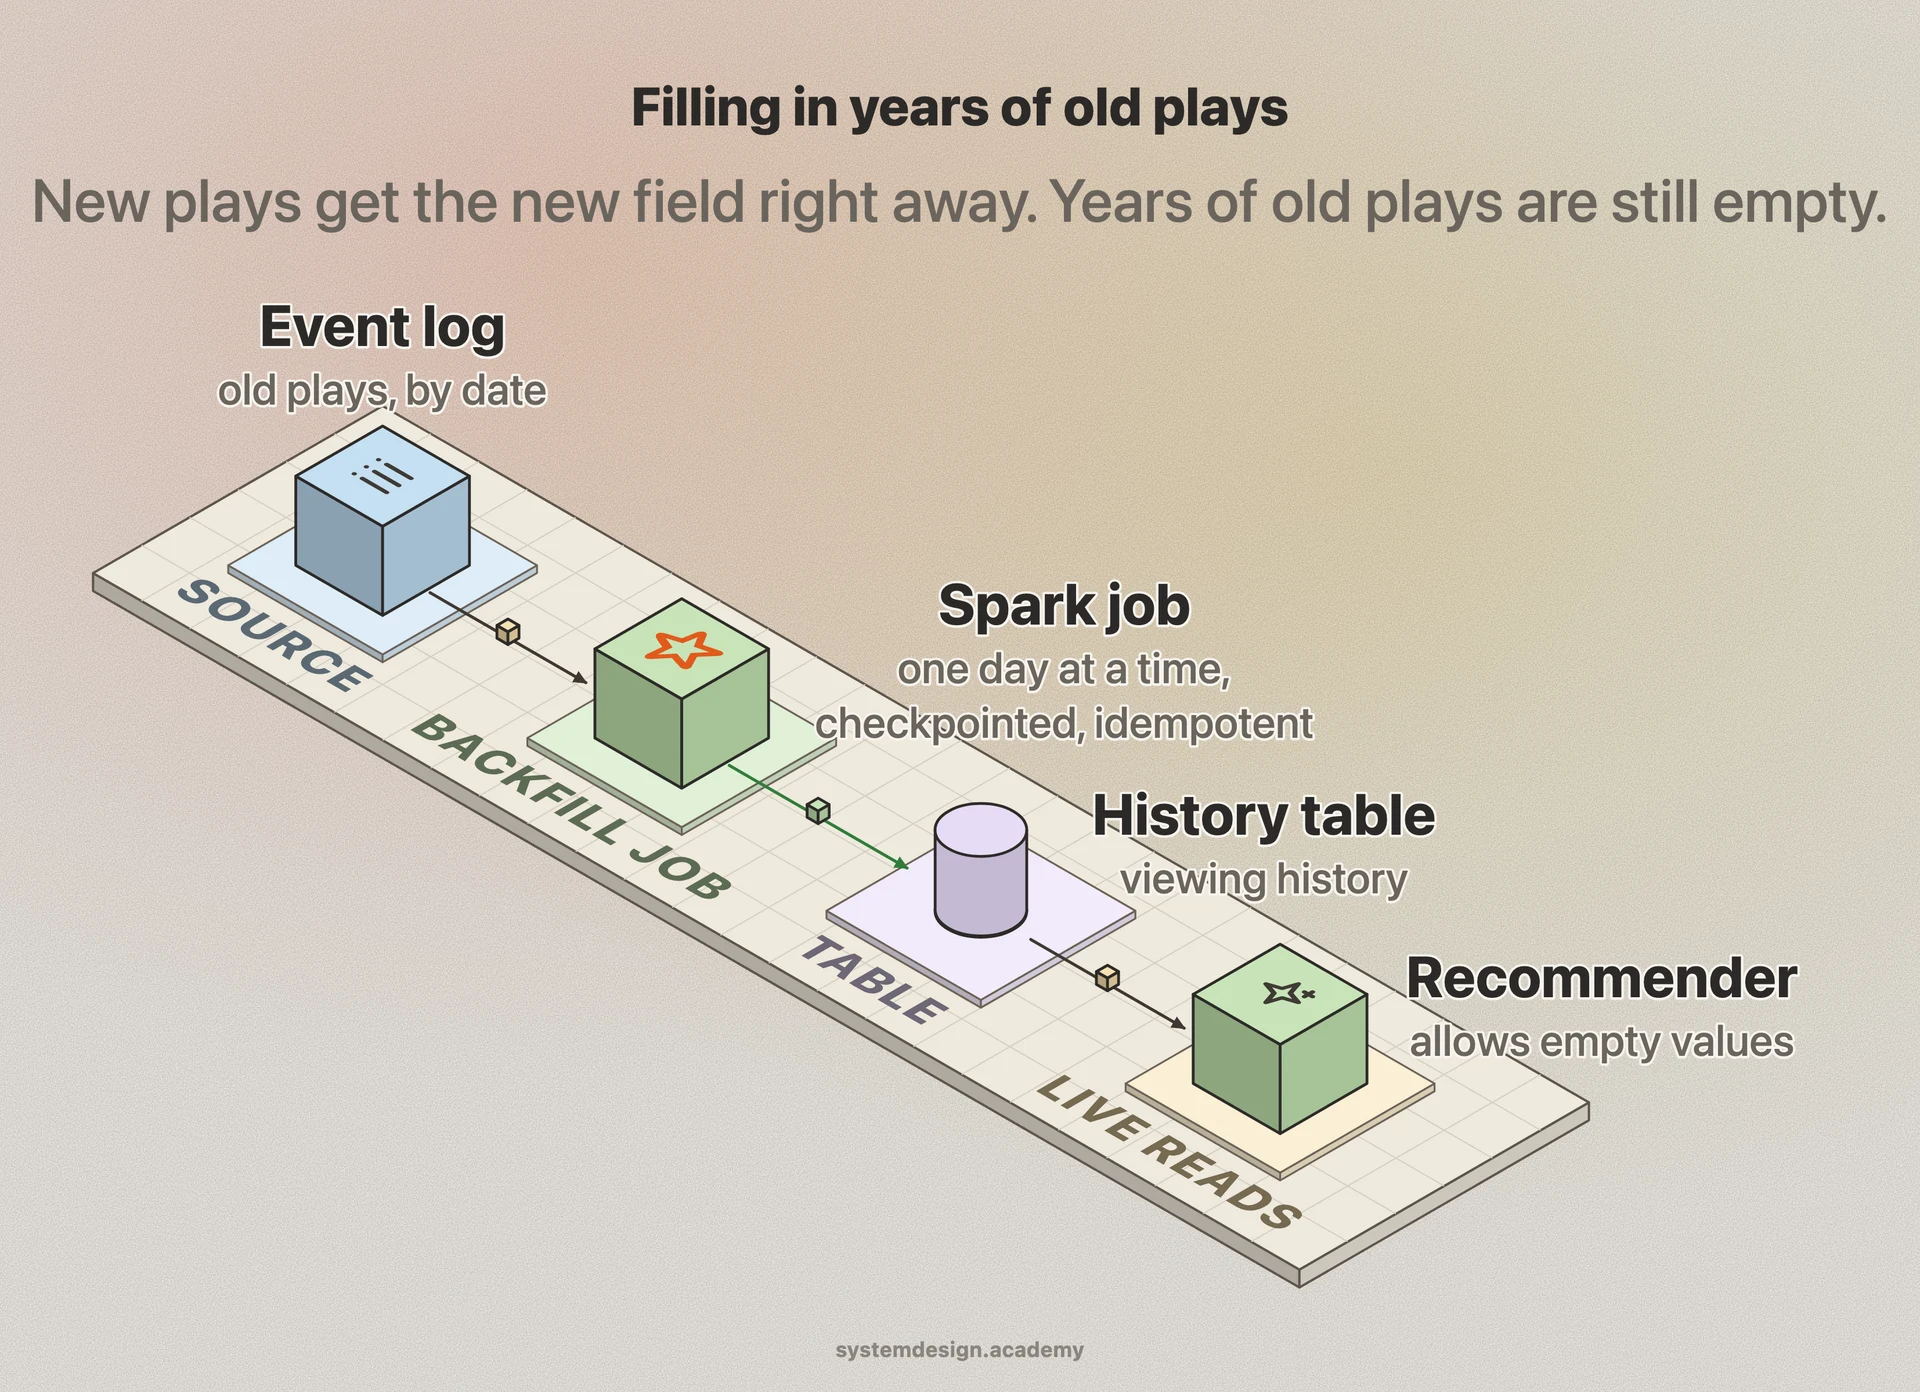
Almost every backfill is a loop over historical records in bounded chunks. You select a batch (say 5,000 rows or one day of events), transform each record with the new logic, write the result, record where you stopped, then move to the next batch. Chunking keeps memory flat and stops a single huge transaction from locking the table or blowing up the database.
Idempotency is the property you cannot skip. A backfill of millions of rows will get interrupted, retried, or run twice. Each write must produce the same end state no matter how many times it runs, which usually means UPSERT semantics or a 'process only rows where the new column is still NULL' filter. You also store a cursor or checkpoint (last id, last timestamp) so a restart resumes instead of starting over.
Throttling matters because the backfill shares the same database and message queue as live traffic. Teams cap the job's rate, run it during off-peak hours, target a read replica where possible, and sleep between batches so production latency does not spike. A common mistake is letting an unthrottled backfill saturate disk IO and take the live service down with it.
For very large jobs the work is fanned out across many workers using a framework like Apache Spark, a distributed queue, or a partitioned set of tasks, each owning a slice of the id or date range so they run in parallel without overlapping.