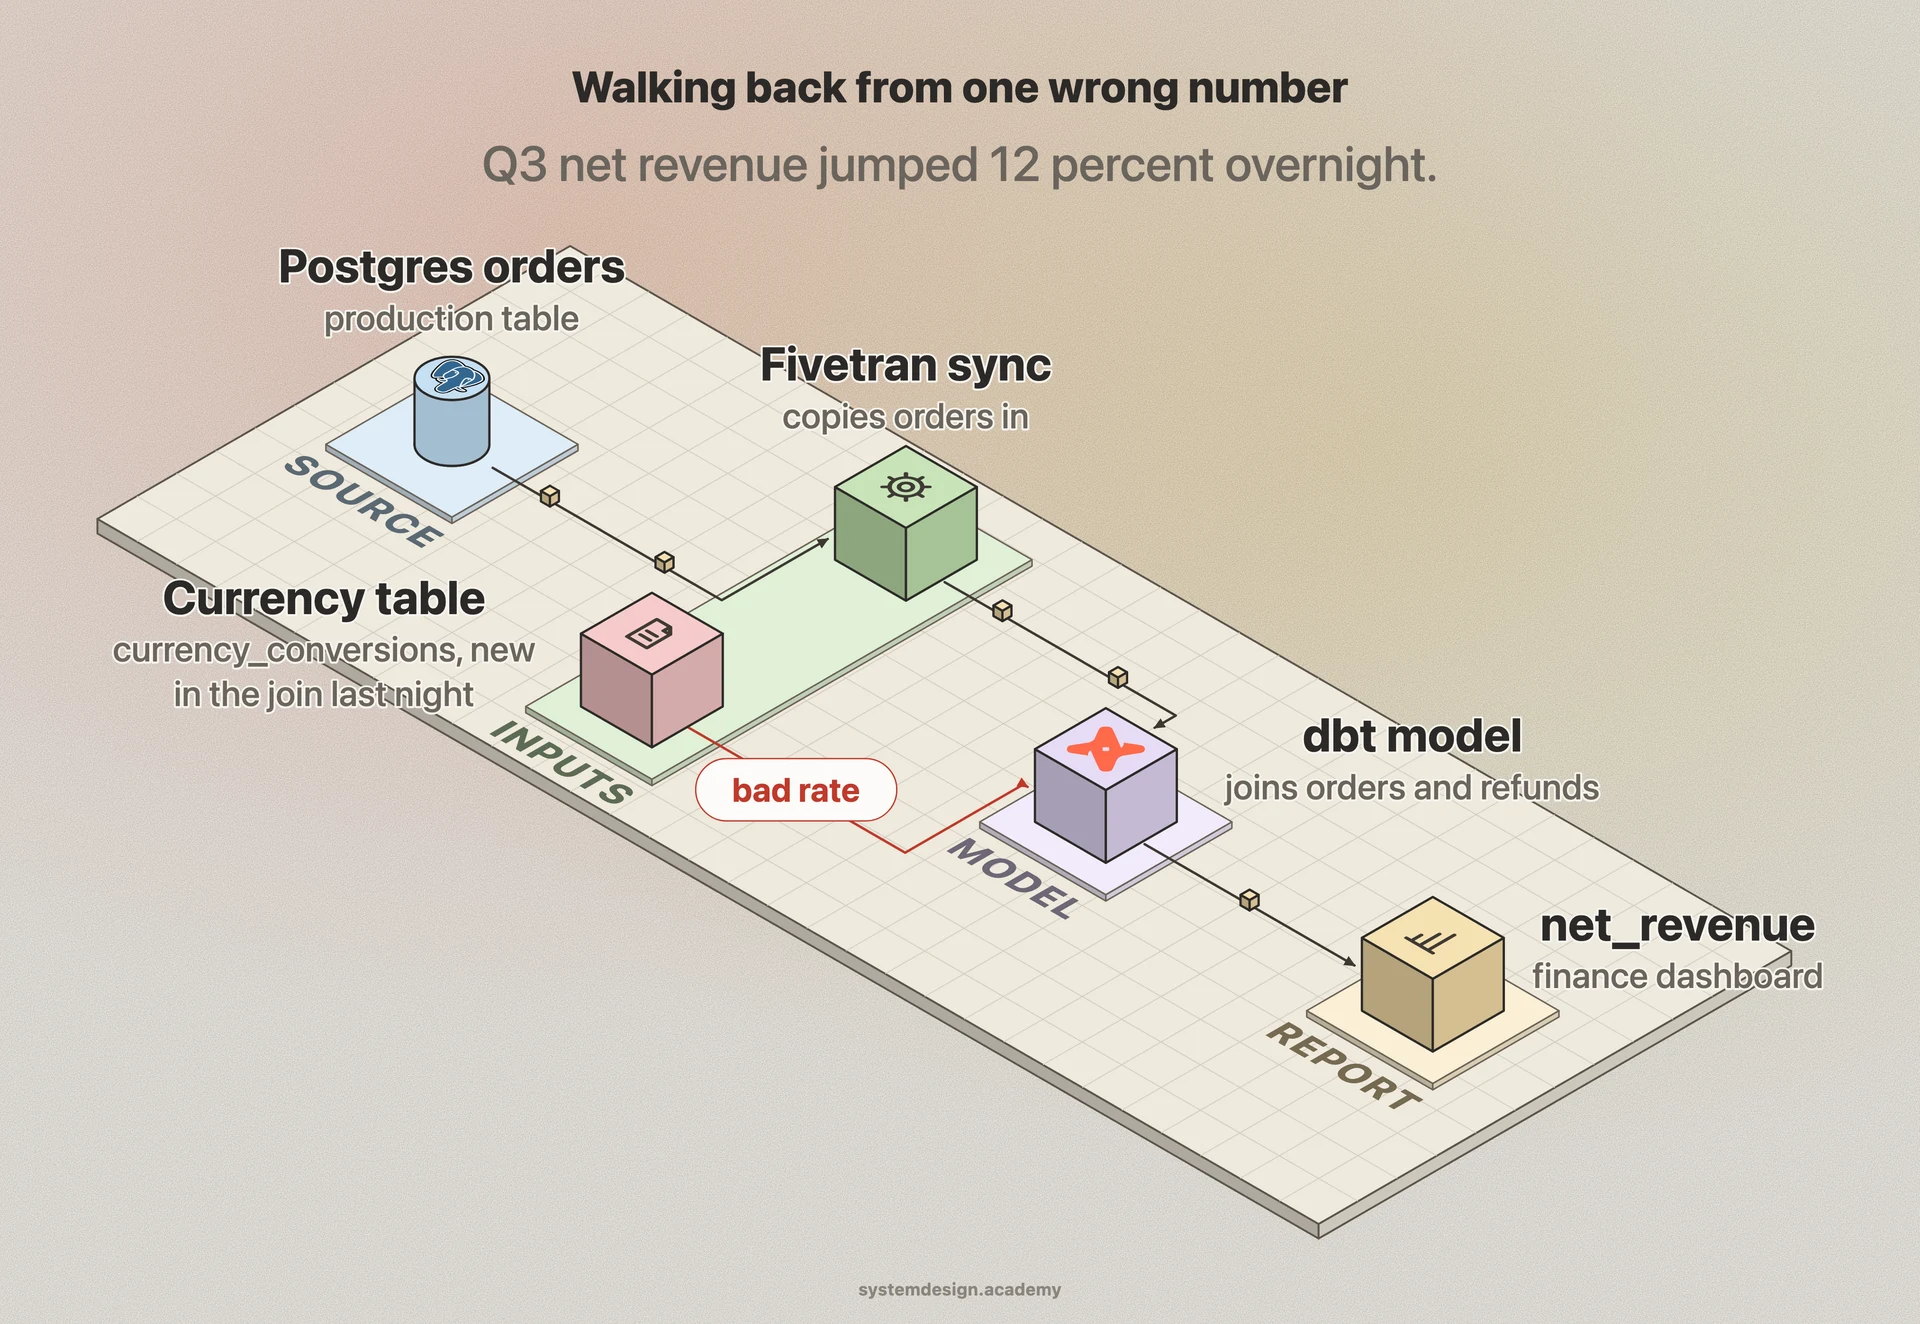
There are three ways to build the graph. The most reliable is parsing the actual code. A tool reads every SQL query, dbt model, or Spark job, parses the abstract syntax tree, and extracts which output columns are derived from which input columns. dbt builds model-level lineage automatically from the ref() and source() calls in its models, which is why its lineage is trusted: it comes from the same code that builds the tables, so it cannot drift out of date.
The second way is runtime capture. The pipeline framework emits an event every time a job reads from one dataset and writes to another. OpenLineage is the open standard for this, and Apache Airflow, Spark, and dbt all emit OpenLineage events that a backend like Marquez collects into a graph. This catches what really ran, including dynamic queries that static parsing might miss.
The third way is log scraping, where a tool reads query history from a warehouse like Snowflake or BigQuery and reconstructs lineage from the SQL that was actually executed. It needs no instrumentation, but it only sees queries the warehouse logged and misses transformations that happen outside it, like a Python script that pulls data, reshapes it in pandas, and writes it back.
Whatever the capture method, the result is stored as a directed graph in a metadata store and exposed through a UI where you click a column and see its upstream sources and downstream consumers.