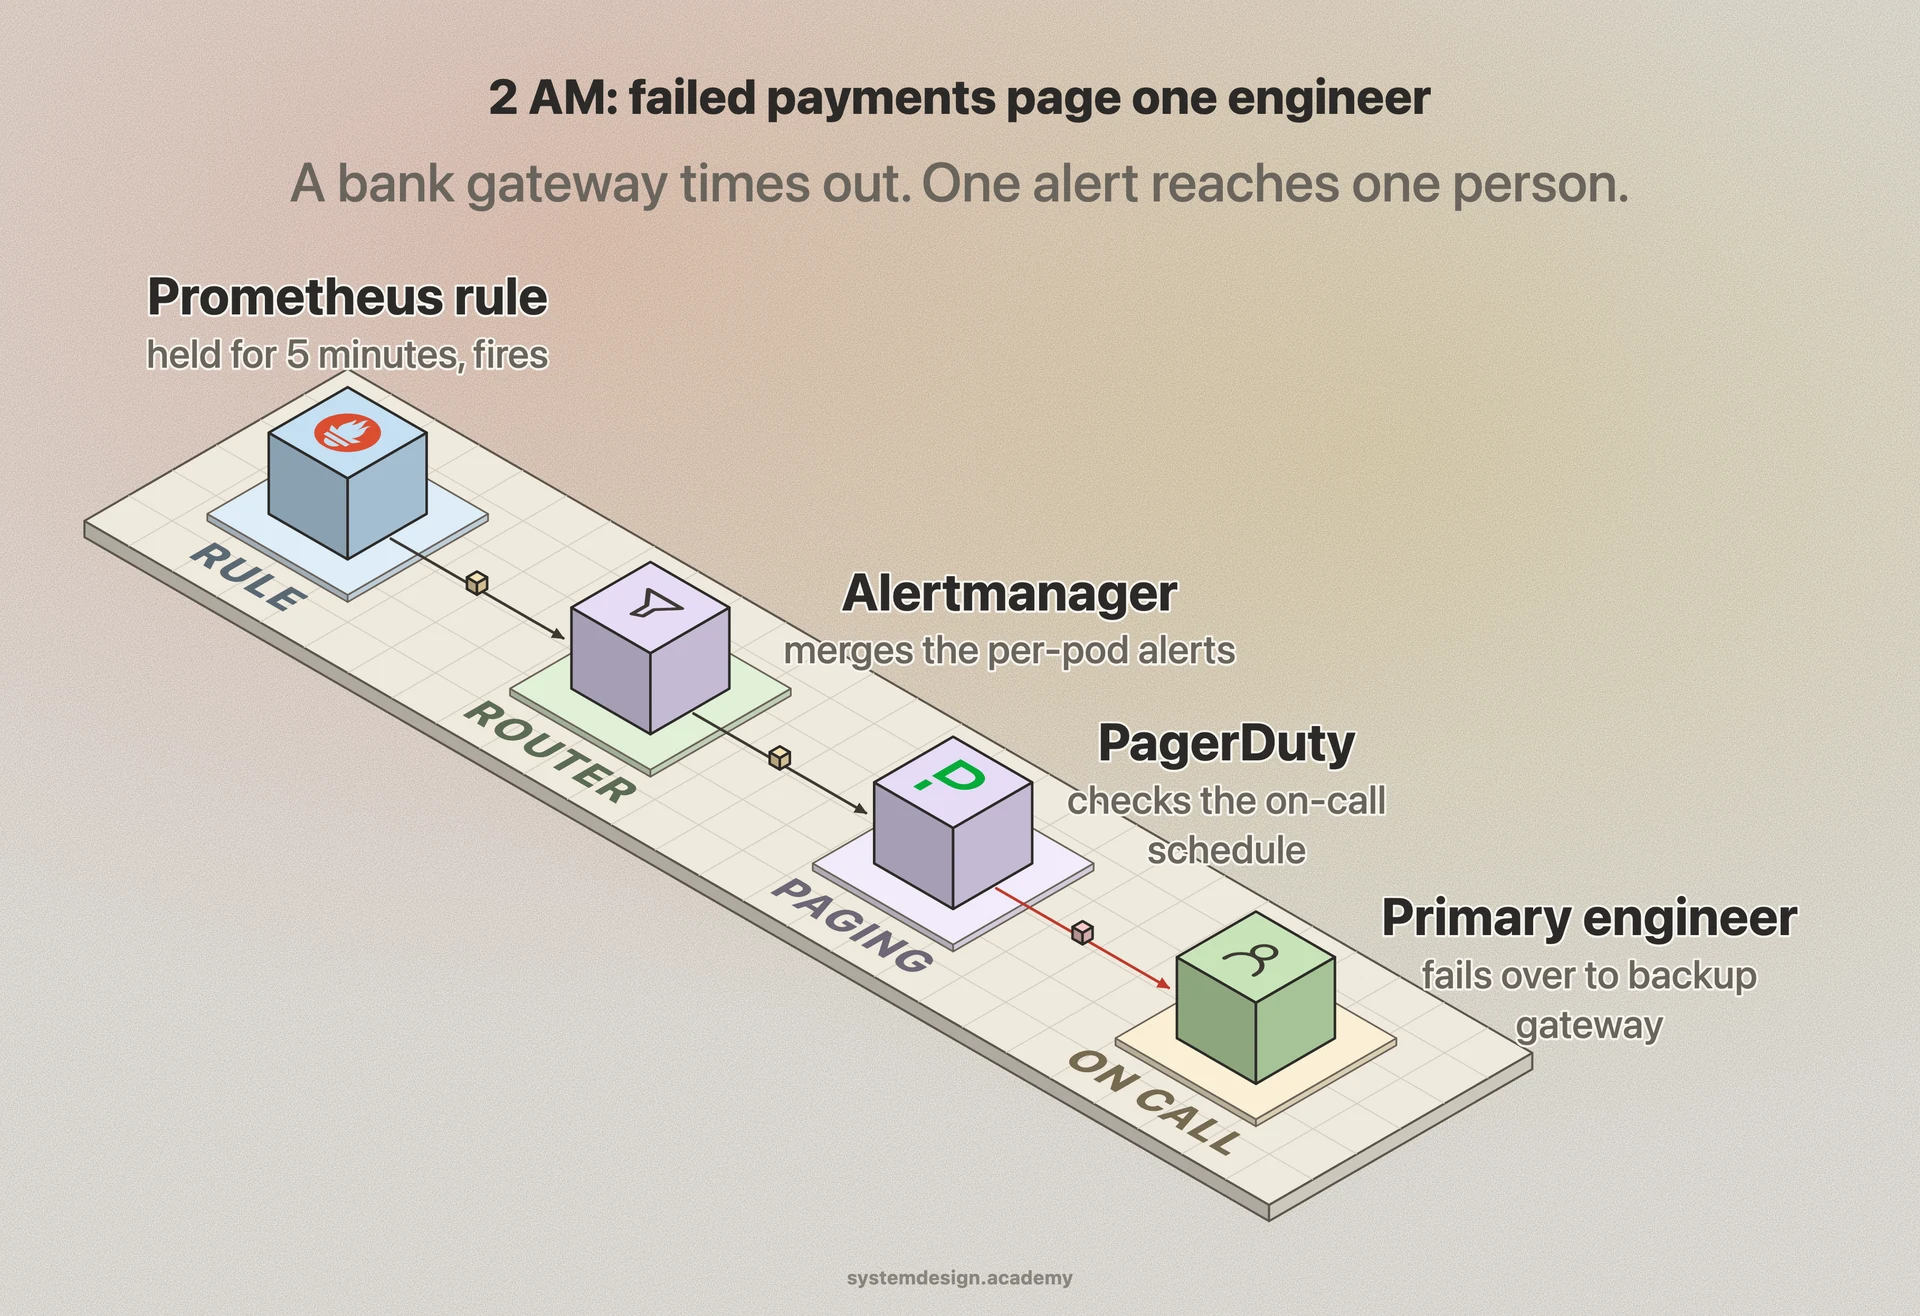
A typical pipeline has three stages. First, a rule engine evaluates conditions on a schedule. In Prometheus this is an alerting rule that runs an expression every 15 to 30 seconds and marks a rule as pending, then firing once the condition has held for the configured `for` duration. The duration matters: it prevents a single noisy data point from paging anyone.
Second, firing alerts are sent to a router. Prometheus ships them to Alertmanager, which groups related alerts together, deduplicates copies coming from many instances, silences known issues during maintenance, and applies inhibition so that a big outage does not also fire 50 child alerts. Datadog, Grafana, and New Relic have their own equivalents built in.
Third, the router hands off to a paging tool such as PagerDuty or Opsgenie. The paging tool owns the on-call schedule, the escalation policy, and the actual phone call, SMS, push, or Slack message. If the first engineer does not acknowledge within, say, 5 minutes, it escalates to the next person, then to the team lead.
Two common rule styles are threshold alerts (latency p99 over 500ms) and rate-of-change or anomaly alerts (traffic dropped 40 percent versus the same hour last week). Threshold rules are simple and predictable; anomaly rules catch problems you did not anticipate but produce more false positives.