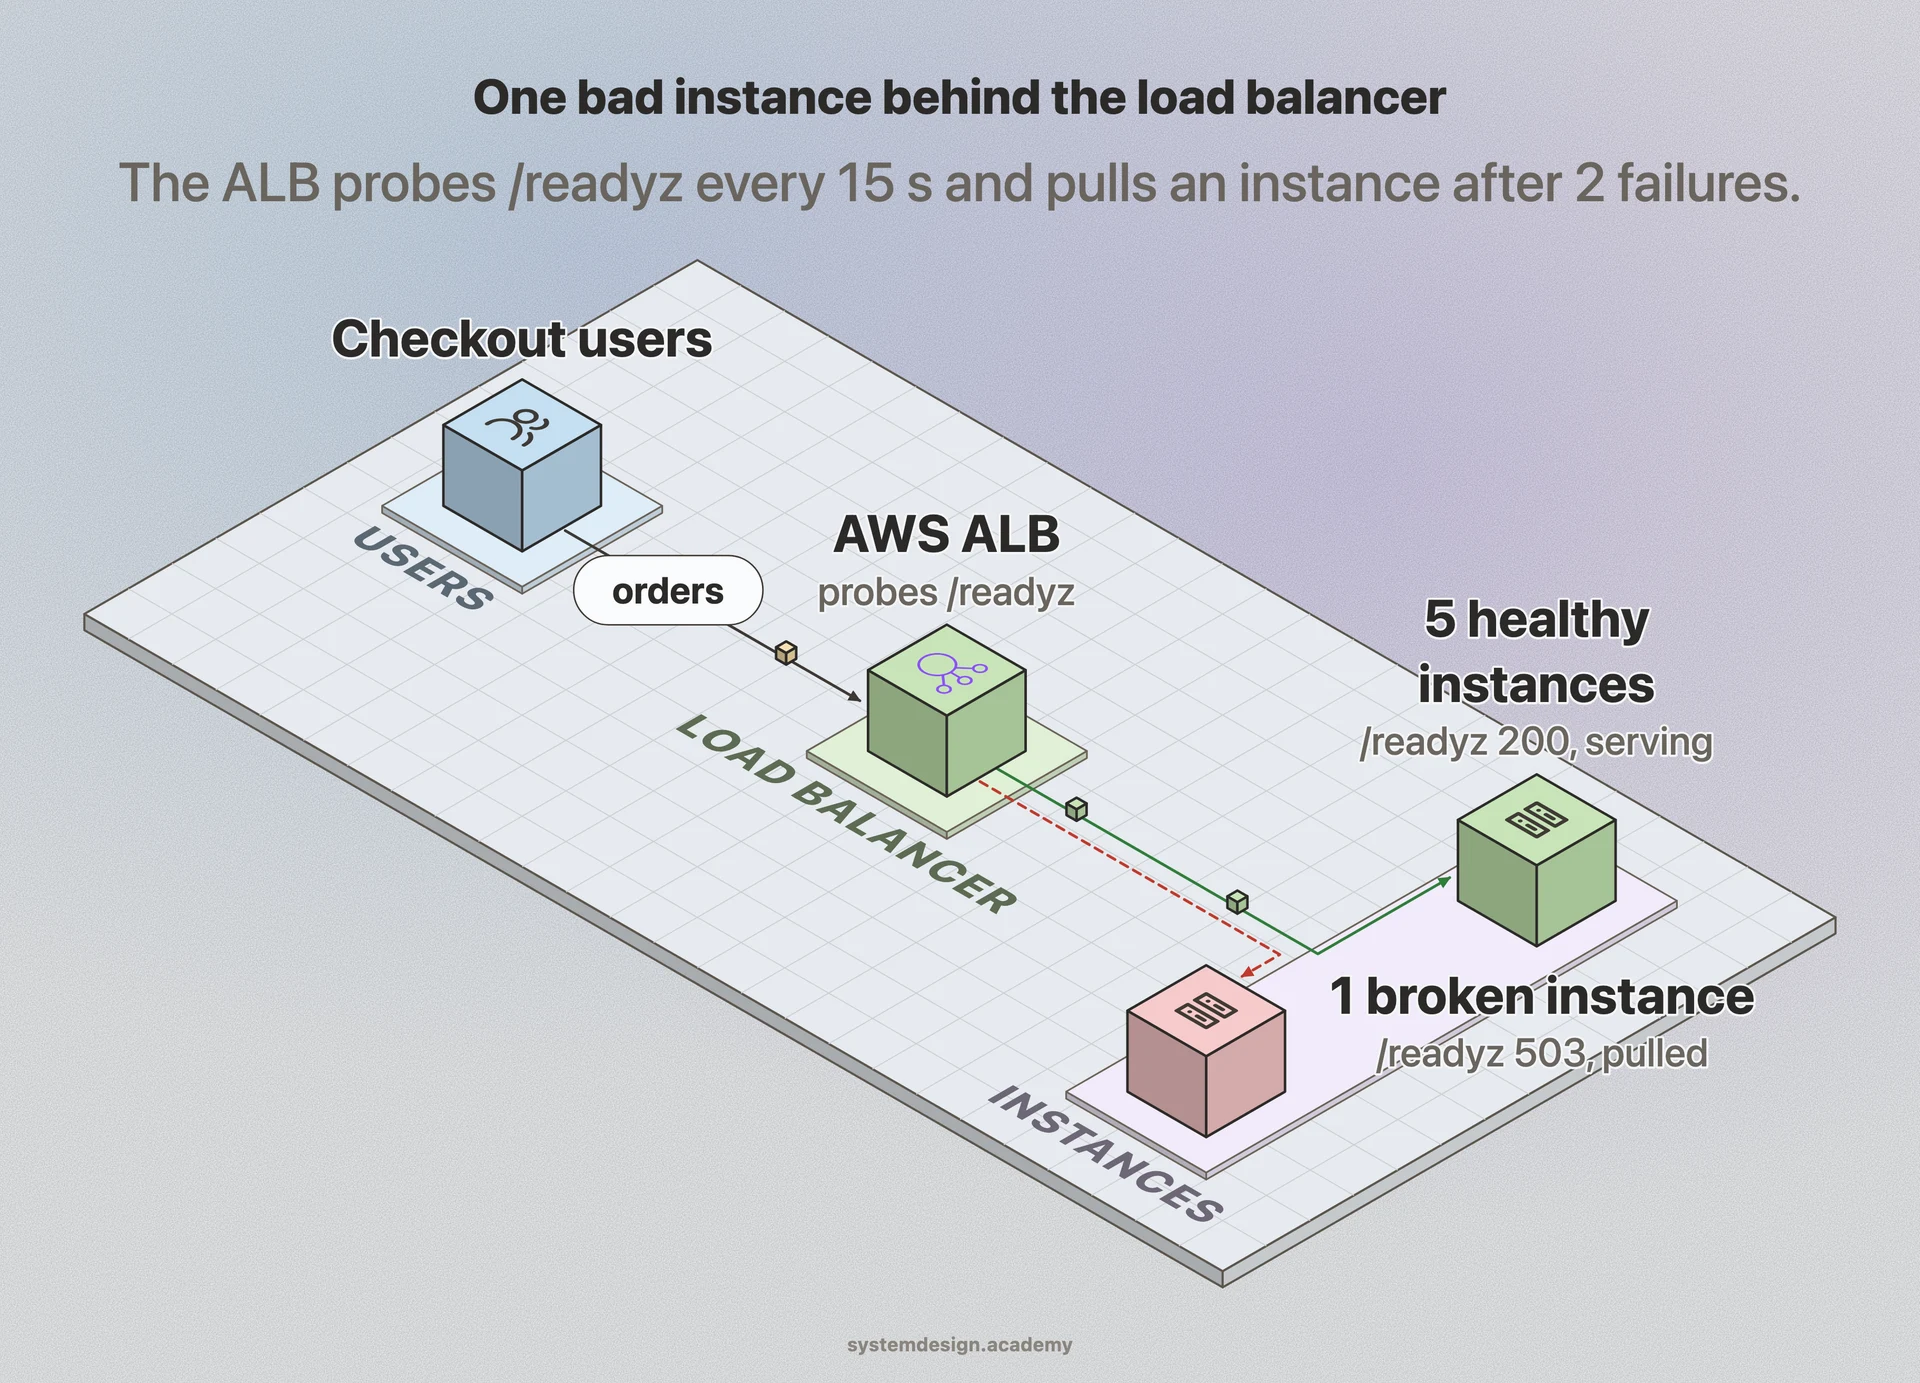
There are two distinct questions, and mixing them up causes outages. Liveness asks: is the process broken and stuck forever? If the answer is yes, the right move is to restart it. Readiness asks: can this instance serve requests right now? If the answer is no, the right move is to stop routing traffic to it but leave it running.
A classic mistake is making liveness depend on a downstream dependency like the database. If the database has a brief hiccup, every instance fails its liveness check at once, Kubernetes restarts all of them, and now you have a thundering herd of cold processes all hitting the recovering database. The database never gets a chance to recover. Liveness should only test whether the process itself is wedged.
Readiness is where dependency checks belong. A freshly started service might need 10 seconds to warm a cache or open a connection pool before it should take traffic. The readiness probe stays red during that window so the load balancer holds back, then flips green once the instance is genuinely ready.
There is also a startup probe in Kubernetes for slow-booting apps. It gives a long grace period before liveness kicks in, so a service that takes 90 seconds to start is not killed at second 30.