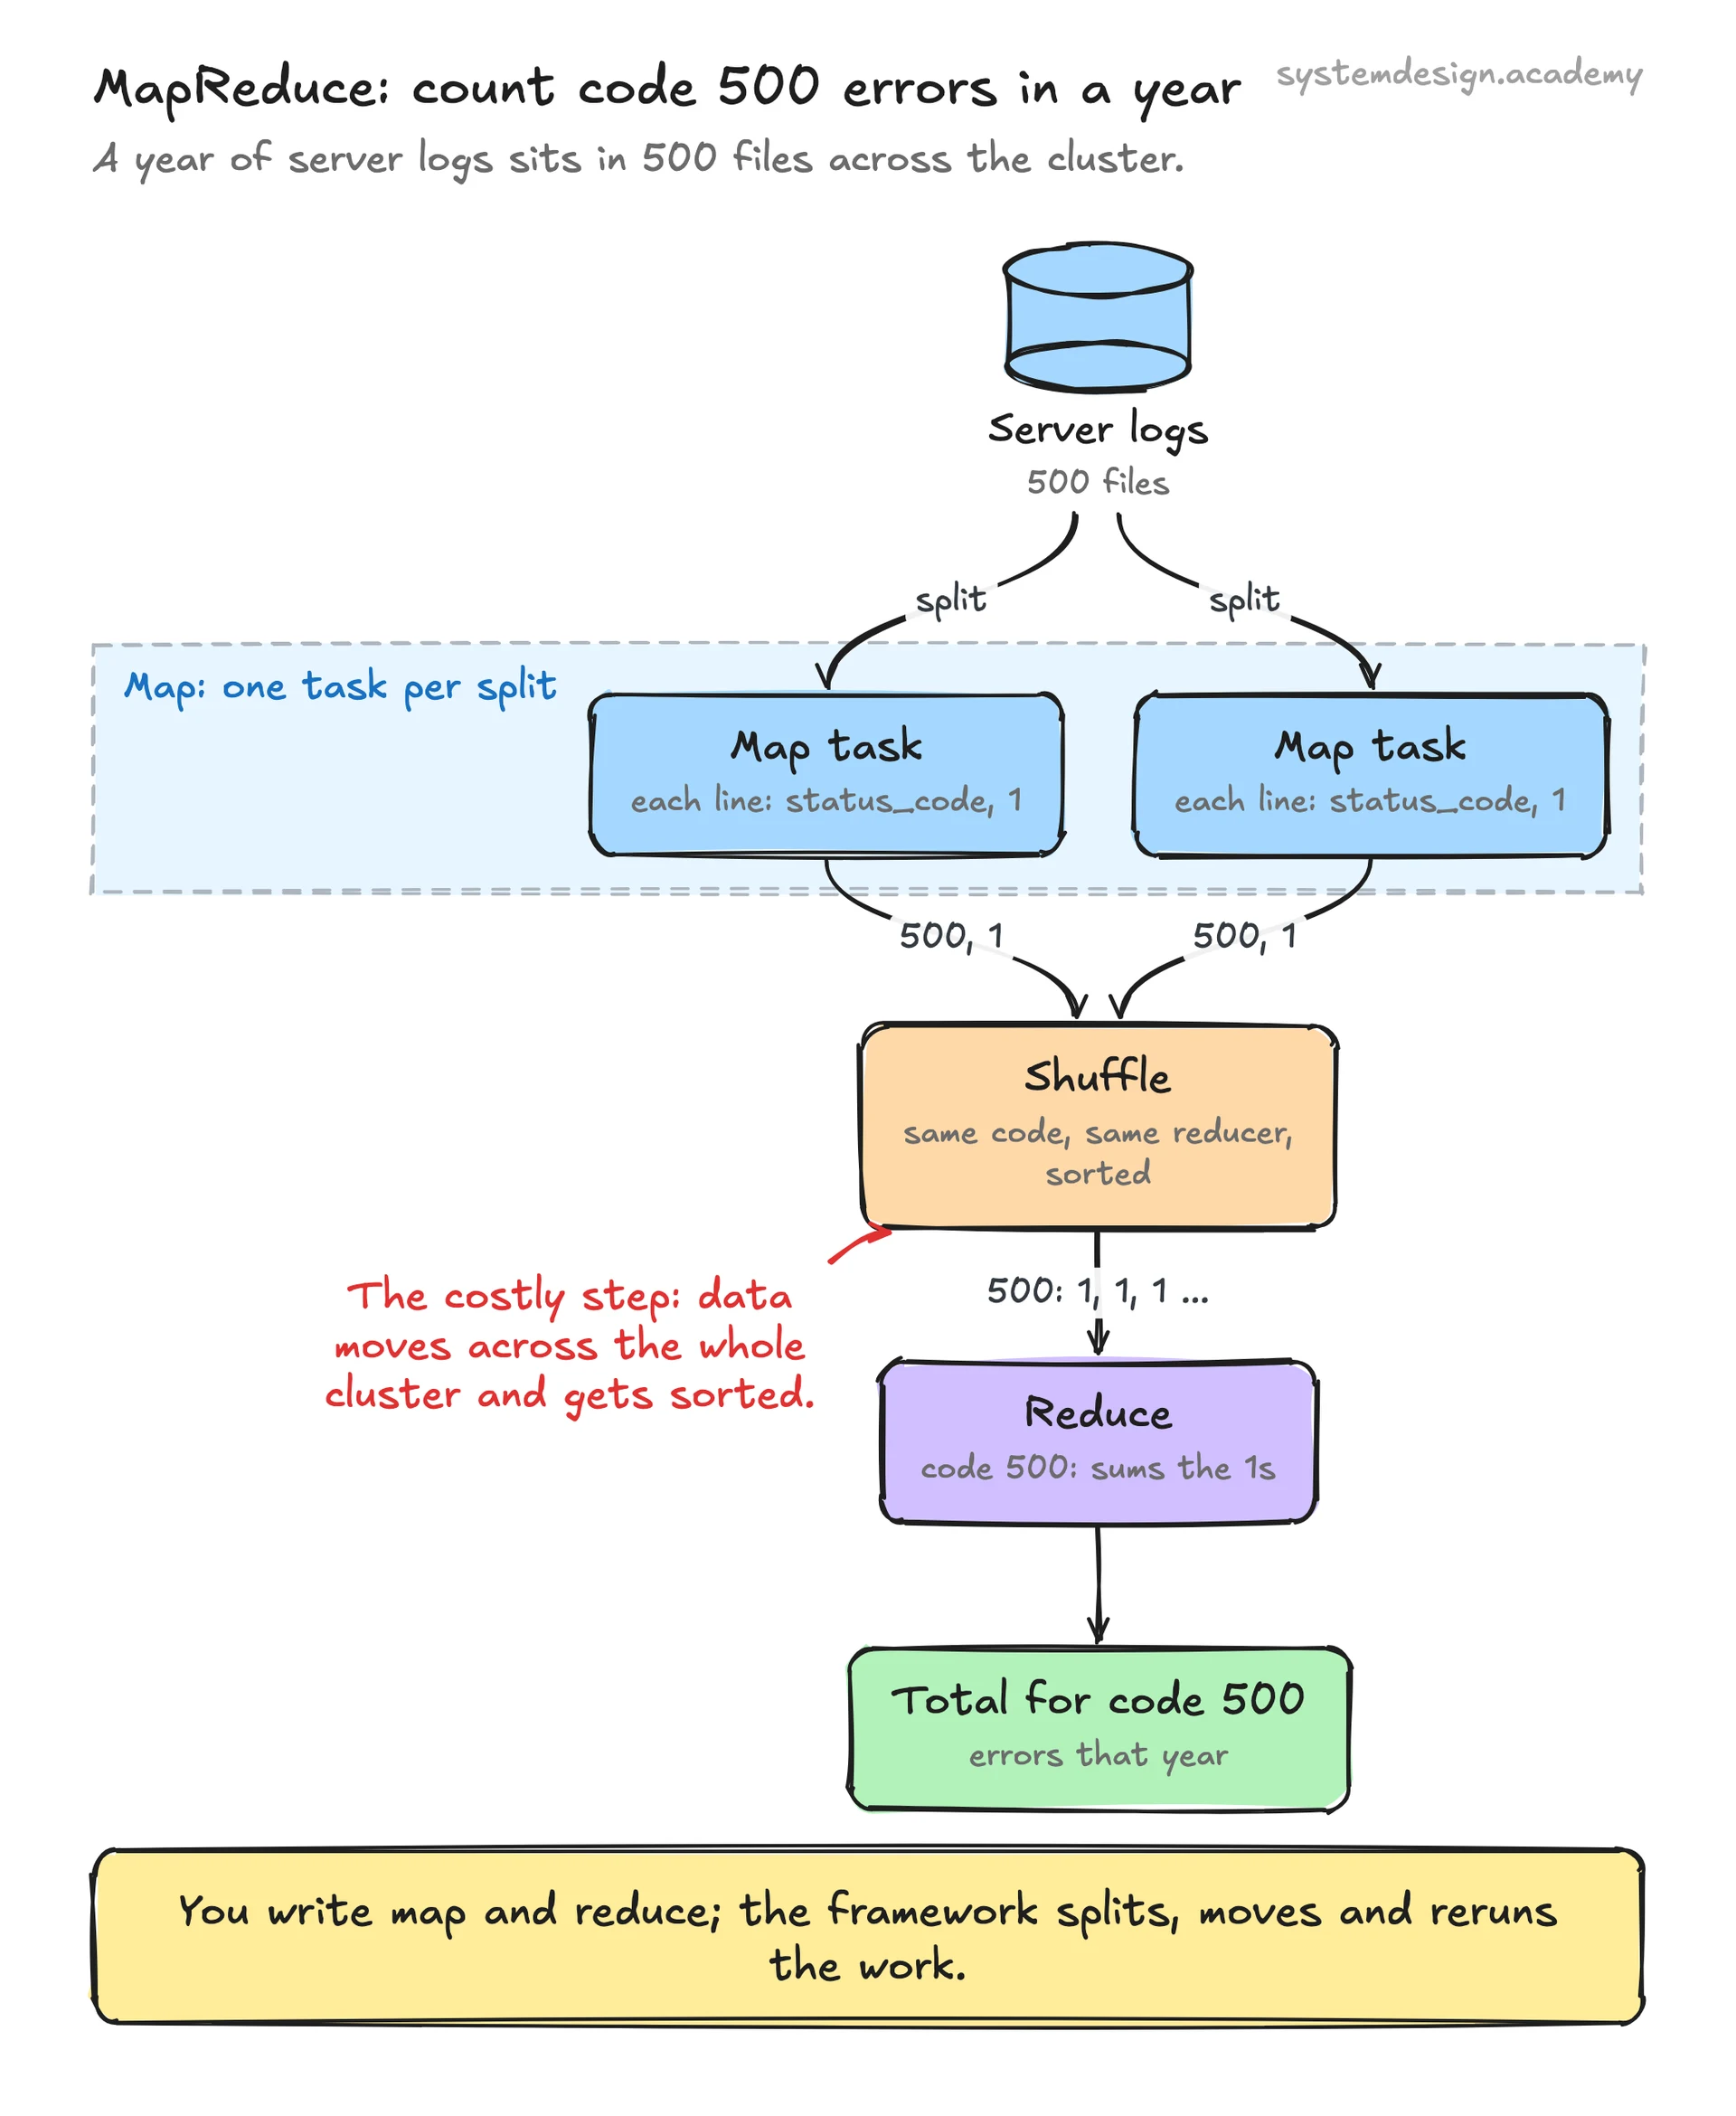
MapReduce fits large batch jobs where you scan most of a huge dataset once and do not need an answer in seconds: nightly ETL, log aggregation, training-data preparation, and rebuilding search or recommendation indexes. It shines when the work is embarrassingly parallel and the input is far too big for one machine.
The cost is latency and rigidity. Every job writes intermediate results to disk and reads them back, so even simple jobs take minutes, and a multi-step pipeline pays that disk and shuffle cost at every stage. It is a poor fit for low-latency queries, for iterative algorithms like many machine-learning trainers that loop over the same data hundreds of times, and for anything interactive.
Those weaknesses are why Apache Spark largely replaced raw MapReduce for new work. Spark keeps intermediate data in memory and expresses pipelines as a graph instead of forcing a disk write between every map and reduce, which makes iterative and interactive jobs much faster. The MapReduce model is still worth understanding because its ideas, keyed parallelism, shuffle, and fault tolerance through re-execution, live on inside Spark, Flink, and most batch engines.