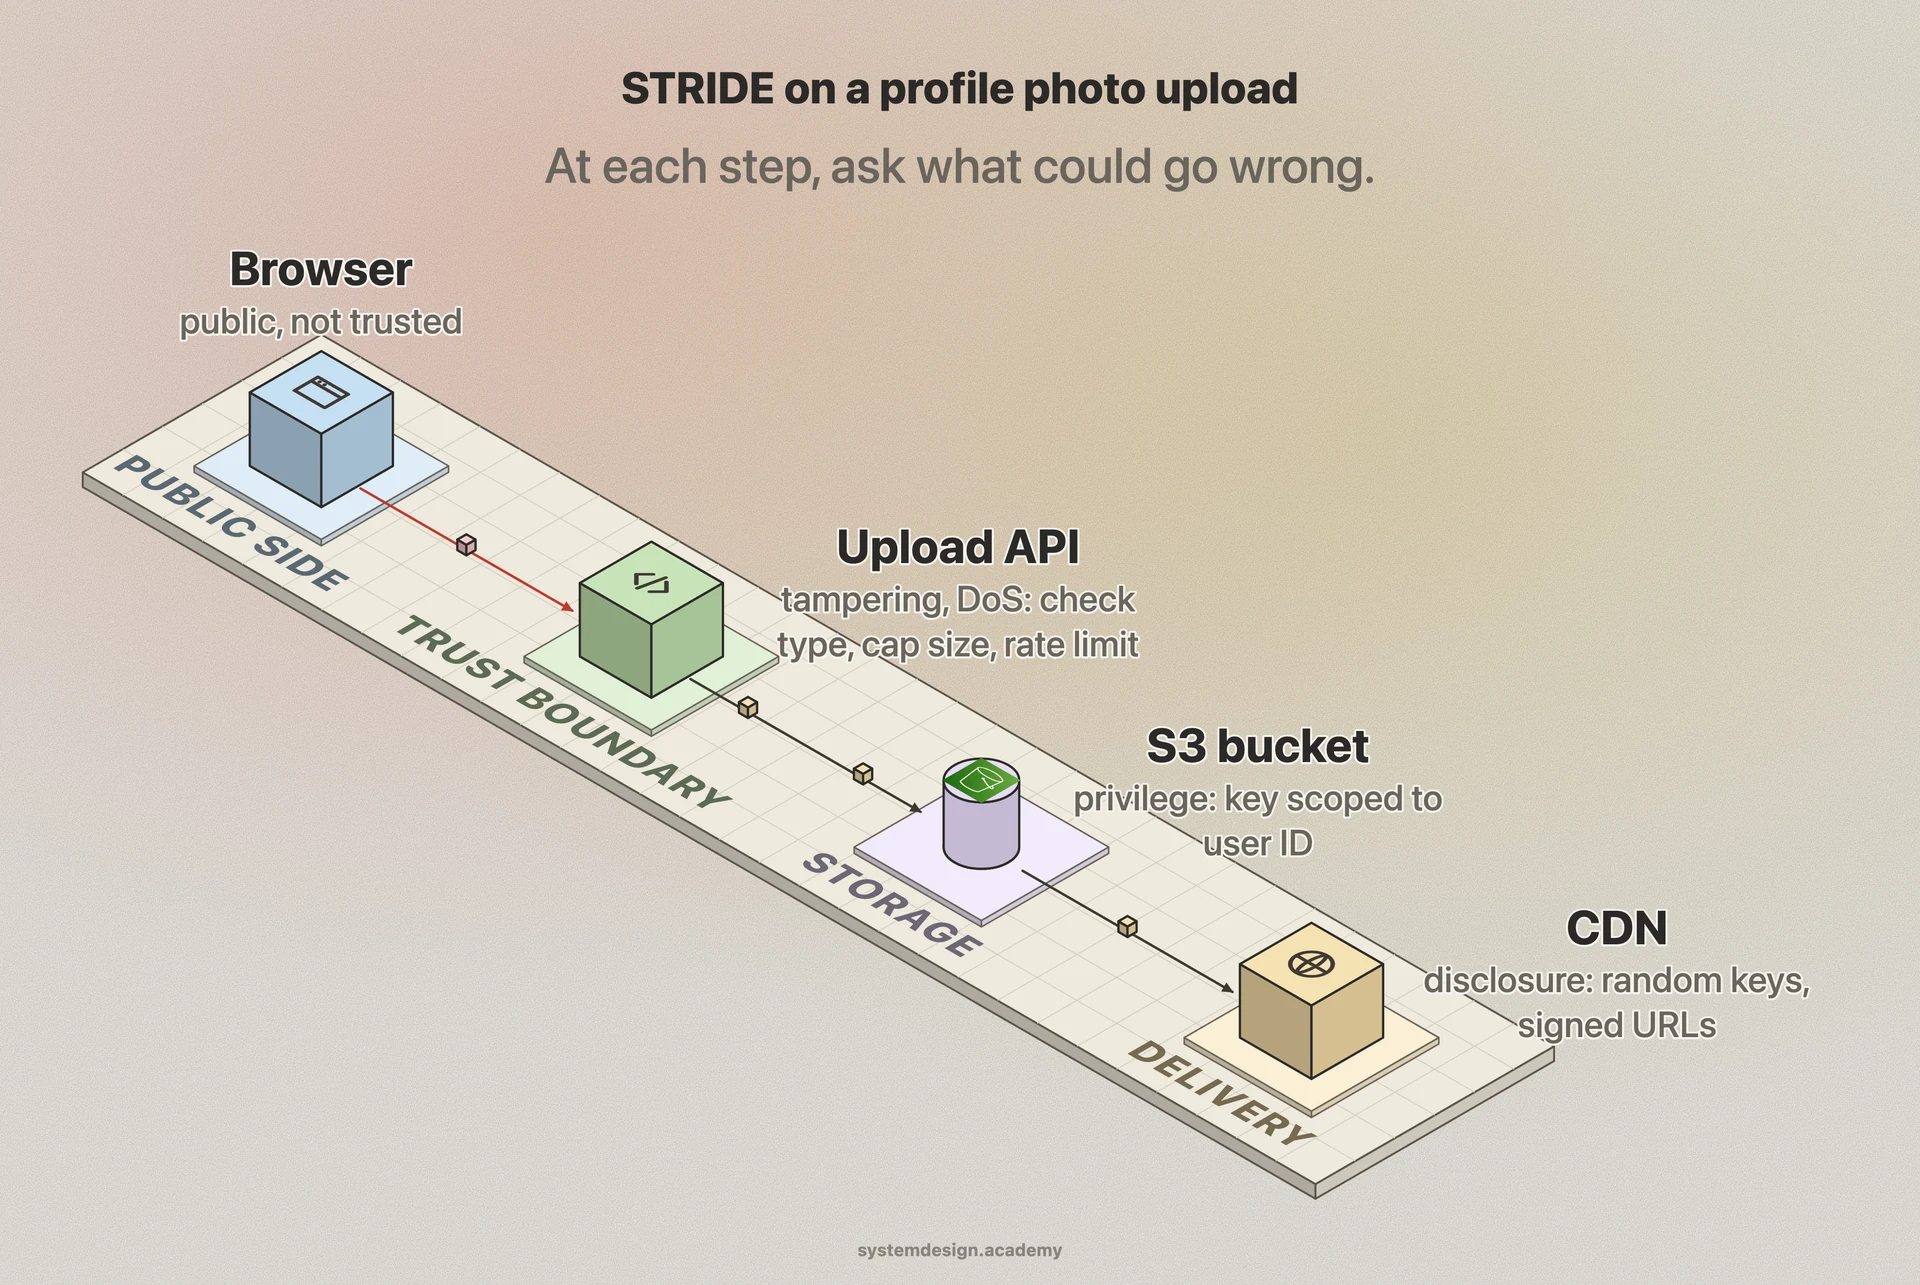
Most teams start with a data flow diagram. You draw the external users, the processes (services, APIs), the data stores (databases, queues, S3 buckets), and the arrows between them. Then you draw trust boundaries, the lines where data crosses from a less trusted zone into a more trusted one, like the edge between the public internet and your internal network, or between an unauthenticated and an authenticated request.
Every place an arrow crosses a trust boundary is where you focus. The most common framework for enumerating threats is STRIDE, from Microsoft. It gives you six categories to check each element against: Spoofing (pretending to be someone else), Tampering (changing data in transit or at rest), Repudiation (denying you did something with no audit trail), Information disclosure (leaking data), Denial of service (knocking it offline), and Elevation of privilege (gaining rights you should not have).
Once threats are listed, you rank them. DREAD is one scoring method (Damage, Reproducibility, Exploitability, Affected users, Discoverability), though many teams just use a simple high/medium/low based on likelihood times impact. The point is to spend your limited time on the threats that matter, not to file 200 tickets nobody will close.
For each high priority threat you pick a mitigation: add authentication, sign the request, encrypt the field, rate limit the endpoint, add an audit log. Then you re-check the model, which is why threat modeling is repeated whenever the design changes, not done once and filed away.