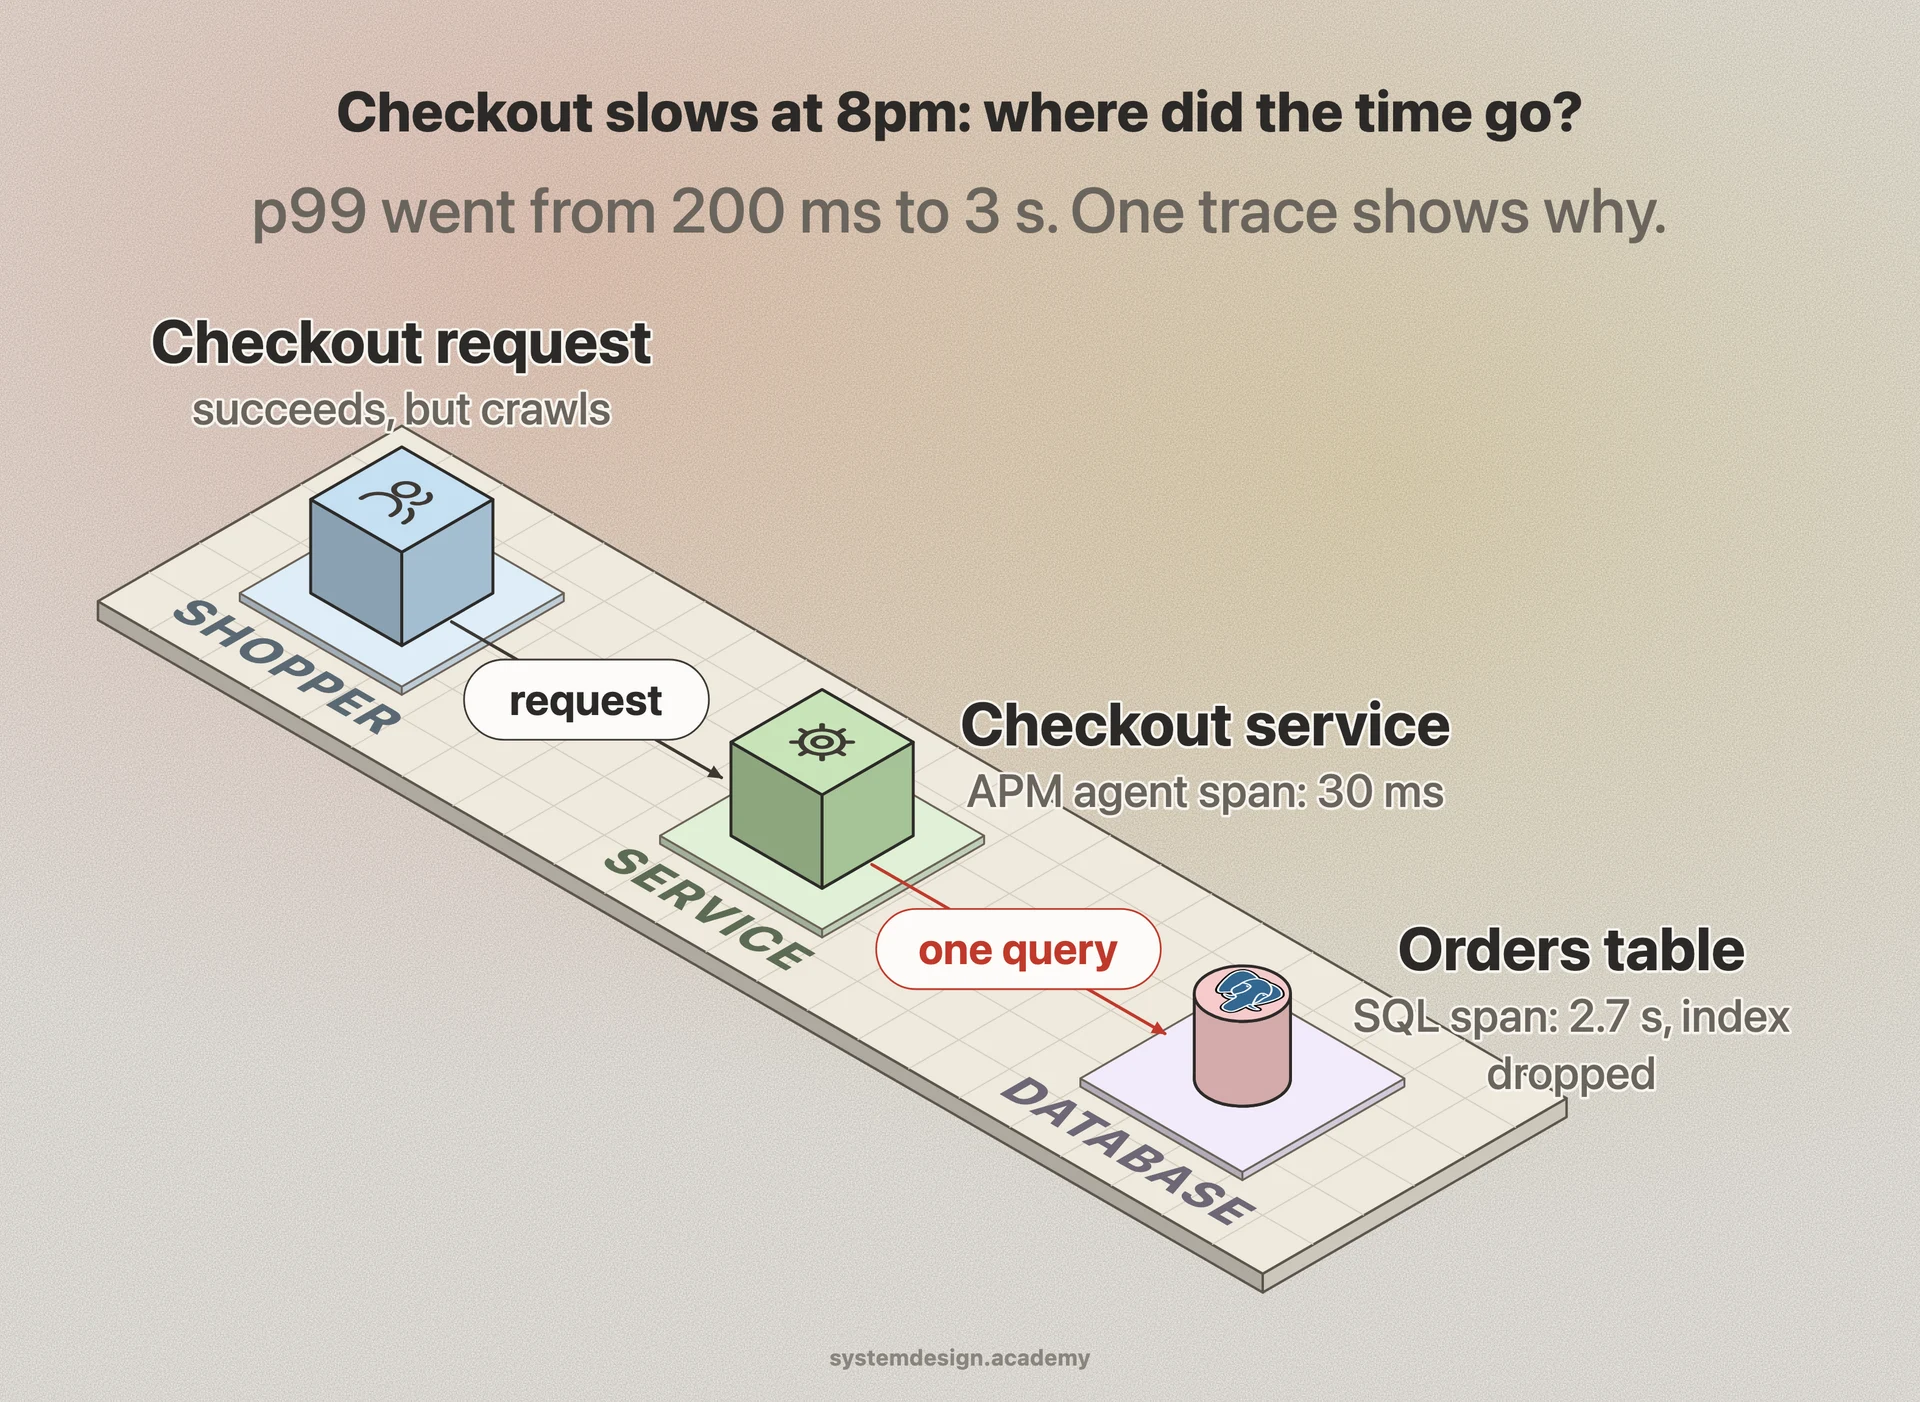
An APM agent or SDK runs inside your application process. It hooks into common libraries (HTTP frameworks, database drivers, HTTP clients, message queue clients) using instrumentation, then records a span for each unit of work: an incoming HTTP request, a SQL query, a call to Redis, a publish to Kafka. Each span carries a start time, a duration, and metadata like the SQL statement or the URL.
Spans from a single request are stitched together into a trace using a shared trace ID that is propagated across service boundaries, usually through HTTP headers. This is what lets you click one slow request in the dashboard and see the full waterfall: 40ms in your service, 1.8 seconds waiting on a database, 200ms in a third-party payment API. Distributed tracing is the backbone of APM in a microservices setup.
Because tracing every request at scale is expensive, most APM systems sample. Head-based sampling decides at the start of a request whether to keep it (for example, keep 10 percent). Tail-based sampling buffers traces and keeps the interesting ones, like every trace that errored or exceeded a latency threshold, which costs more to run but loses fewer of the traces you actually care about.
The modern standard for the instrumentation layer is OpenTelemetry, a vendor-neutral set of SDKs and a wire format. You instrument once with OpenTelemetry and can ship the data to Datadog, Grafana, New Relic, or your own backend, which avoids locking your code to one vendor's proprietary agent.