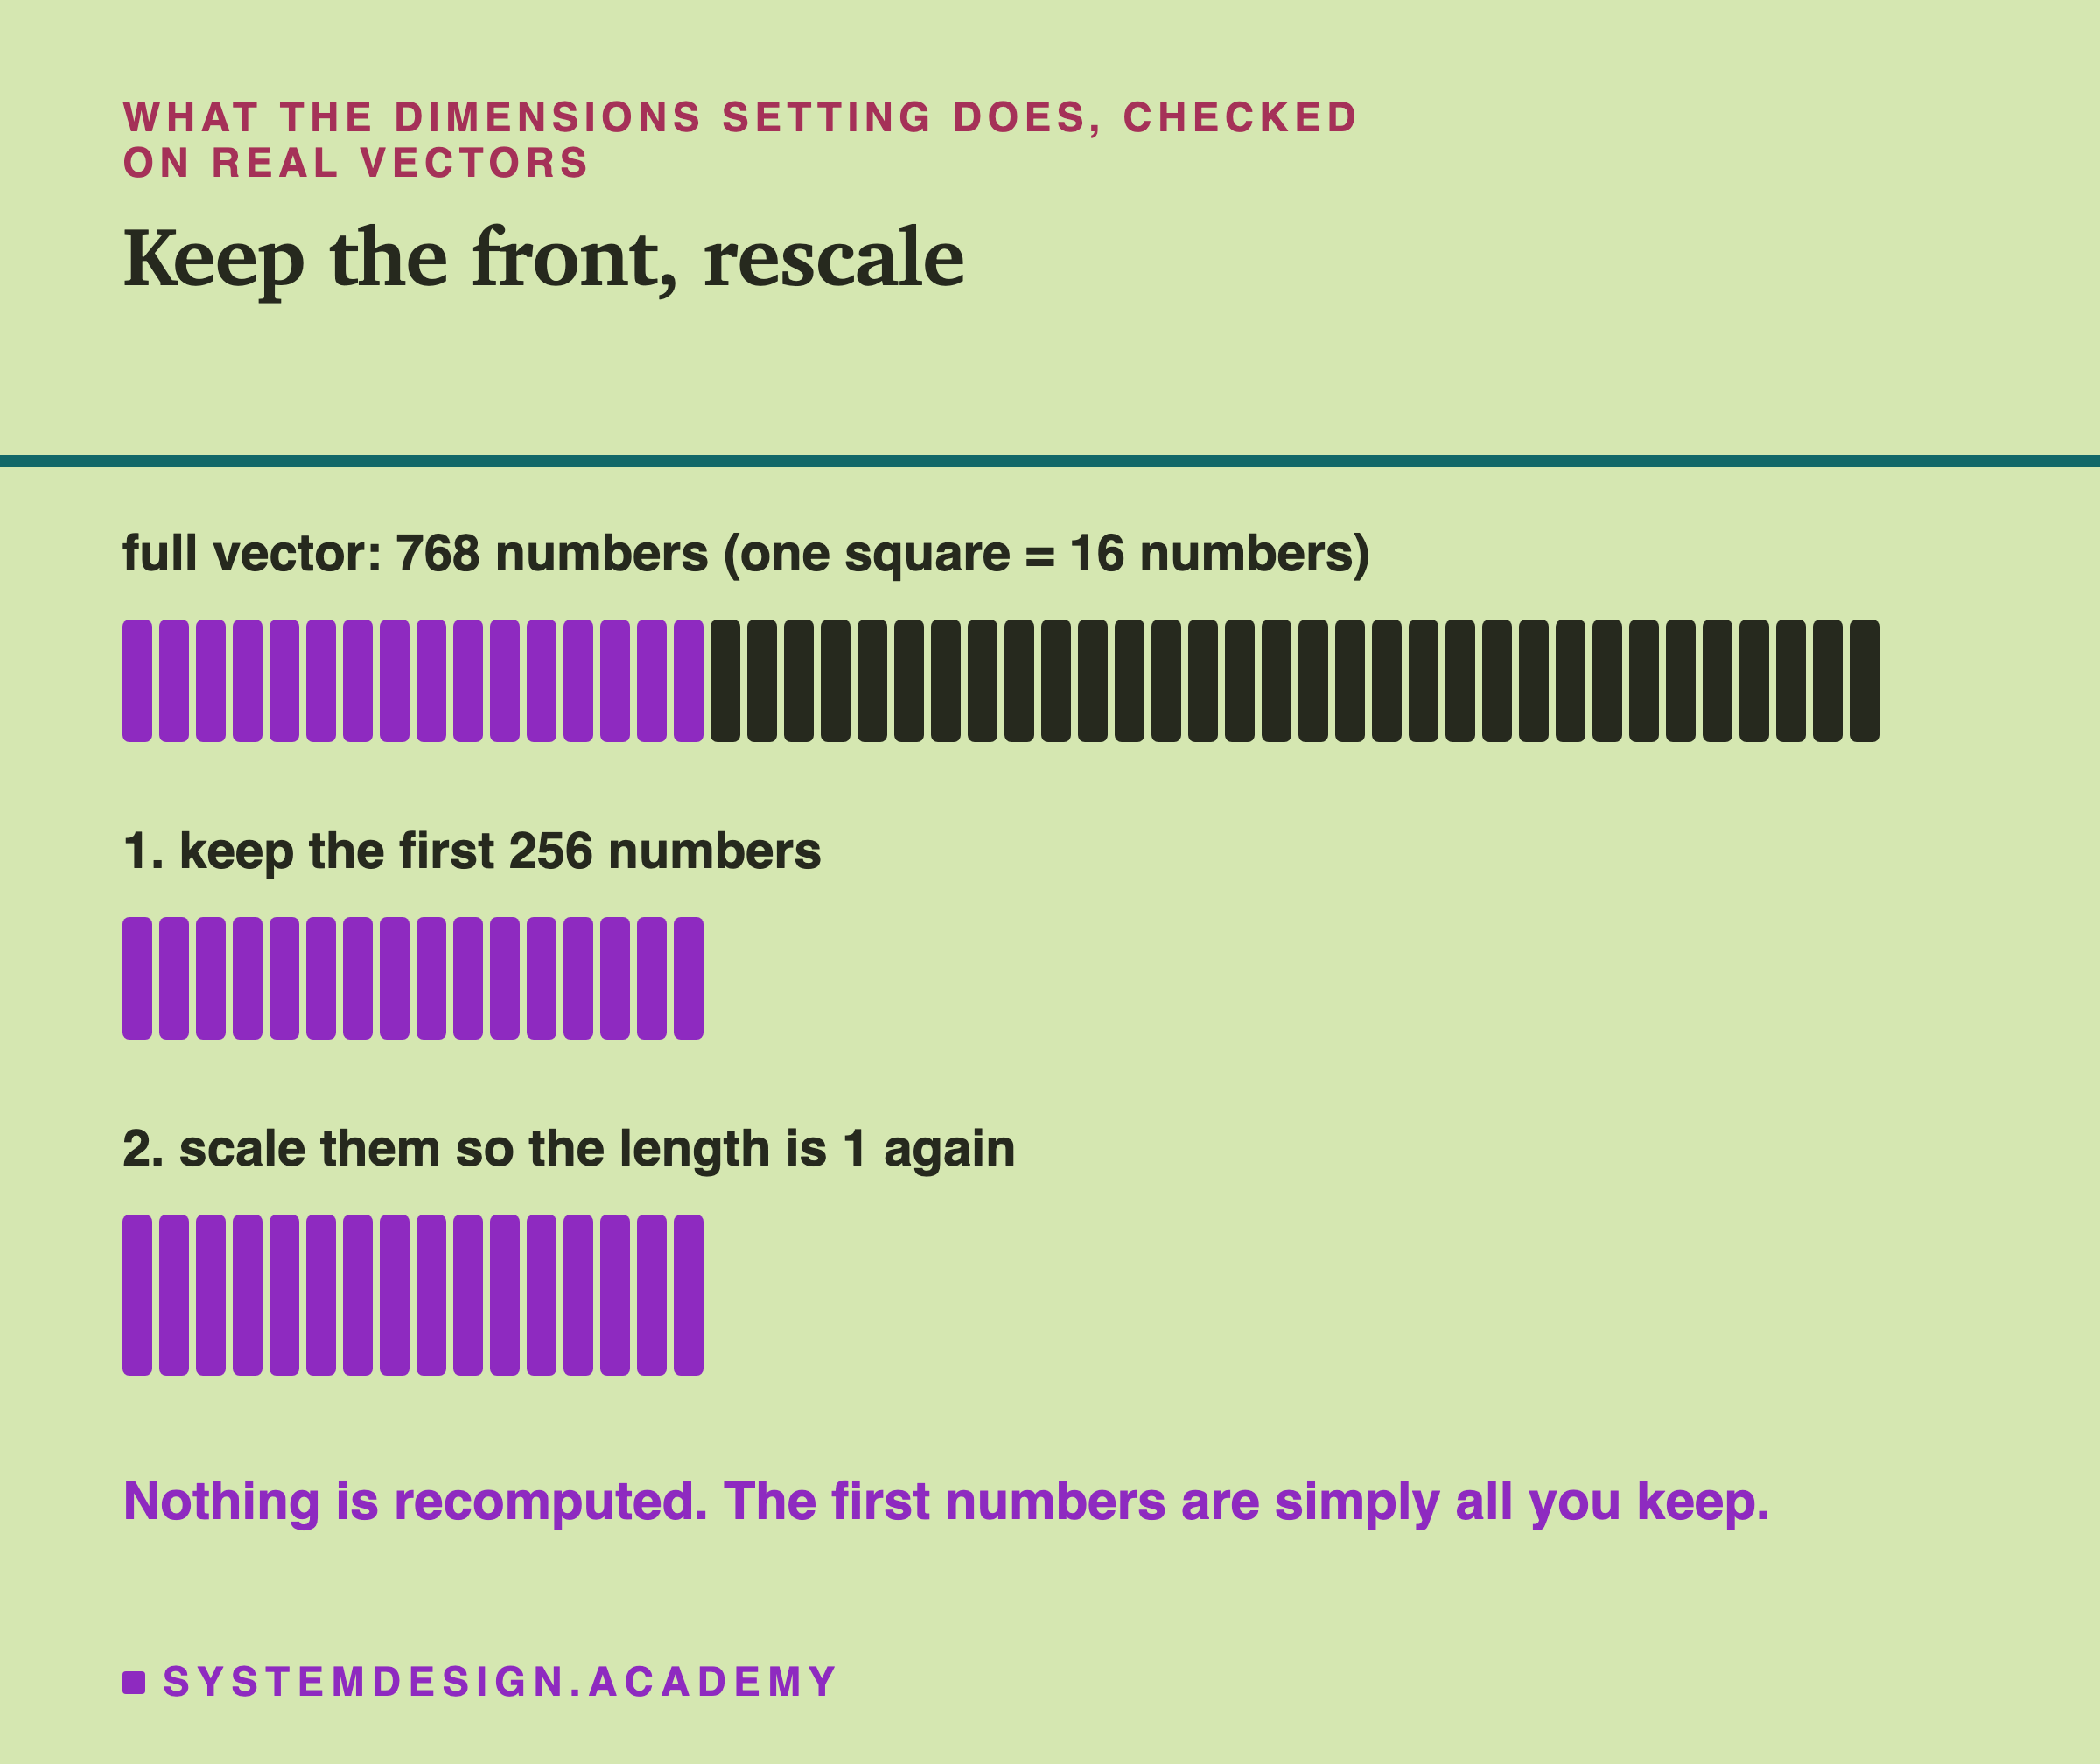
An embedding is stored for every document, or every piece of a document, that you want to search. Each number usually takes 4 bytes. So the length of the vector is multiplied by how many documents you keep.
For one million documents, the lesson does the arithmetic. At 768 numbers that is about 3.1 GB, just for the embeddings. At 1,024 numbers it is about 4.1 GB. At 256 numbers it is about 1.0 GB, for either model.
Search work shrinks the same way. A simple search compares the question with every stored vector, number by number. In the lesson's test of 1,823 pieces, one question needs 1,400,064 multiplications at 768 numbers and 466,688 at 256.
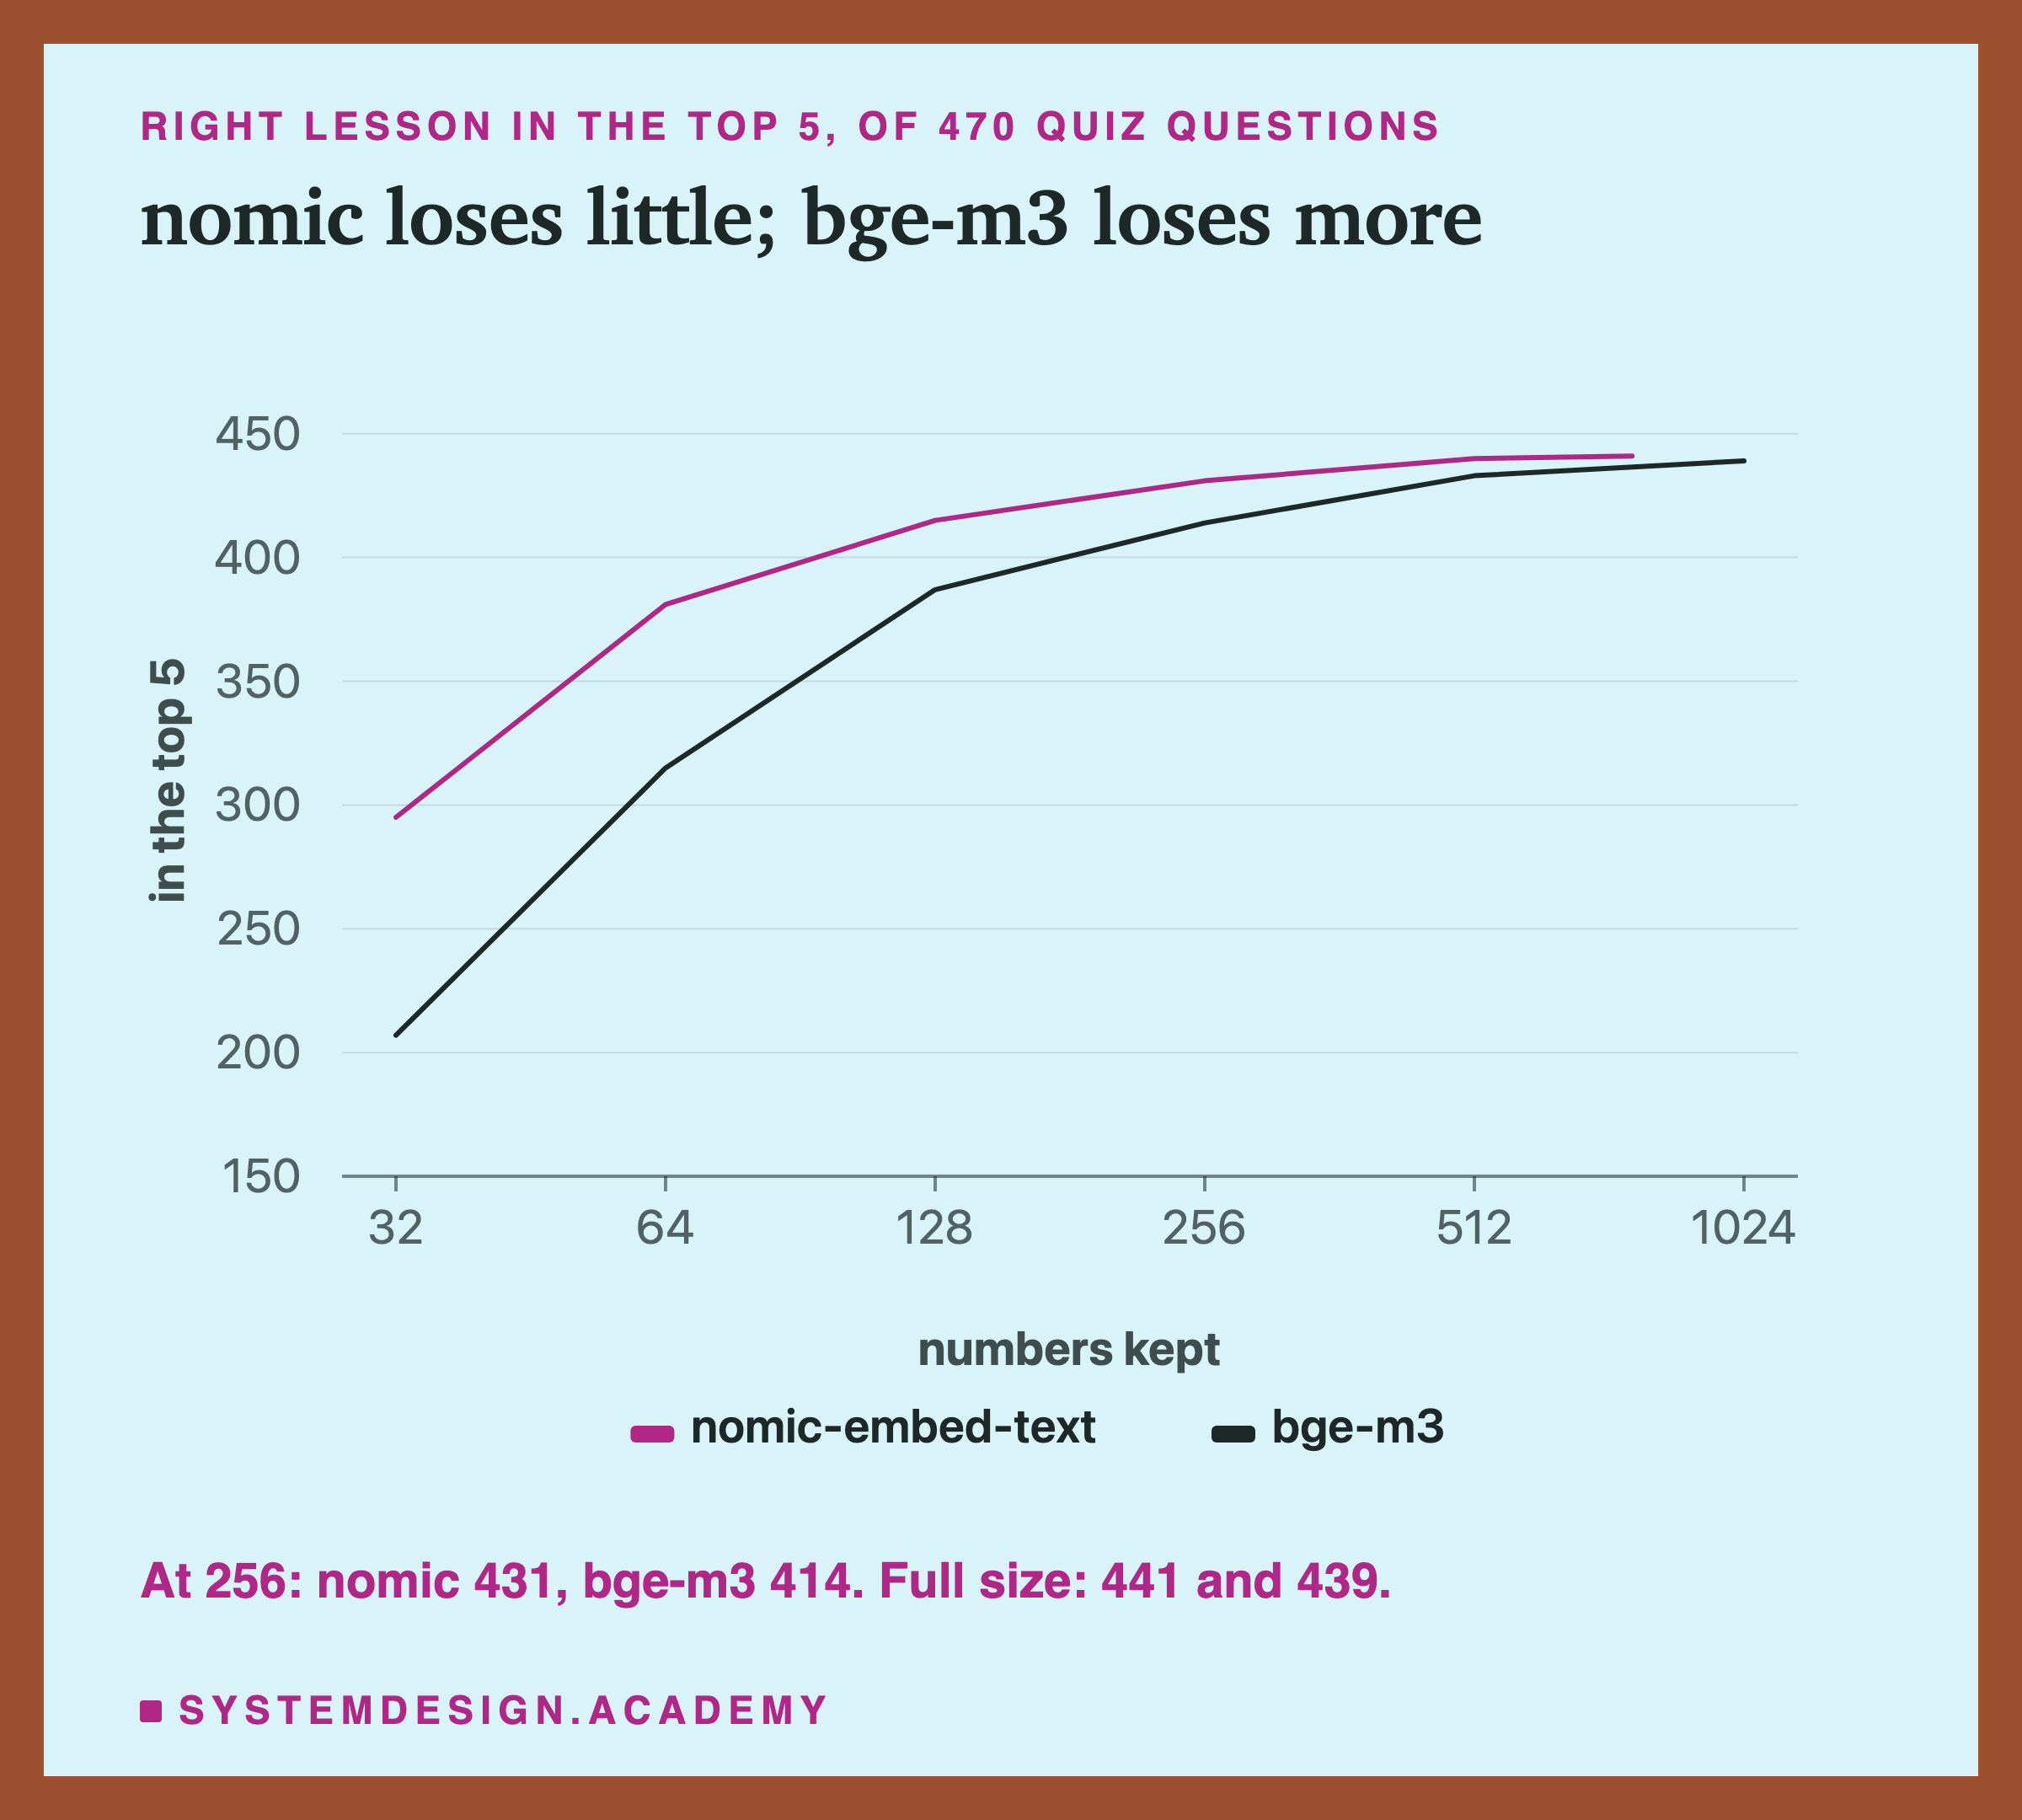
That saving is only worth having if search still finds the right documents. A smaller vector that finds the wrong document is not cheaper. It is broken. So the real question is how much accuracy you lose.