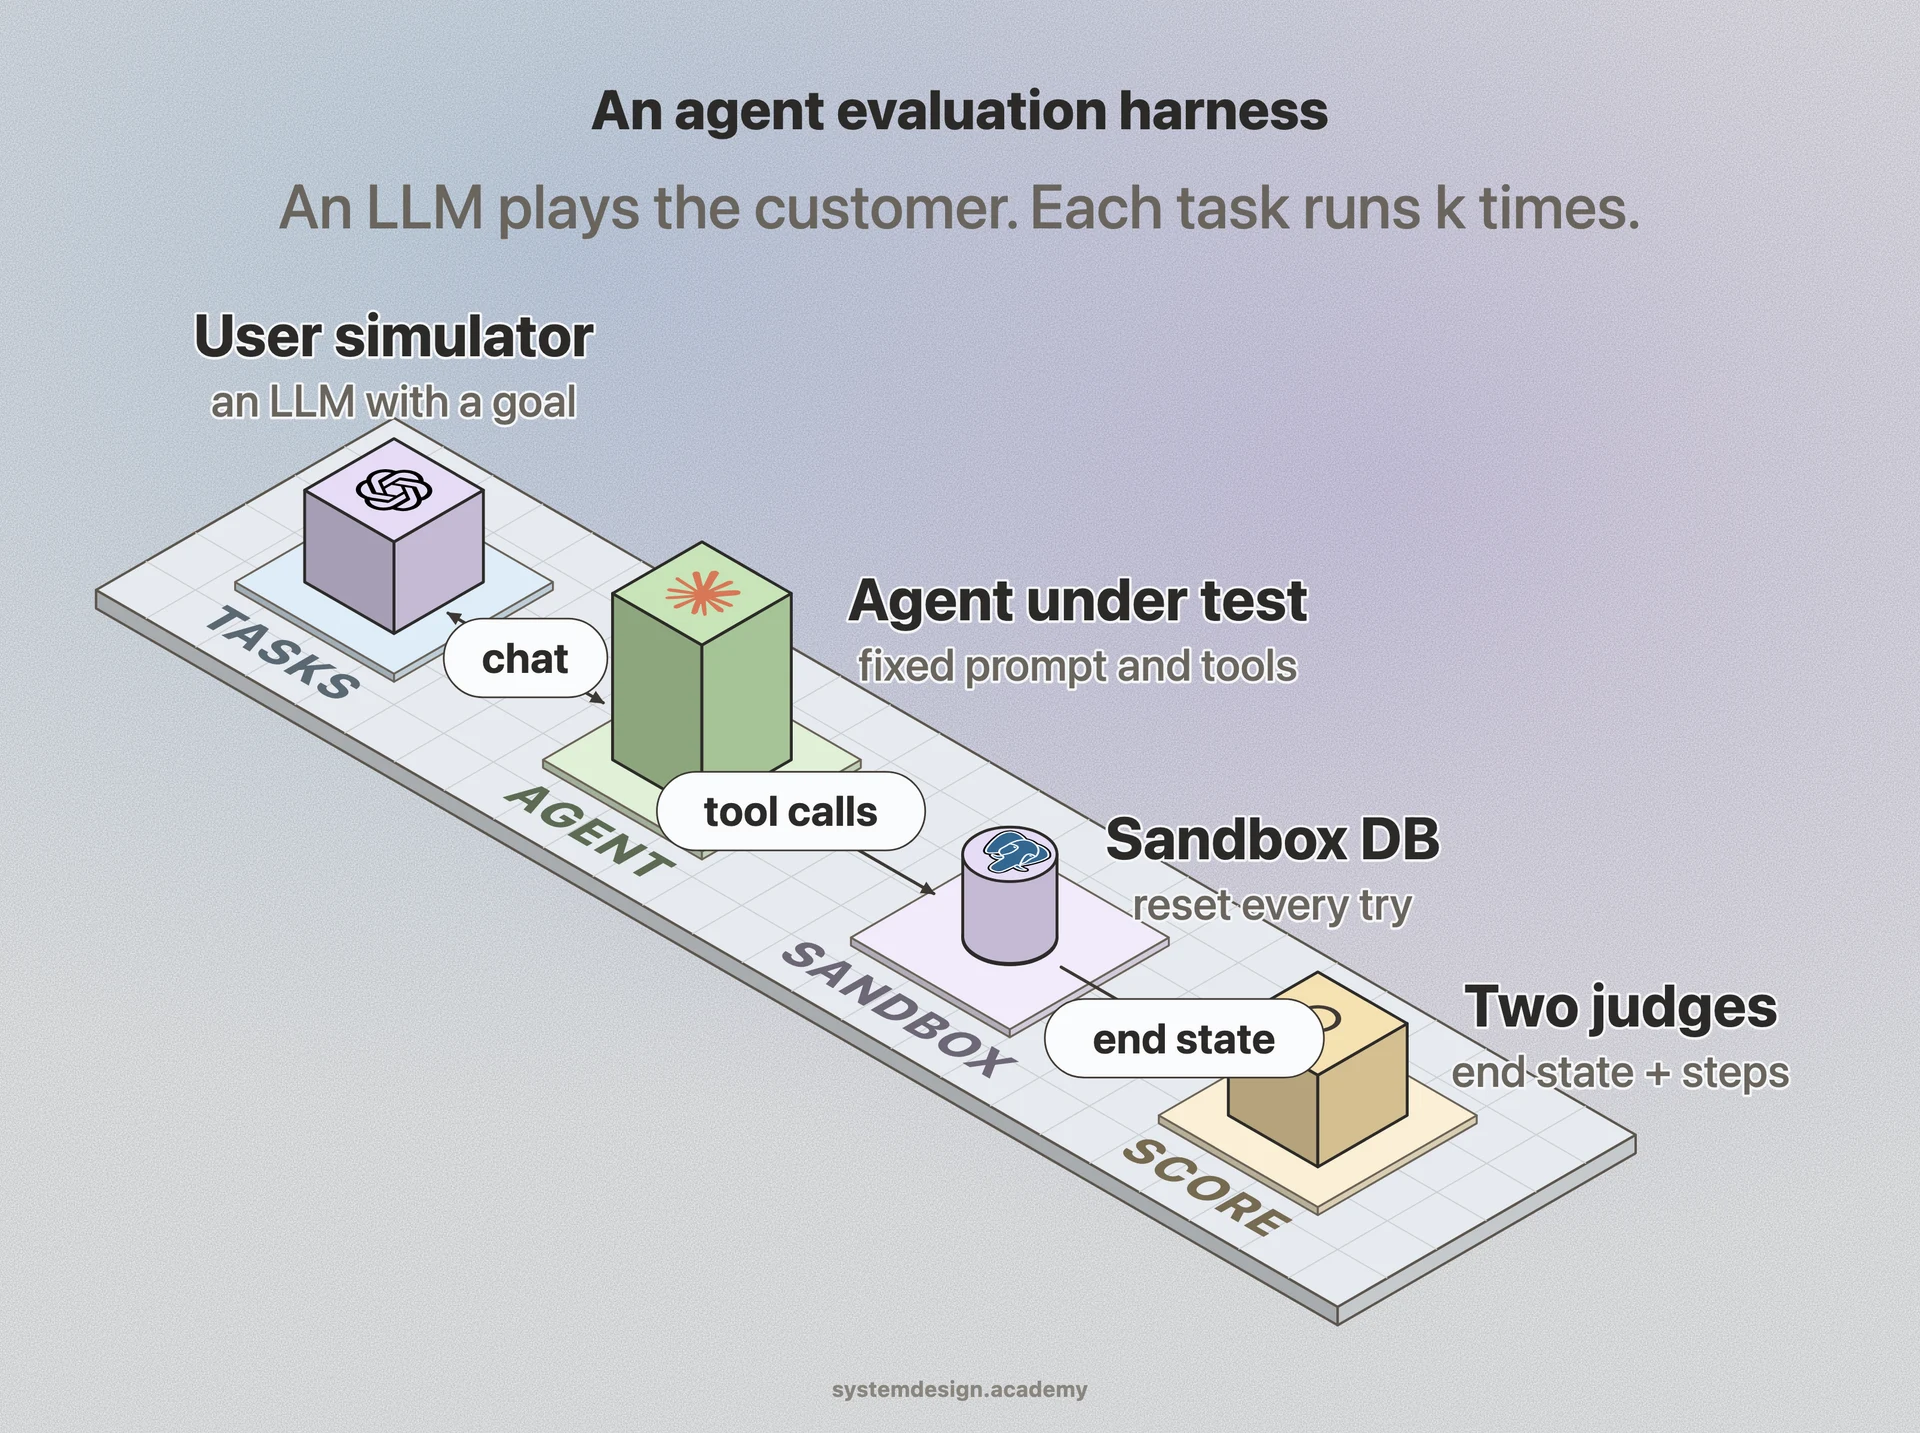
An AI agent is a program that lets a large language model (LLM), the kind of model behind ChatGPT, decide what to do next. It calls tools, reads the results and decides again until the task is done. A tool is a function the agent may run, such as "find order" or "issue refund".
Evaluation means testing with a fixed set of examples and a score, so you can compare one version with another. Testing a chatbot is mostly about its answer. Testing an agent is harder, for three reasons.
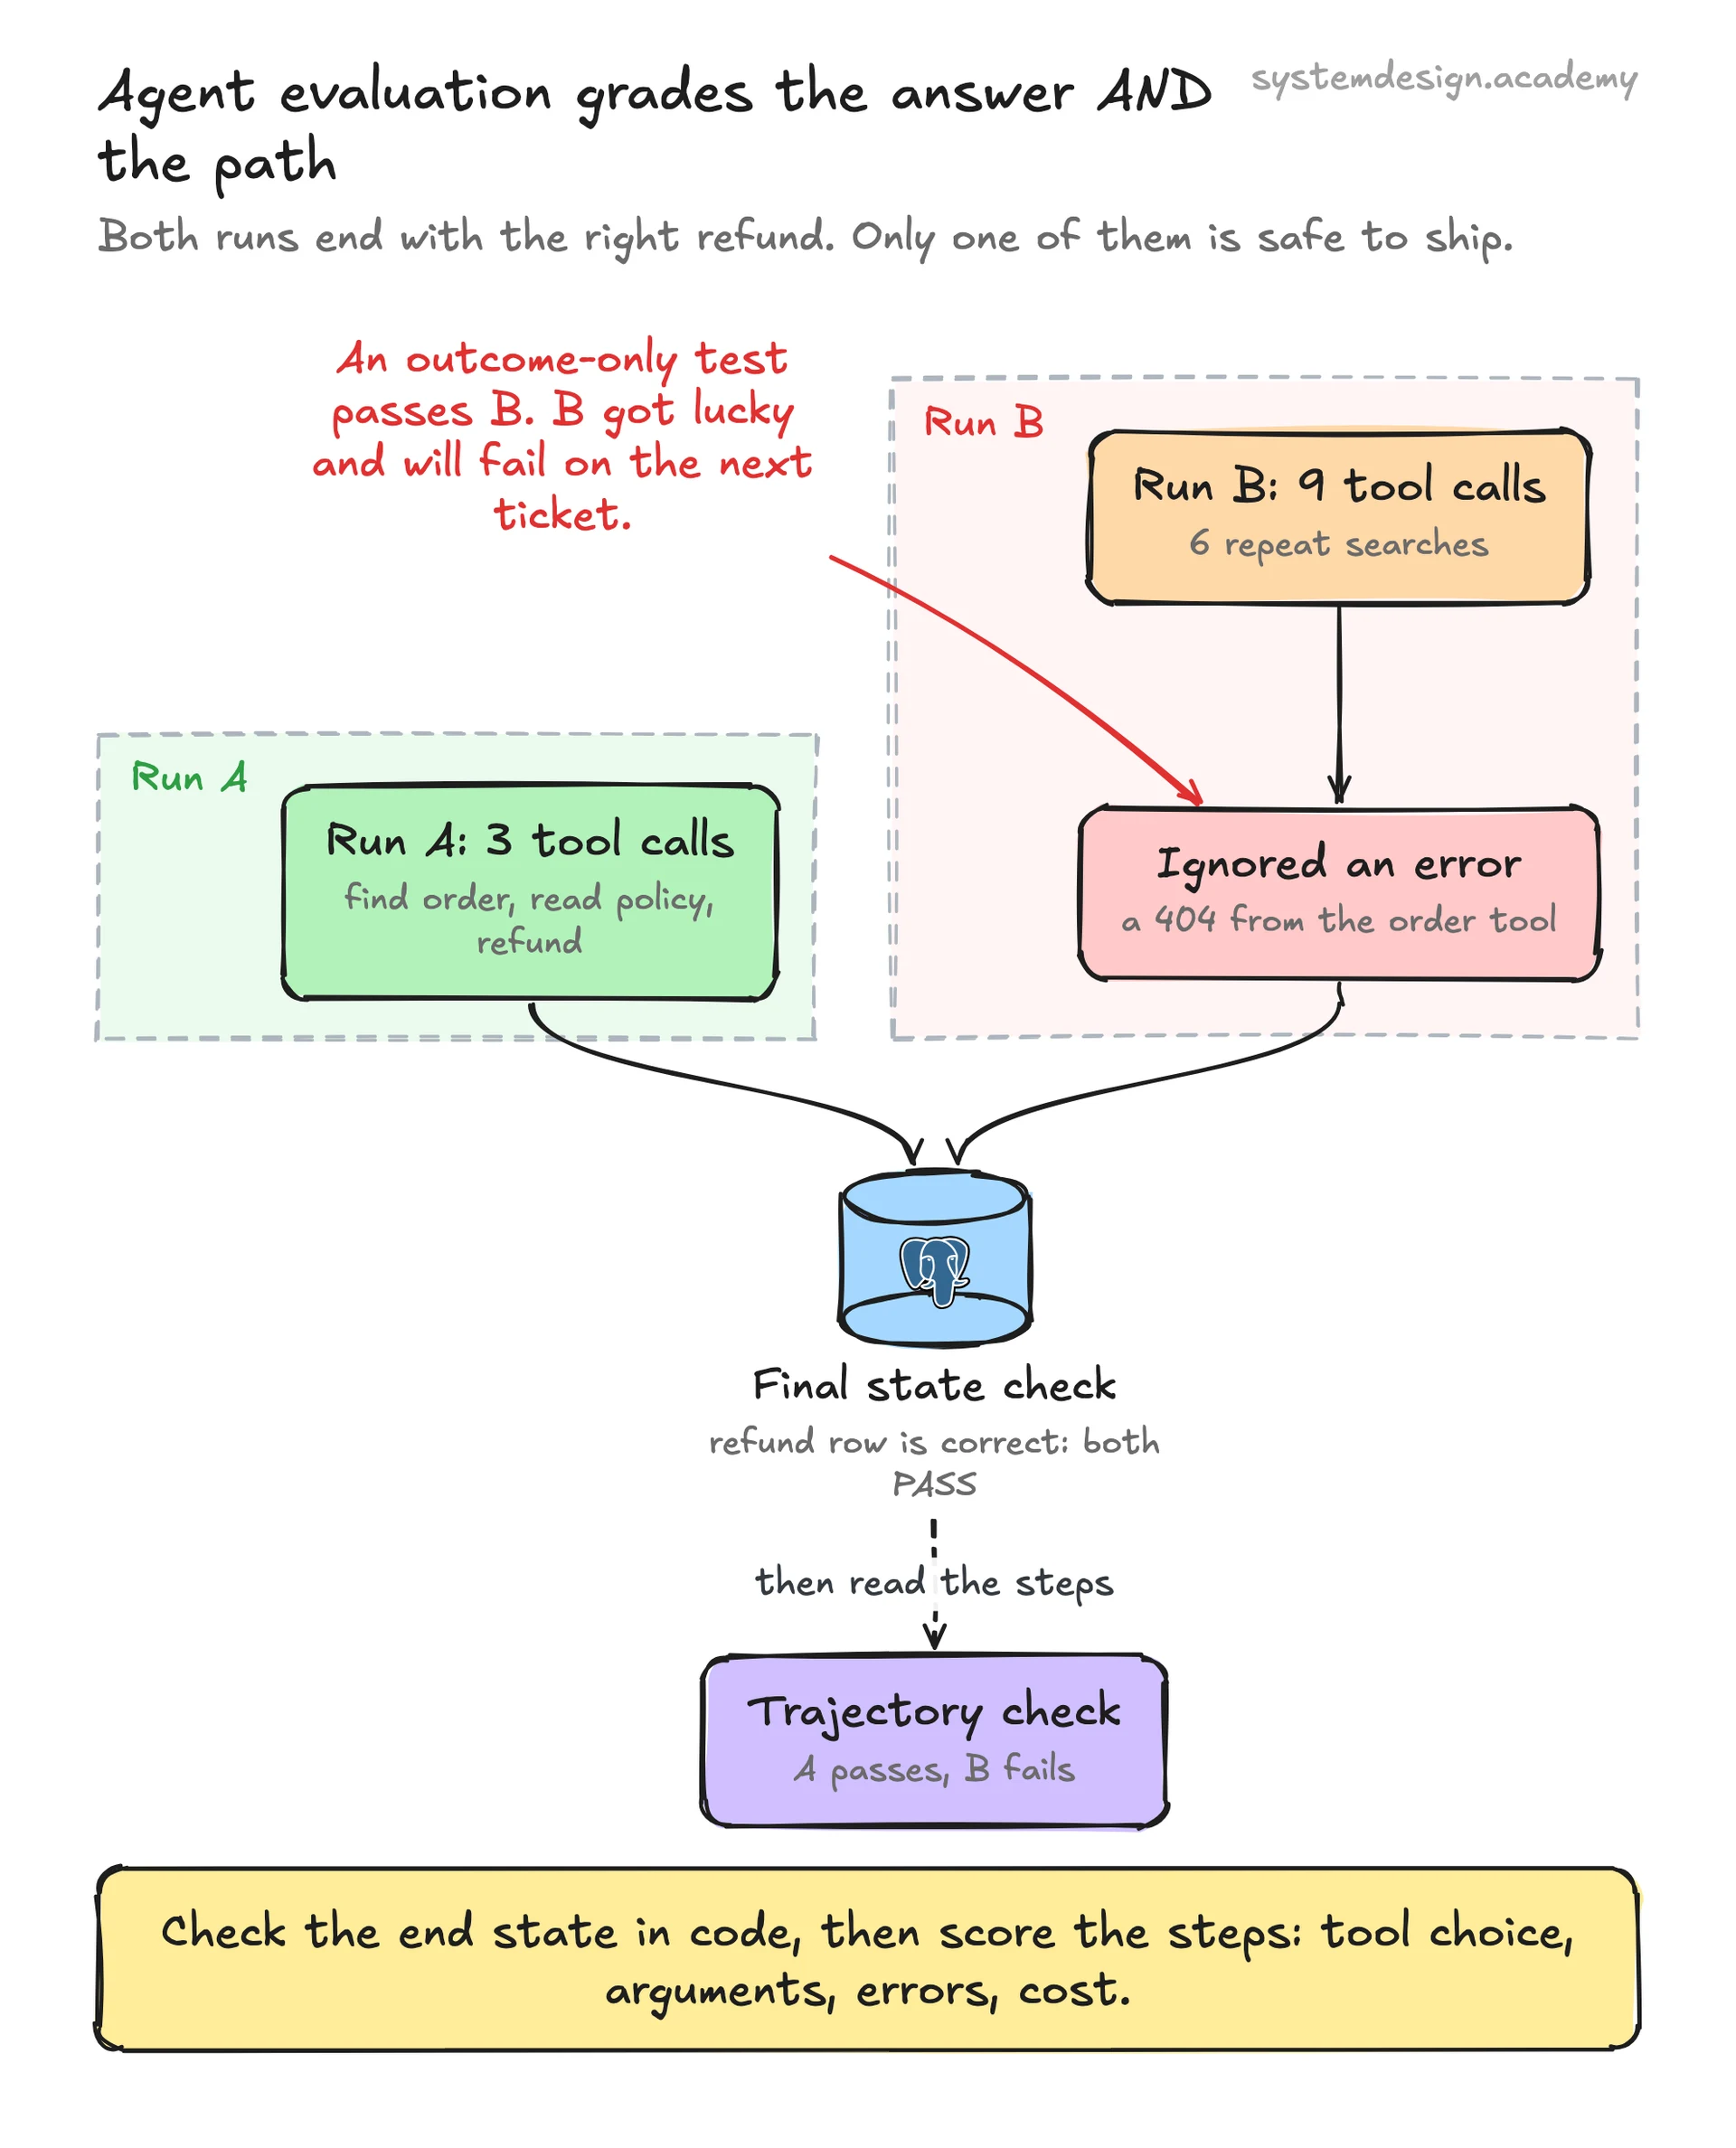
First, the agent acts. It changes things in the world, such as a refund in a database. So you must check what changed, not only what it said. Second, it takes many steps, and a right answer can hide a bad path. Third, it is not consistent. LLMs give different outputs on different runs, so an agent that solves a task today may fail the same task tomorrow.
Agent evaluation answers three questions. Did it finish the task? Did it get there in a safe and sensible way? And will it do that every time?