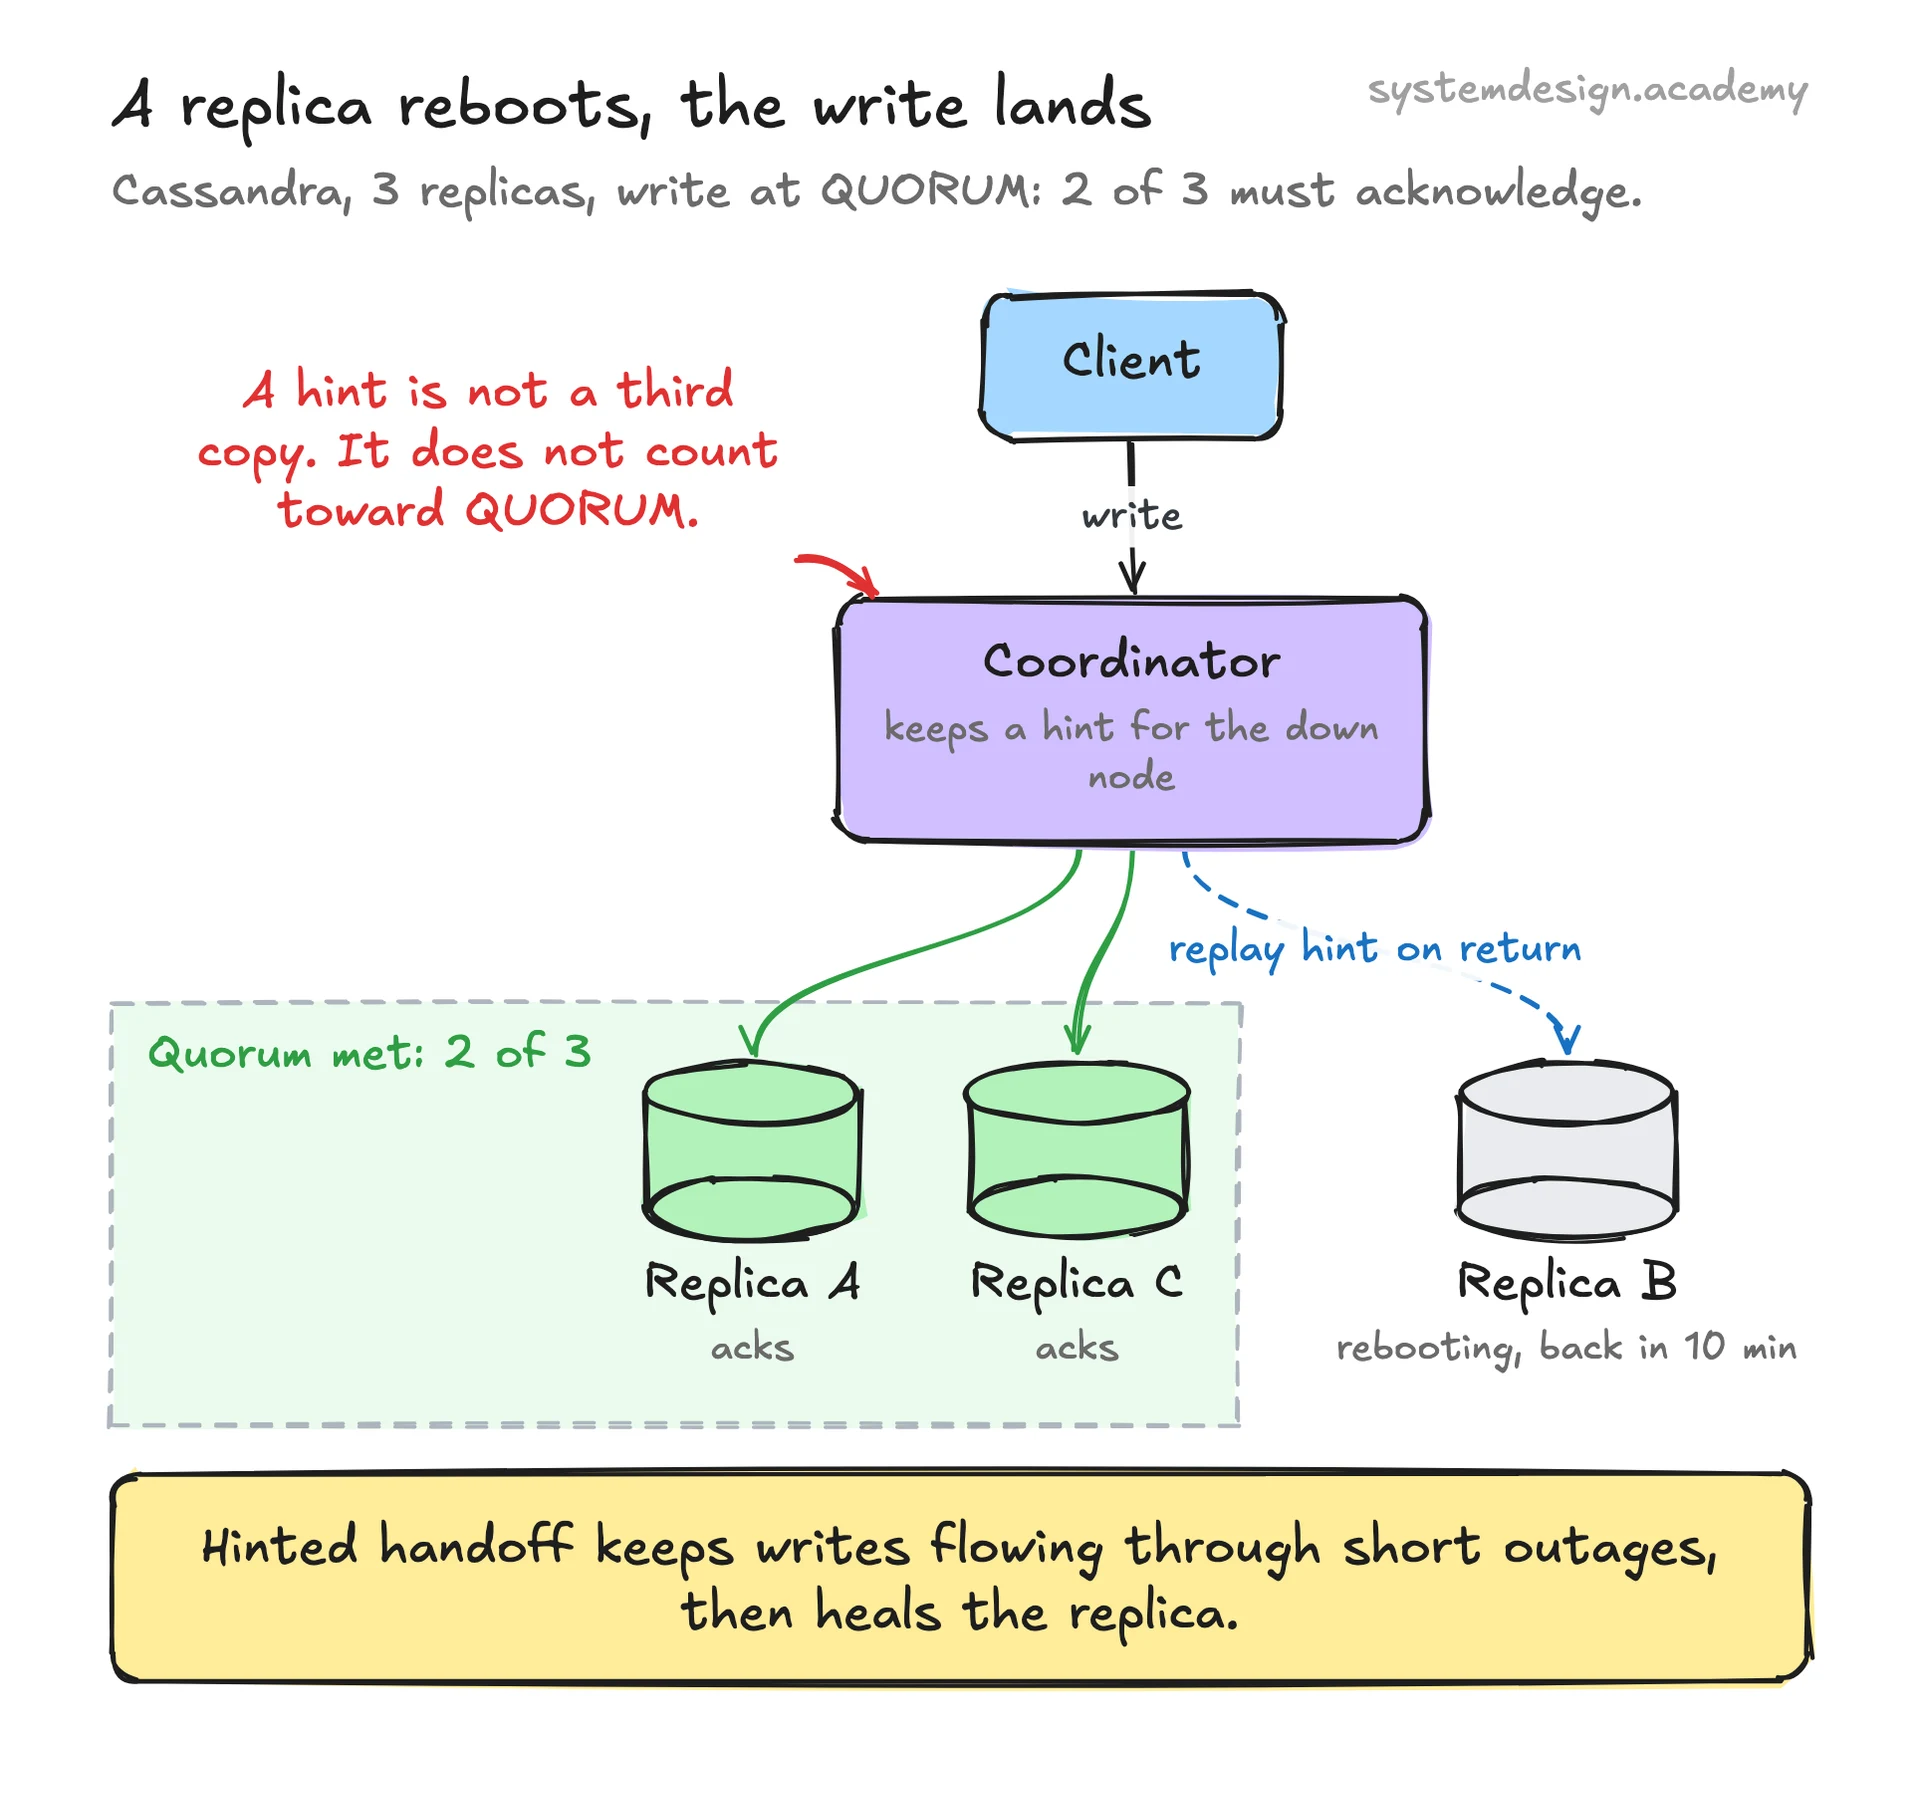
A coordinator node receives a write and computes which replicas should hold it, usually using consistent hashing to map the key onto the ring of nodes. Say replicas A, B, and C should each store the value but B is unreachable.
The coordinator sends the write to A and C as normal, and for B it picks a live node to hold a hint. In some designs the coordinator itself stores the hint; in others, like Amazon Dynamo, a different healthy node in the preference list stores it. The hint is tagged with B's identity and a timestamp.
Each node runs a background process that periodically checks whether the nodes it holds hints for are alive again. When B recovers, the holding node streams the queued hints to B, B applies them, and once B confirms receipt the holding node deletes its copy. Hints are usually limited in time (by default Cassandra stops storing new hints for a node that has been down longer than 3 hours) so an outage that drags on does not let hints pile up forever and eat disk.
Hinted handoff alone does not guarantee the replica catches up perfectly. Hints can be dropped after their TTL, or the holding node itself can crash and lose them. That is why systems pair it with a slower, exhaustive repair mechanism such as anti-entropy with Merkle trees and read repair to reconcile any divergence the hints missed.