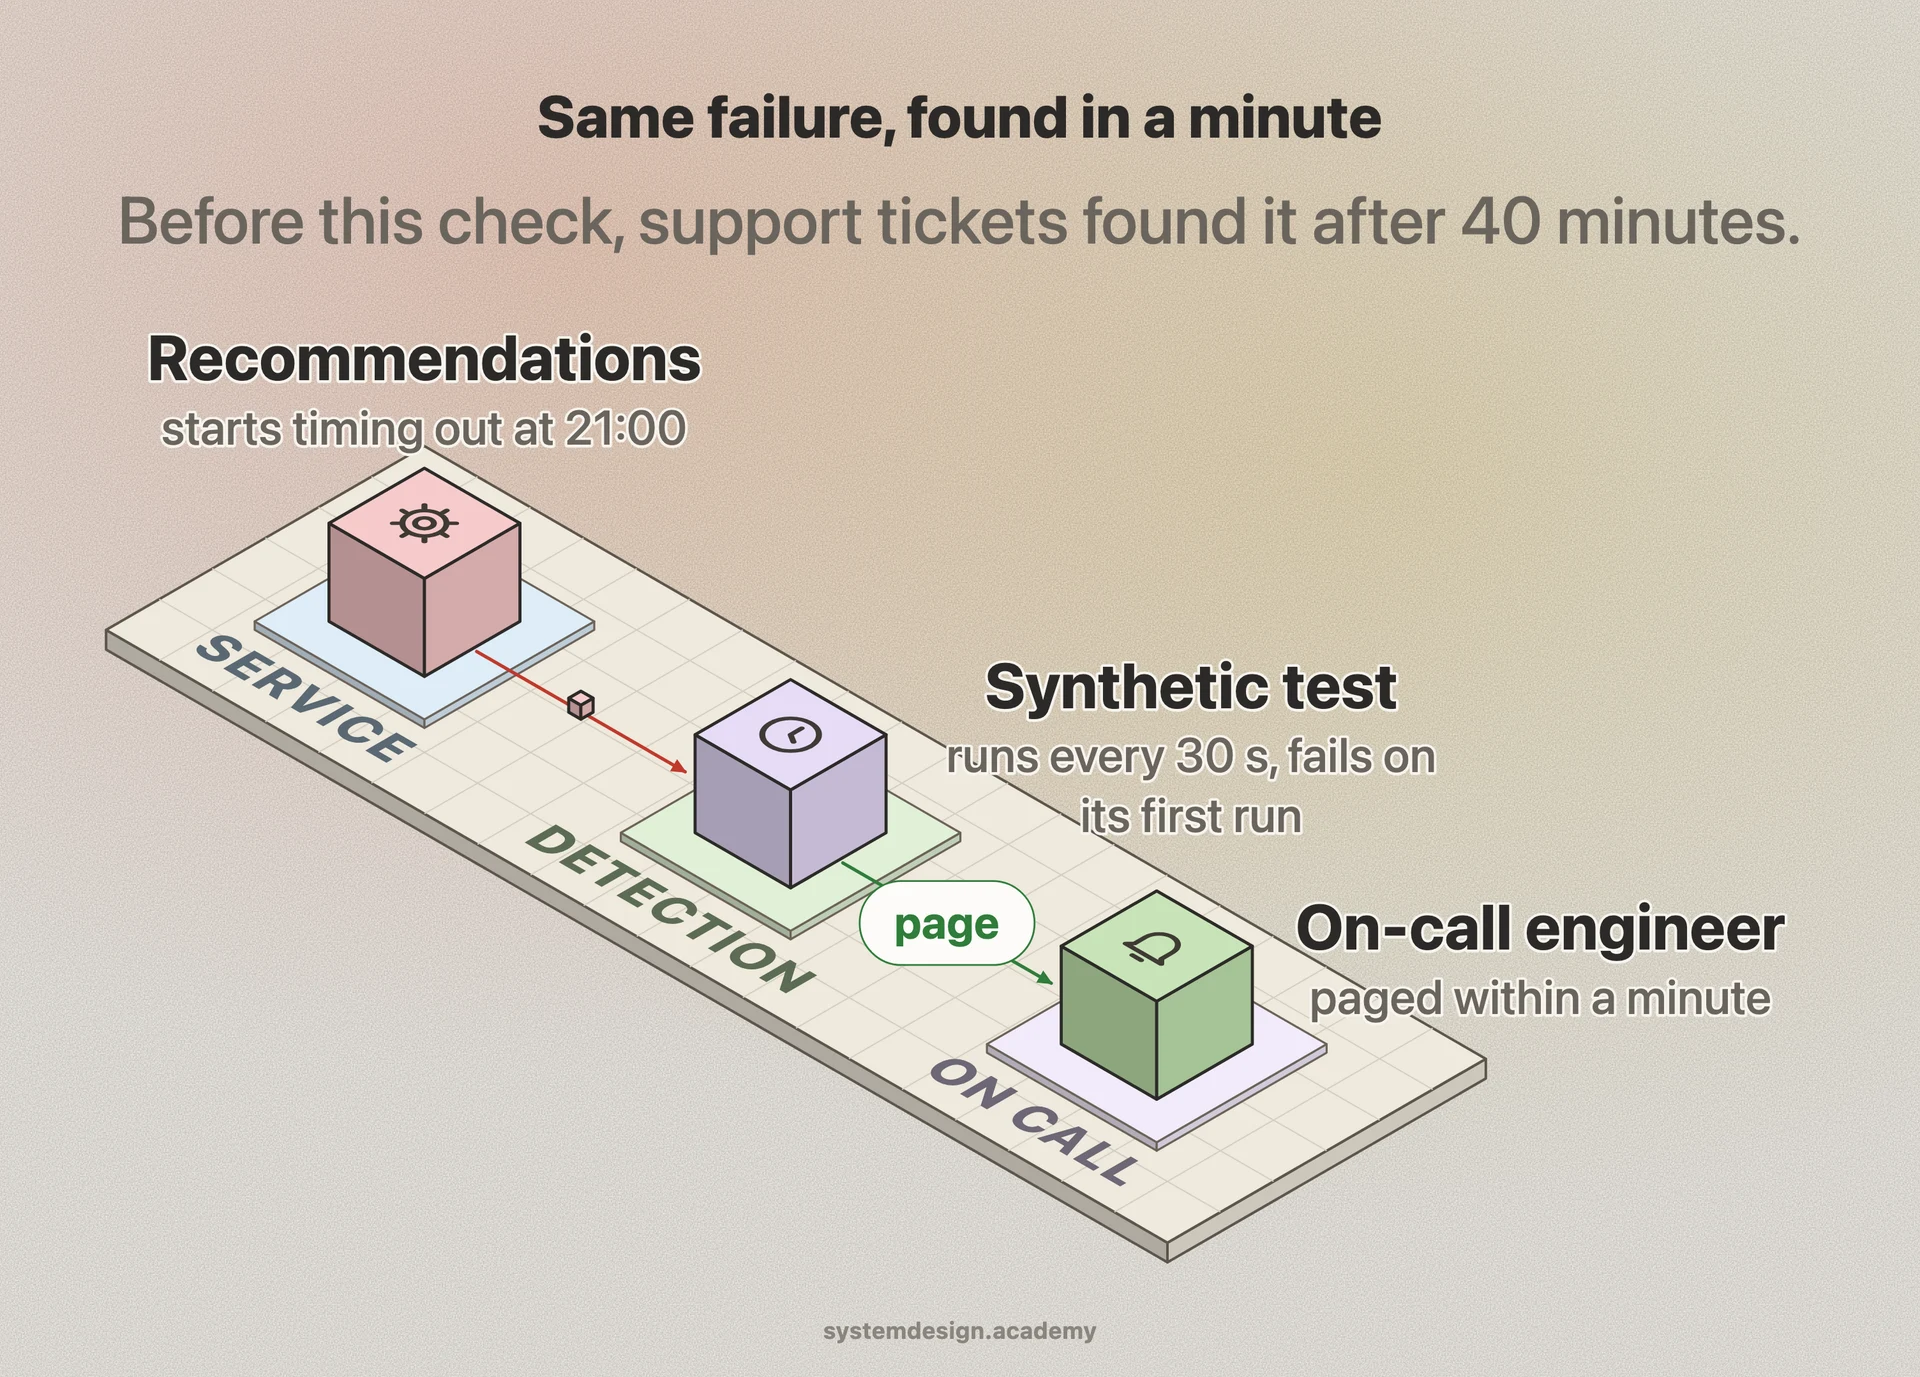
Calculating MTTD requires knowing the true start time of each incident, which is the hard part. Teams reconstruct it after the fact from logs, metric graphs, and traces, then compare it to the timestamp of the first alert or first human report. Tools like PagerDuty, Datadog, and Opsgenie record these timestamps automatically so the gap can be computed without guesswork.
The lever for lowering MTTD is observability: metrics, logs, and traces feeding alerts that fire on symptoms users feel, not just on raw resource numbers. An alert on a 5 percent jump in HTTP 500 rate or a p99 latency breach detects real pain in seconds. An alert that only watches CPU usage can miss an outage entirely if the broken service is sitting idle.
Good signal-to-noise is just as important. If on-call engineers get hundreds of low-value alerts a day, they tune them out, and real failures sit in the noise for long stretches. Synthetic checks, anomaly detection, and SLO-based burn-rate alerts (popularized by Google's SRE practice) all push detection earlier without flooding the pager.
The trade-off is sensitivity versus noise. Tighter, faster thresholds cut MTTD but raise false positives and alert fatigue. Looser thresholds keep the pager quiet but let slow-burning problems hide. The goal is the lowest MTTD you can hit before false alarms start eroding trust in the alerts.