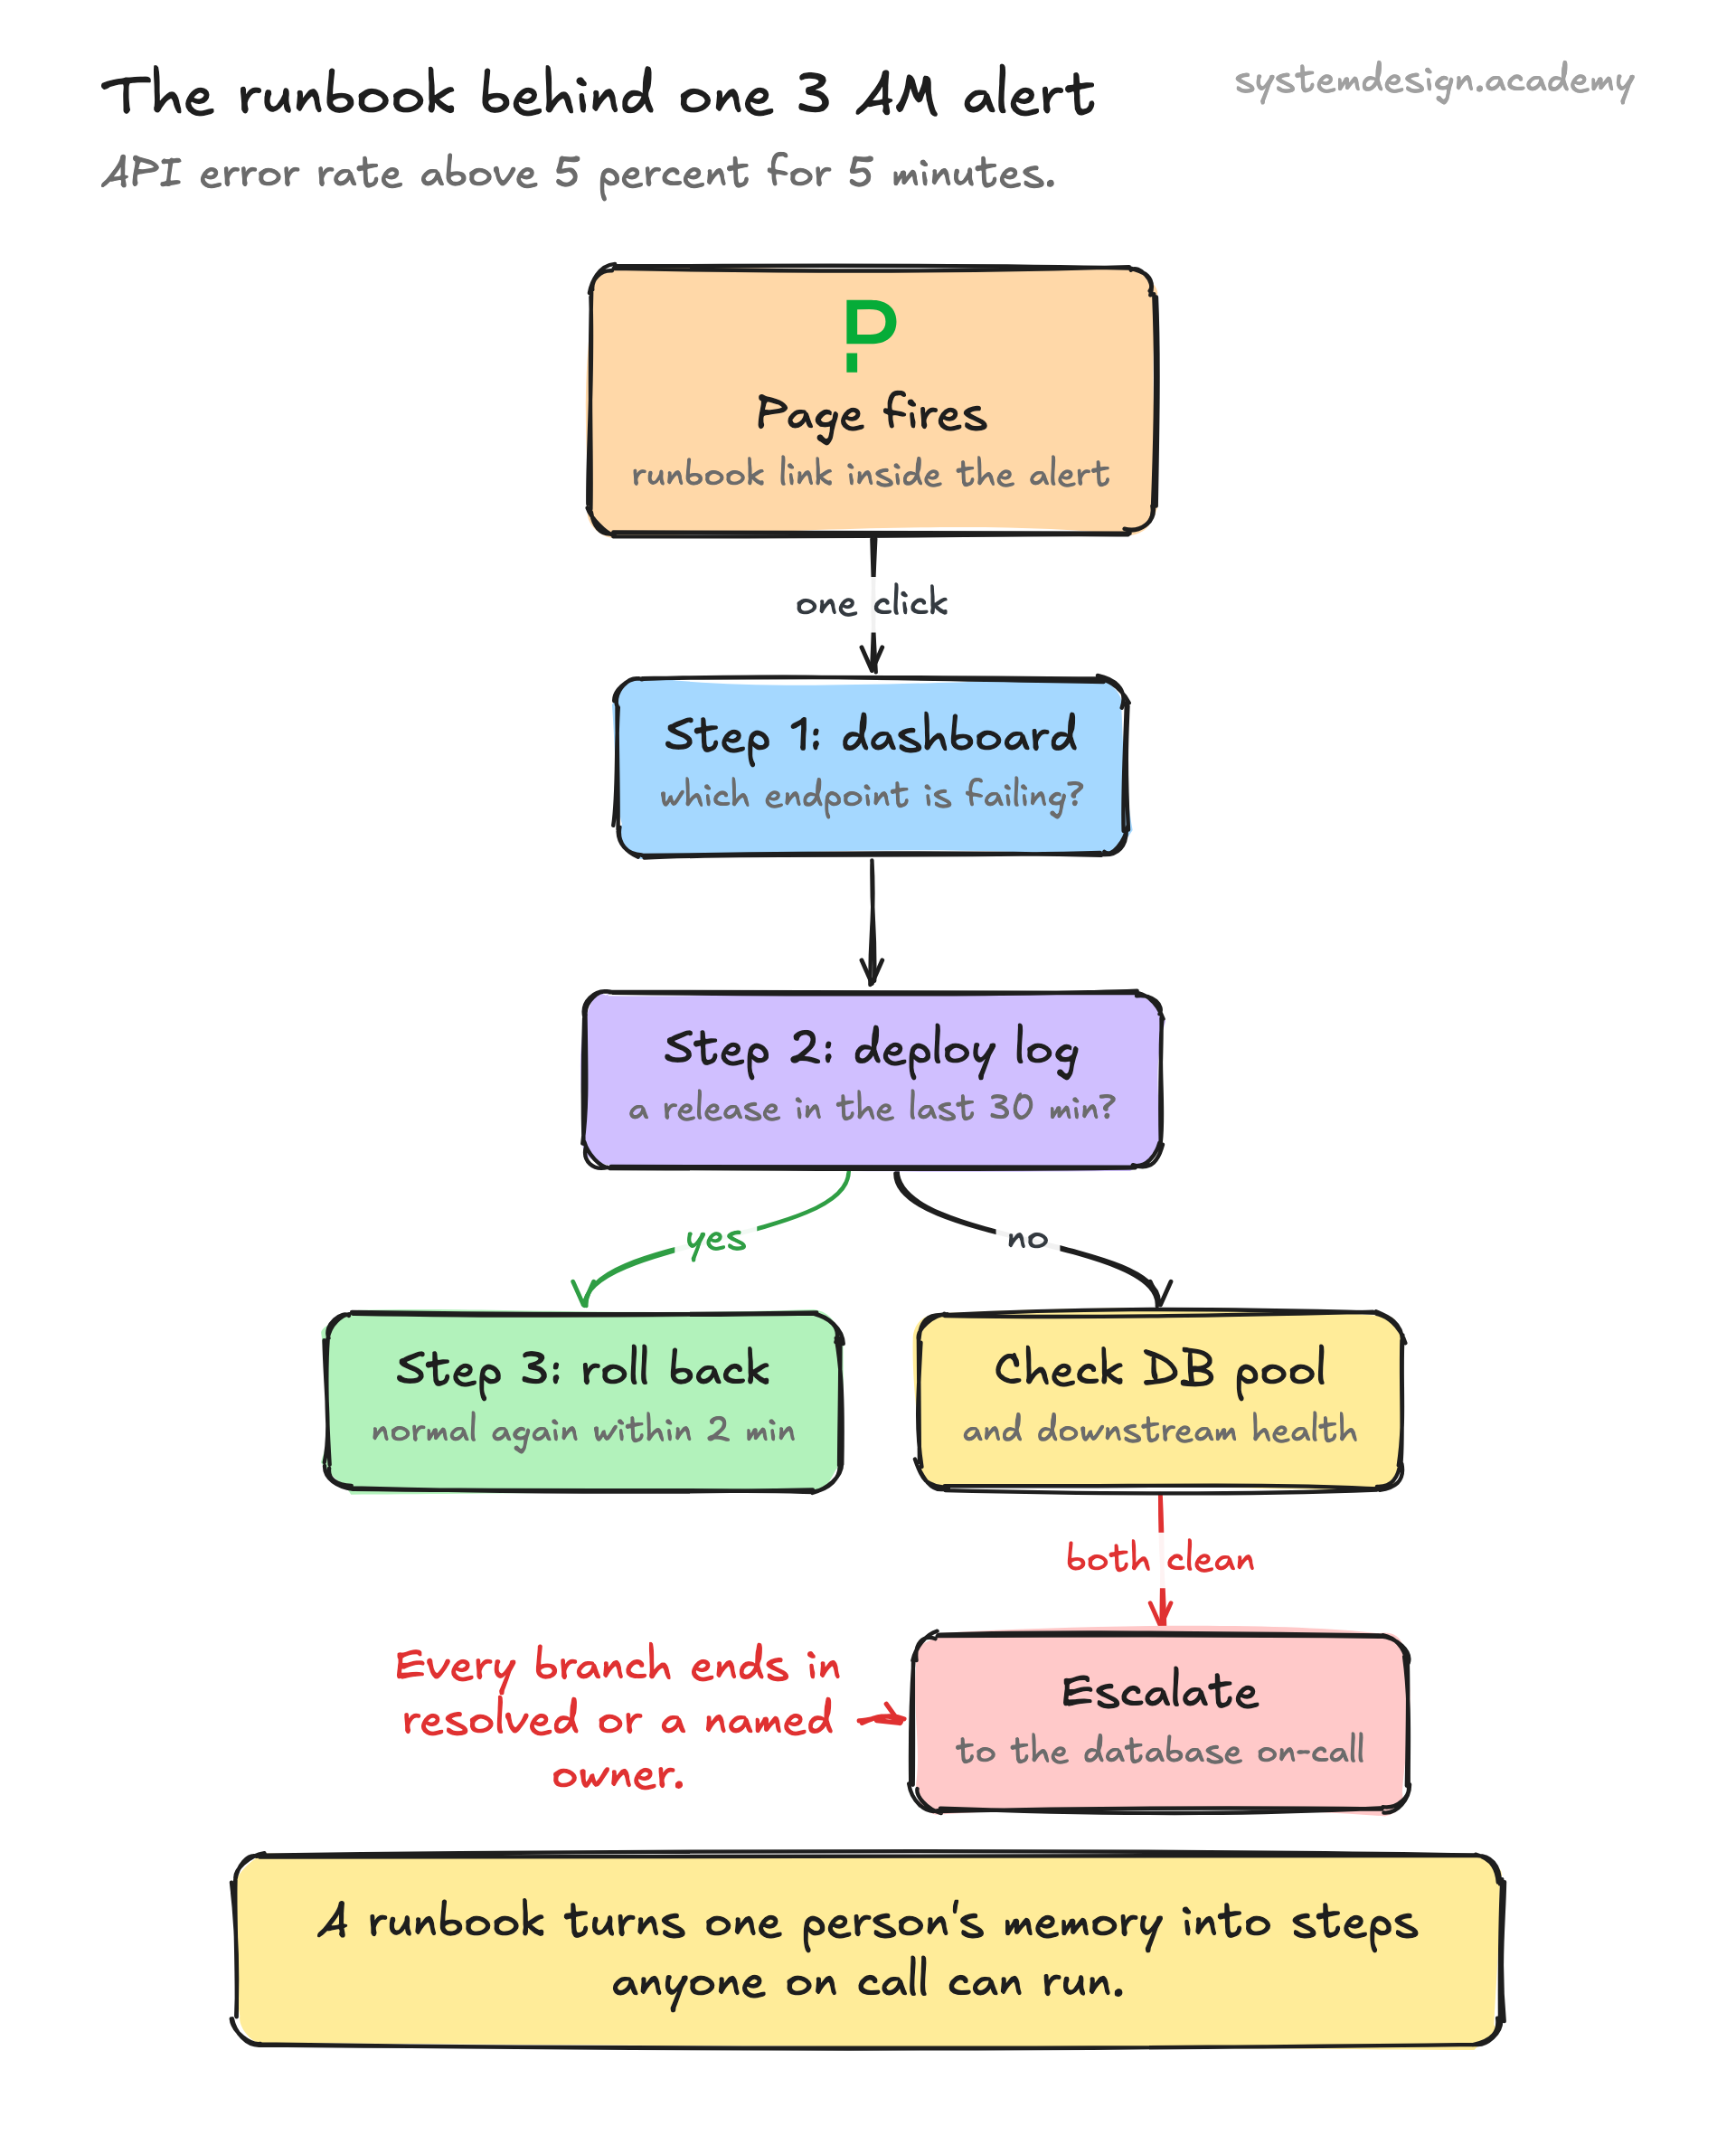
Write a runbook for any failure mode that has happened more than once, anything that pages a human, and any procedure that is risky or hard to remember (database failover, secret rotation, region evacuation). If a task is rare and trivial, a runbook may be overkill. If it is rare but catastrophic, you absolutely want one rehearsed in advance.
The main trade-off is staleness. A runbook that points to a renamed service or a deleted dashboard is worse than none, because it sends a stressed engineer down a dead end. Teams fight this by versioning runbooks in Git next to the code, reviewing them in incident postmortems, and running game days where engineers execute the runbook on purpose to catch rot.
Another failure is overconfidence in the steps. A runbook is a starting point, not a substitute for understanding. It should say why each step matters so an engineer can adapt when reality does not match the script, which during a real incident it often will not.