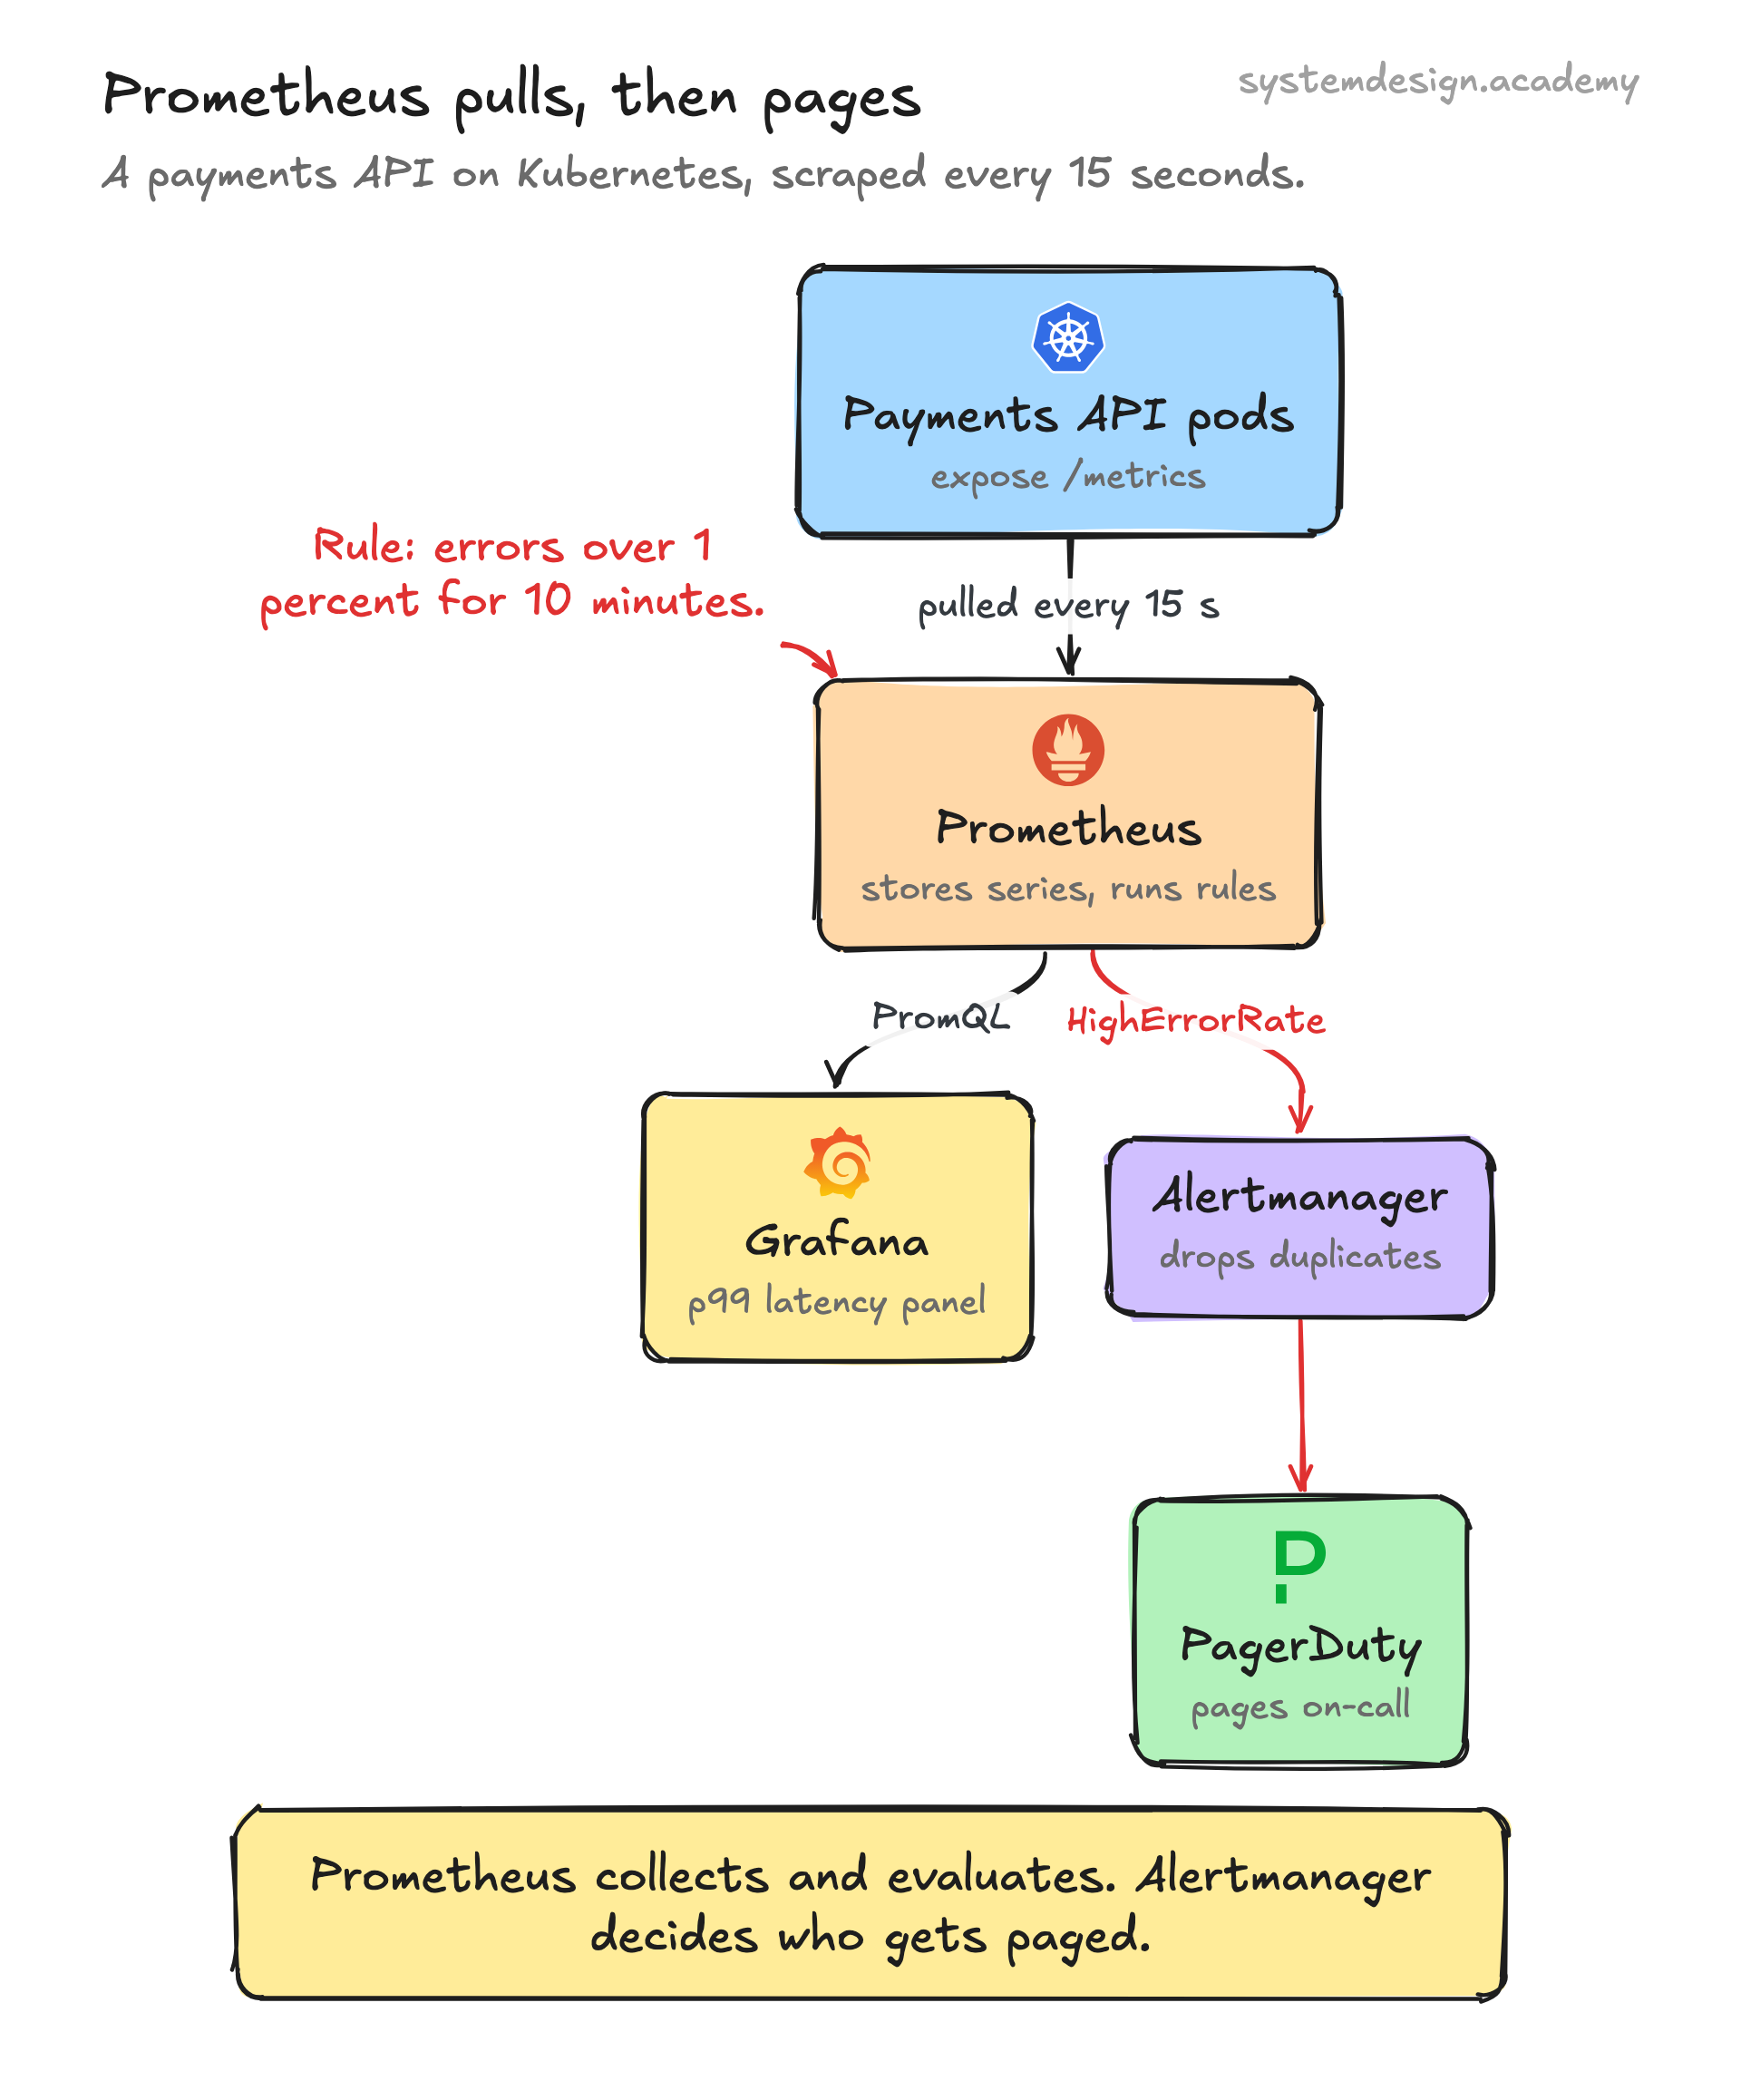
Prometheus is pull-based, not push-based. On a schedule (commonly every 15 to 30 seconds) the server scrapes an HTTP endpoint, usually /metrics, on every target. The target exposes its current metric values as plain text. This is the opposite of systems like StatsD where the application pushes data out.
Targets are found through service discovery. In Kubernetes, Prometheus watches the API server and automatically discovers pods and services as they come and go, so you do not hand-edit a target list. It also supports EC2, Consul, DNS, and static configs.
Samples are written to a local time-series database on disk. Recent data lives in an in-memory head block and is flushed to immutable two-hour blocks, which are later compacted into larger blocks. A write-ahead log protects against crashes. By default retention is 15 days because Prometheus is designed for recent operational data, not long-term archival.
Alerting is split out. Prometheus evaluates alerting rules written in PromQL and, when one fires, sends it to a separate component called Alertmanager, which handles grouping, deduplication, silencing, and routing to Slack, PagerDuty, or email.