What NVIDIA released: Nemotron 3.5 Super VL and Bolt
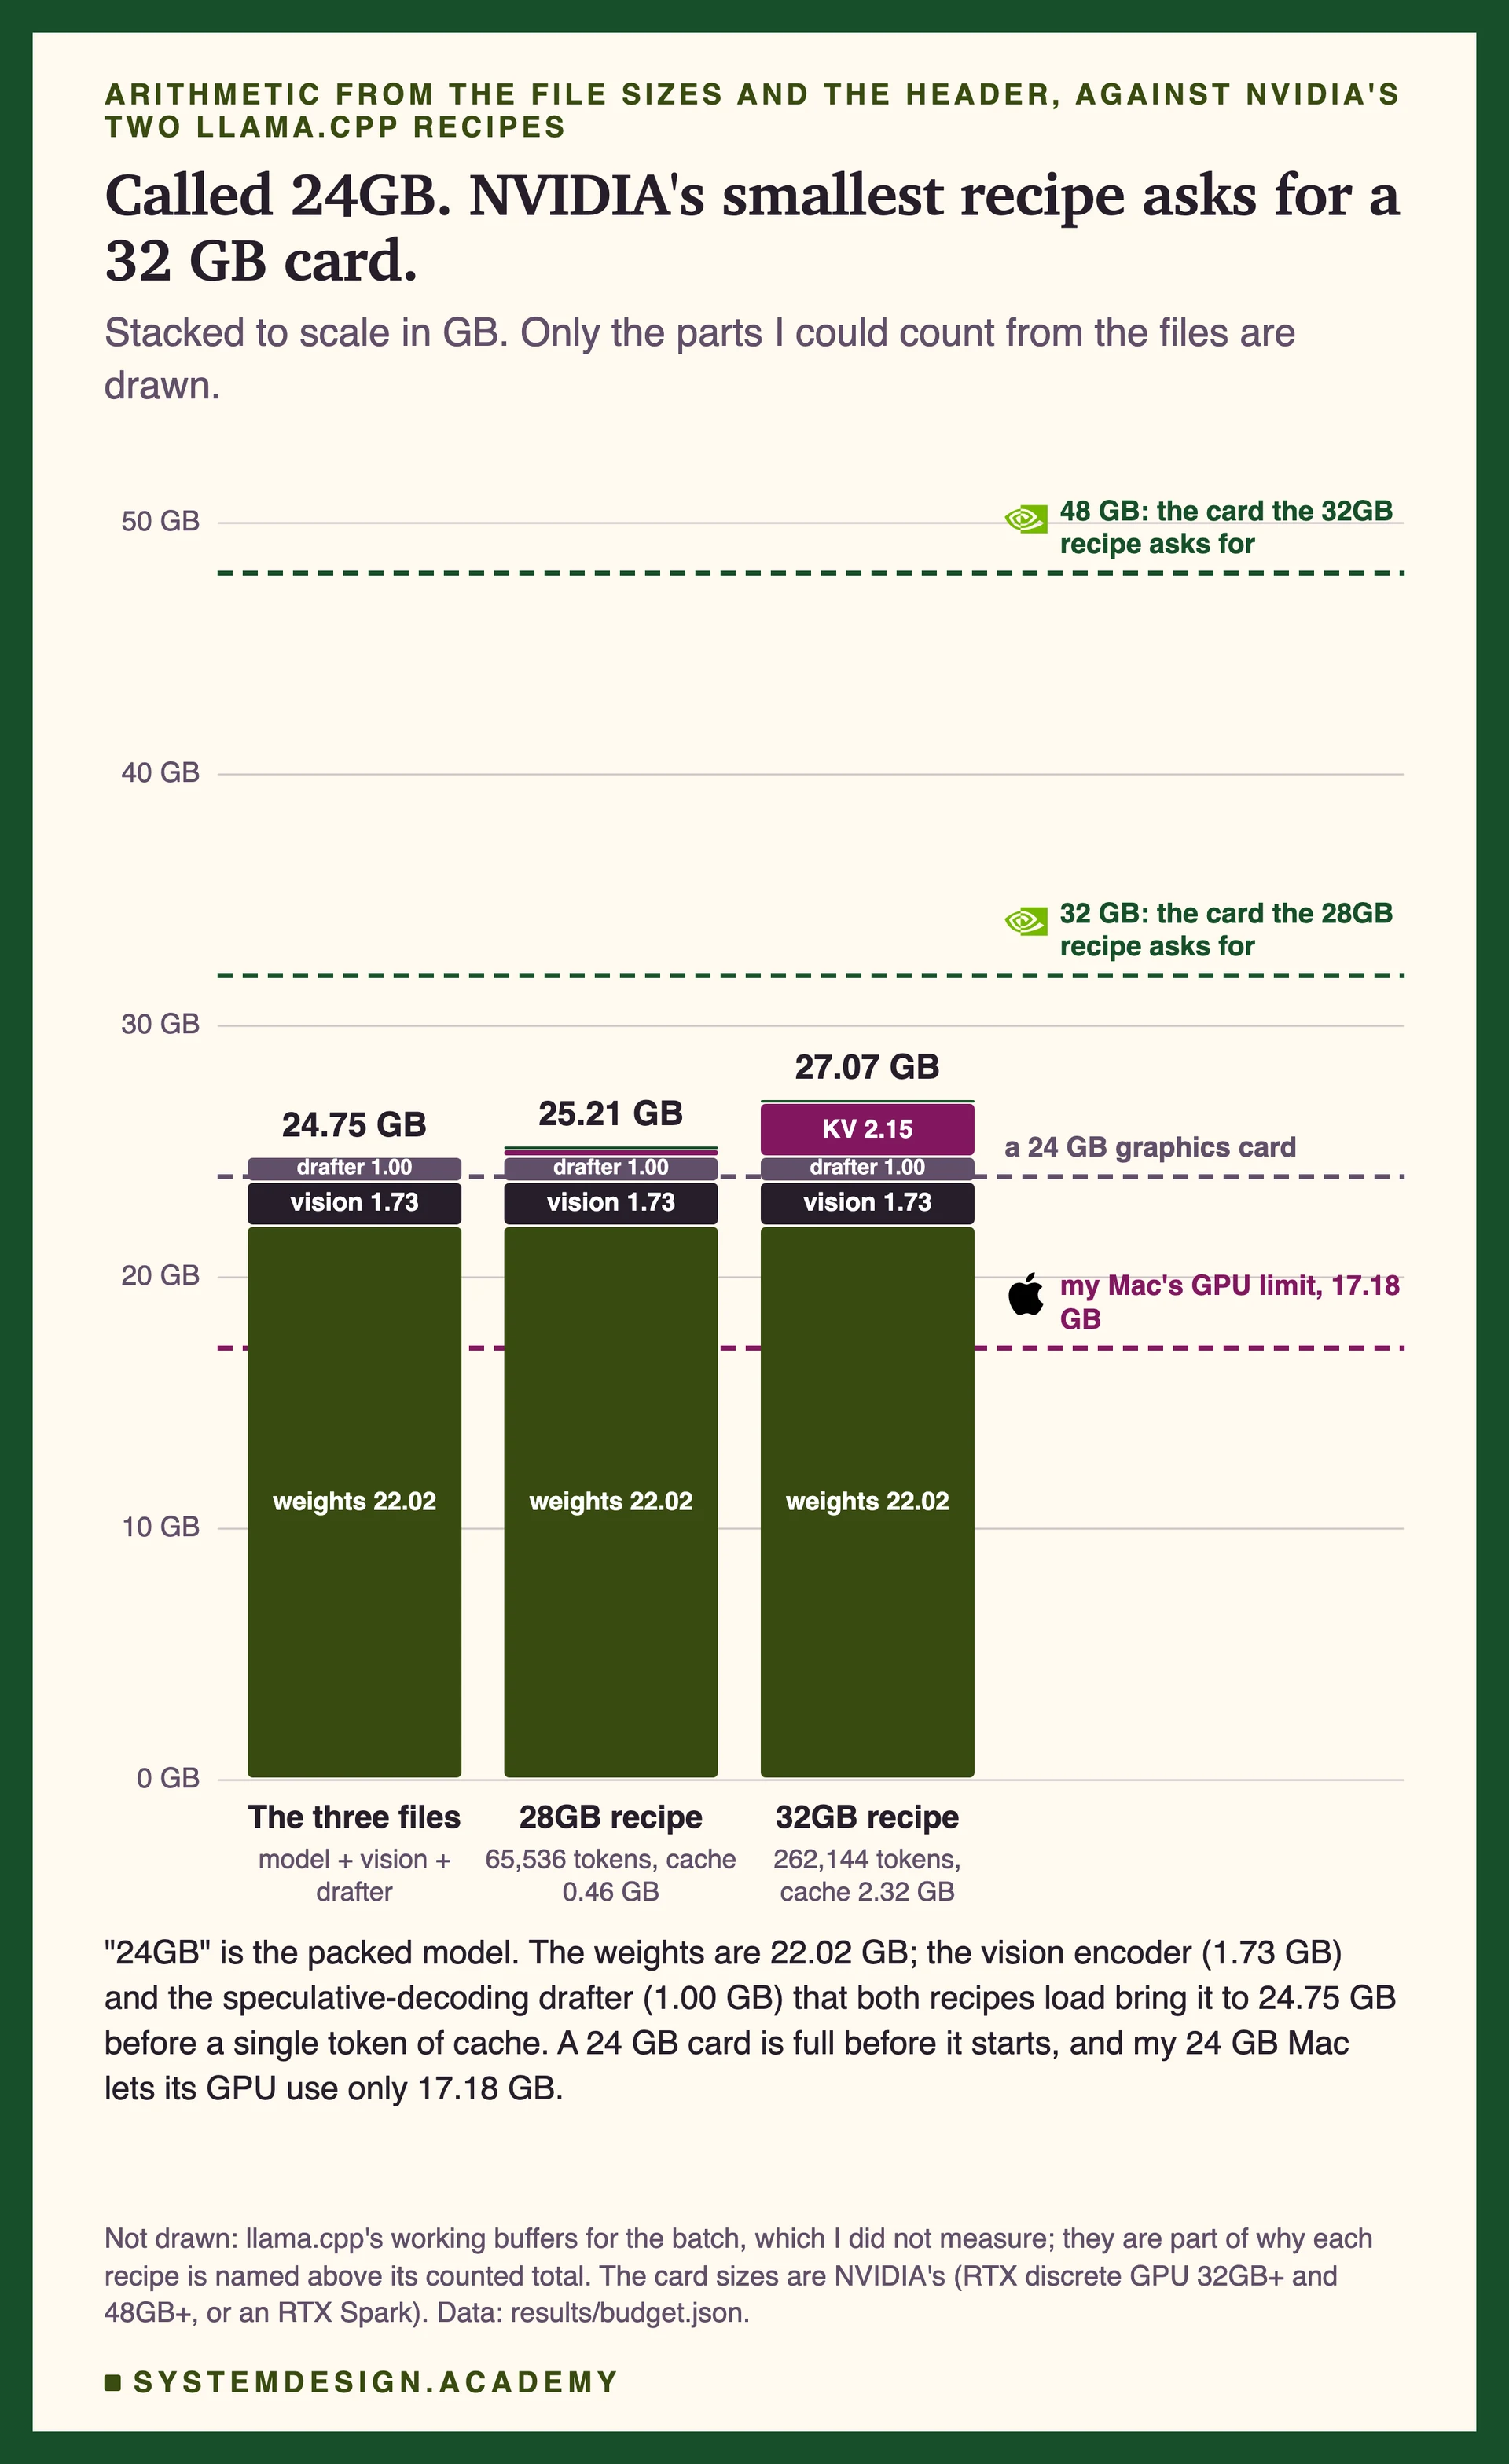
“We designed Nemotron 3.5 Bolt 74B-A9B to fit into 24GB of memory and achieve a decoding speed of at least 80 TPS, while maximizing intelligence.”
Nemotron is NVIDIA's family of open models. "Open" here means you can download the weights (the numbers the model learned) and, for Nemotron, much of the training data and the training recipes too. Before these came Nemotron 3.5 Lightning (30B total, 3B active), the first 3.5 chat model, whose files went up on Hugging Face in early August. On 15 October NVIDIA added two bigger ones, both vision-language models: they read text, images and video, and they write text.
Nemotron 3.5 Super VL has 120 billion parameters, of which 12 billion are active for each token. It is a mixture-of-experts model (MoE): instead of one big block of maths that every token passes through, each expert layer holds many smaller "experts" and a router picks a few for each token. So the model is large, but each token only costs the work of a 12B model. Super VL supports up to 1 million tokens of context, and at full precision NVIDIA lists it on 4 H100 GPUs or 2 GB200s. Its 4-bit version (NVFP4, NVIDIA's own 4-bit number format) runs on one H200, two H100s, one GB200 or one DGX Spark, NVIDIA's desktop AI computer.
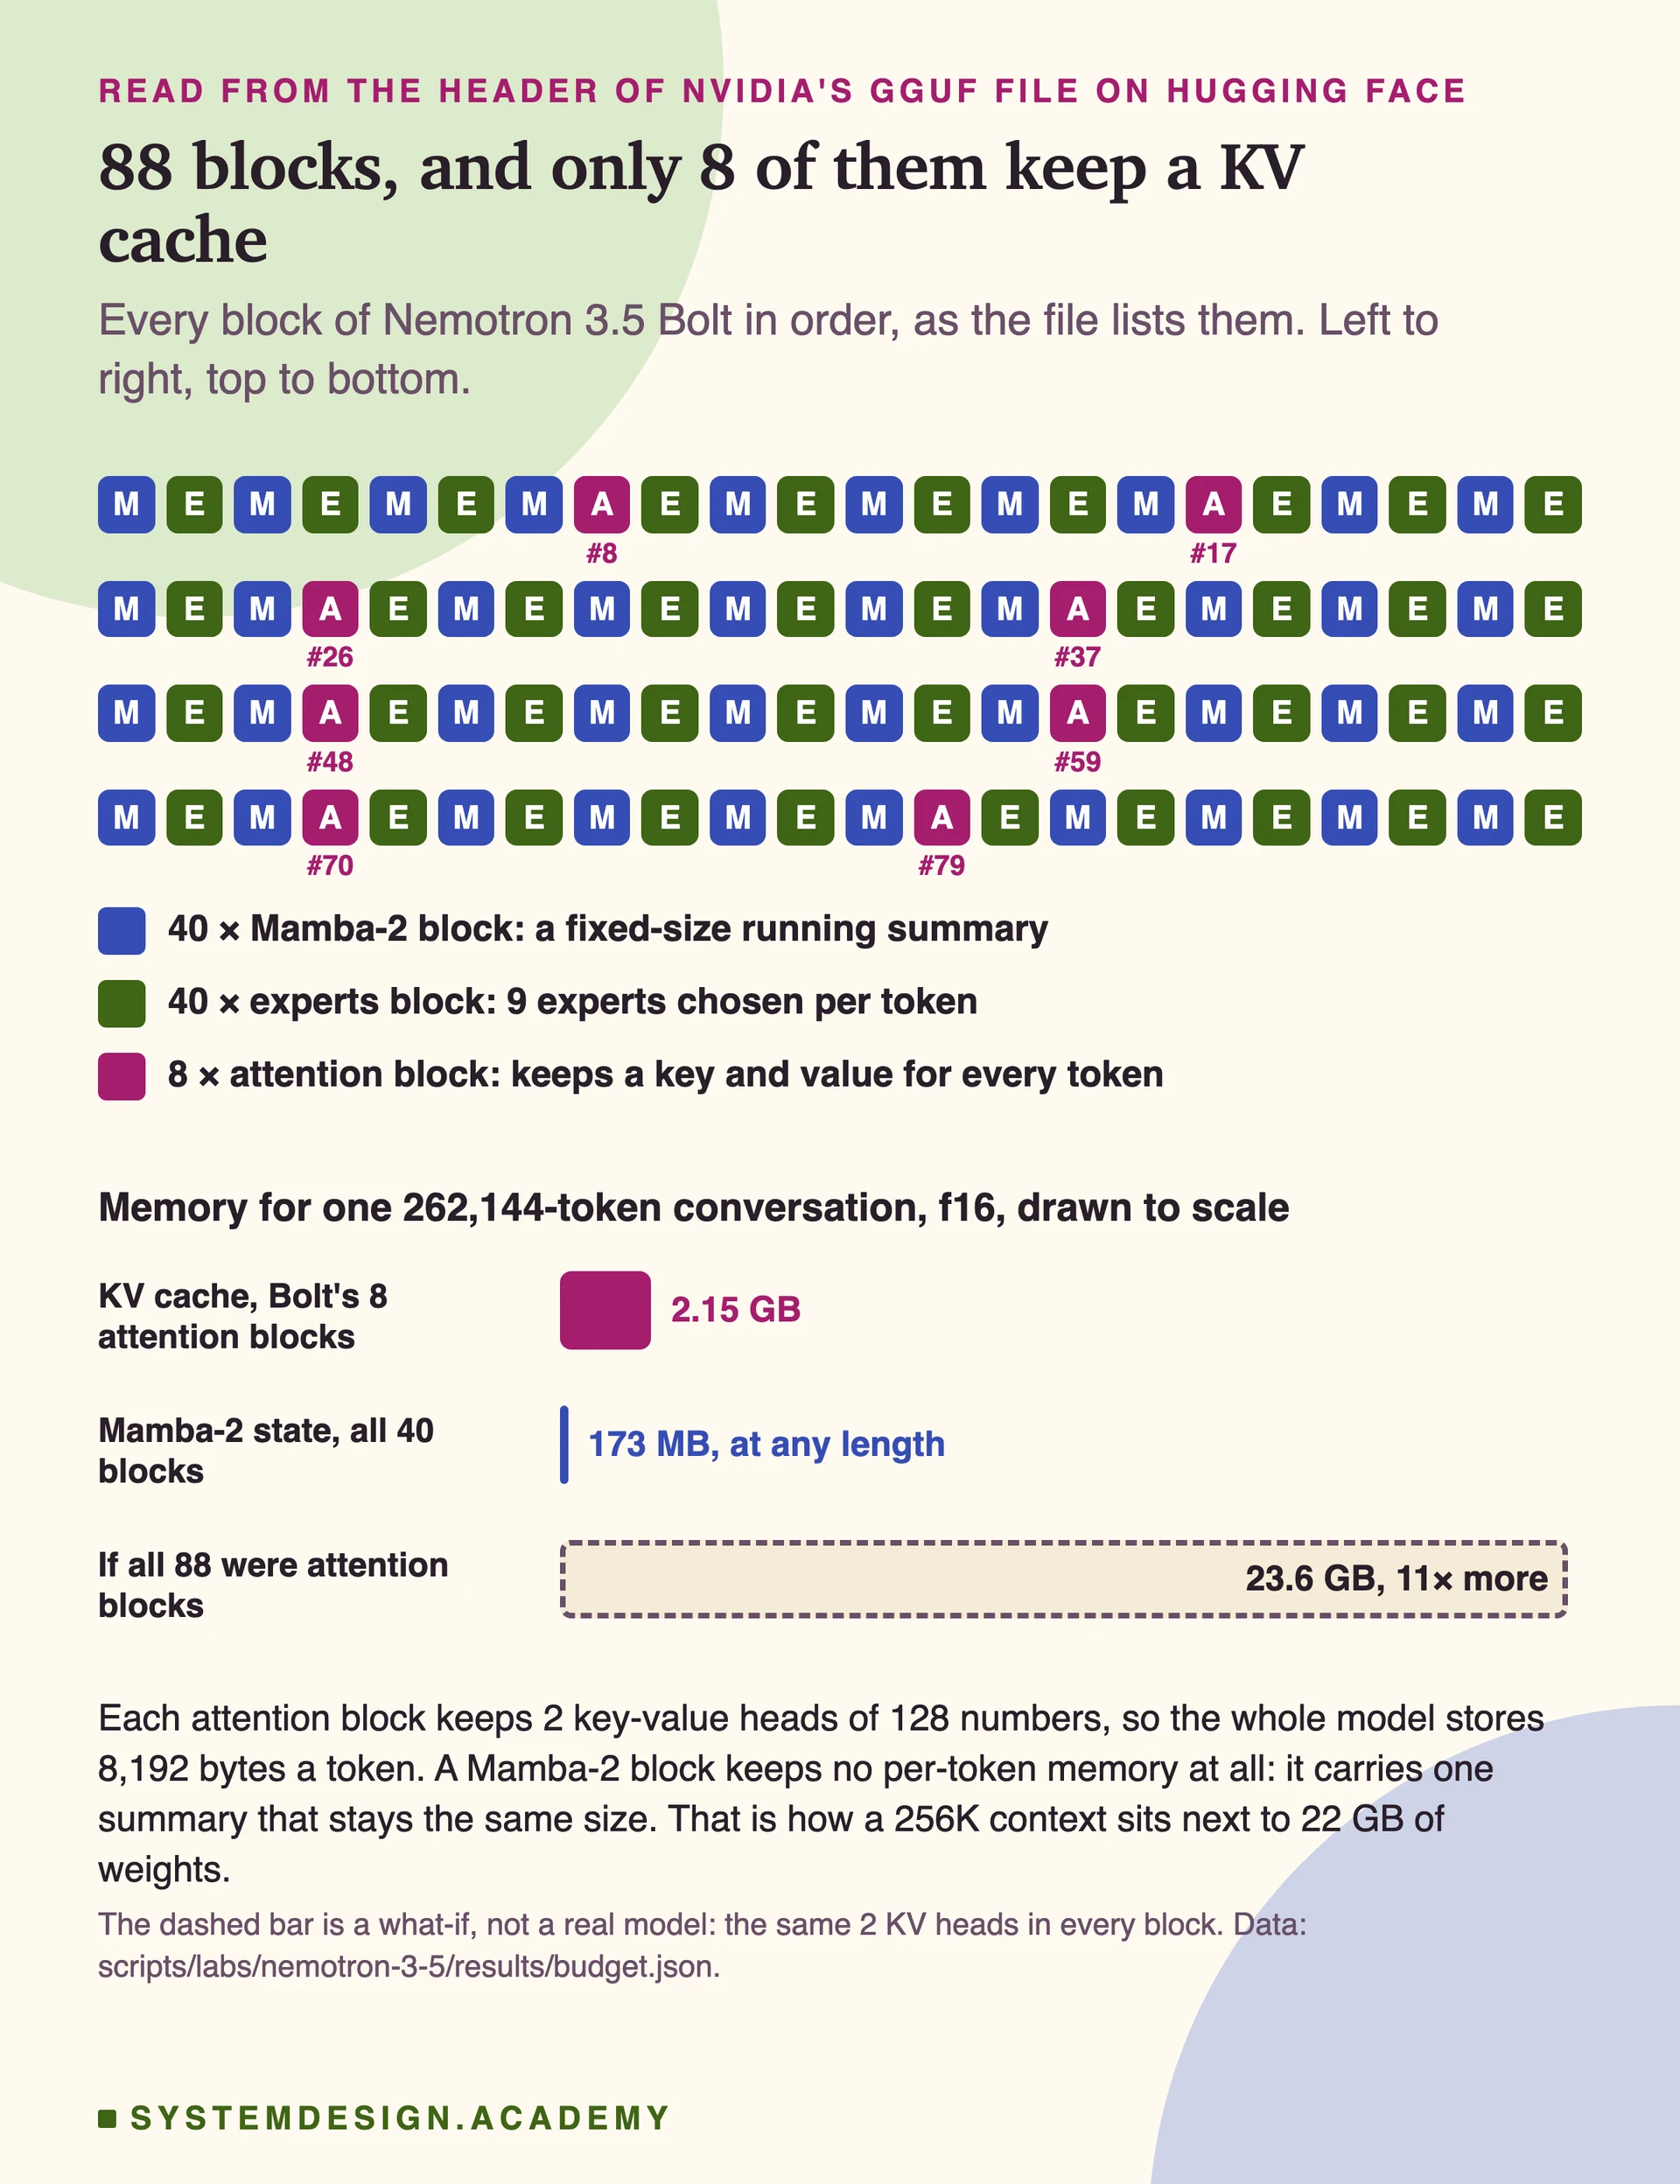
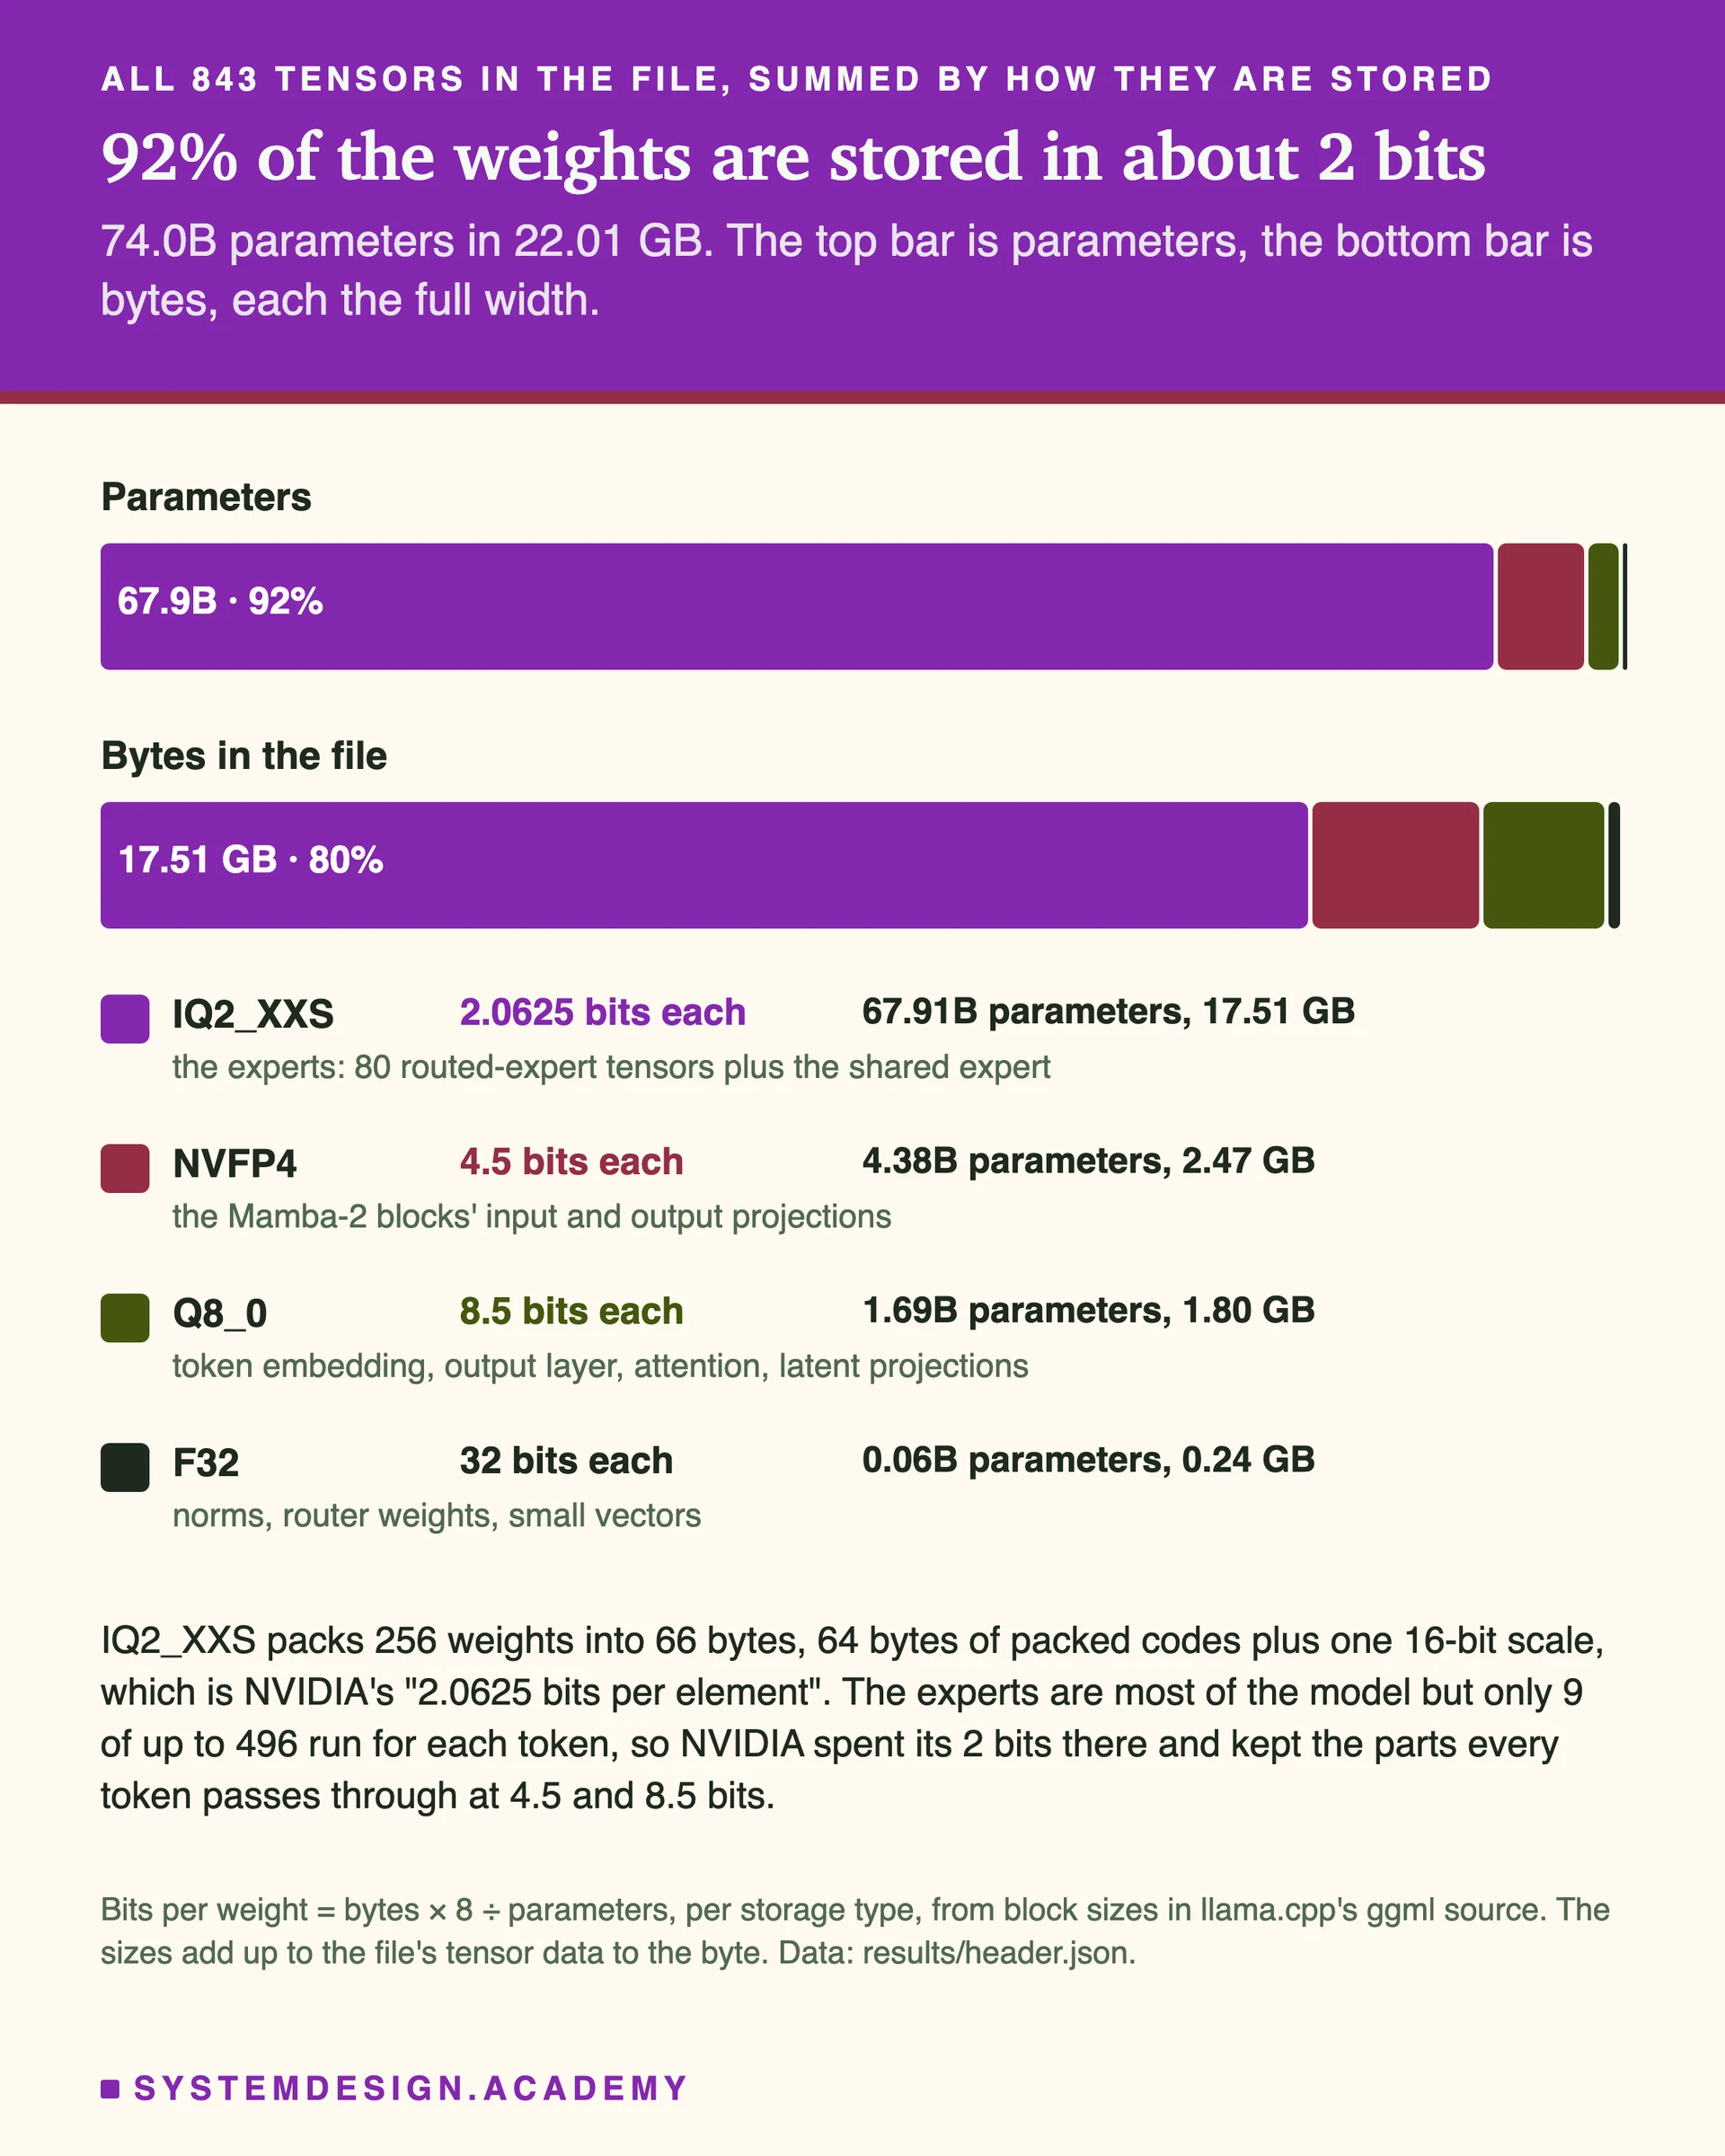
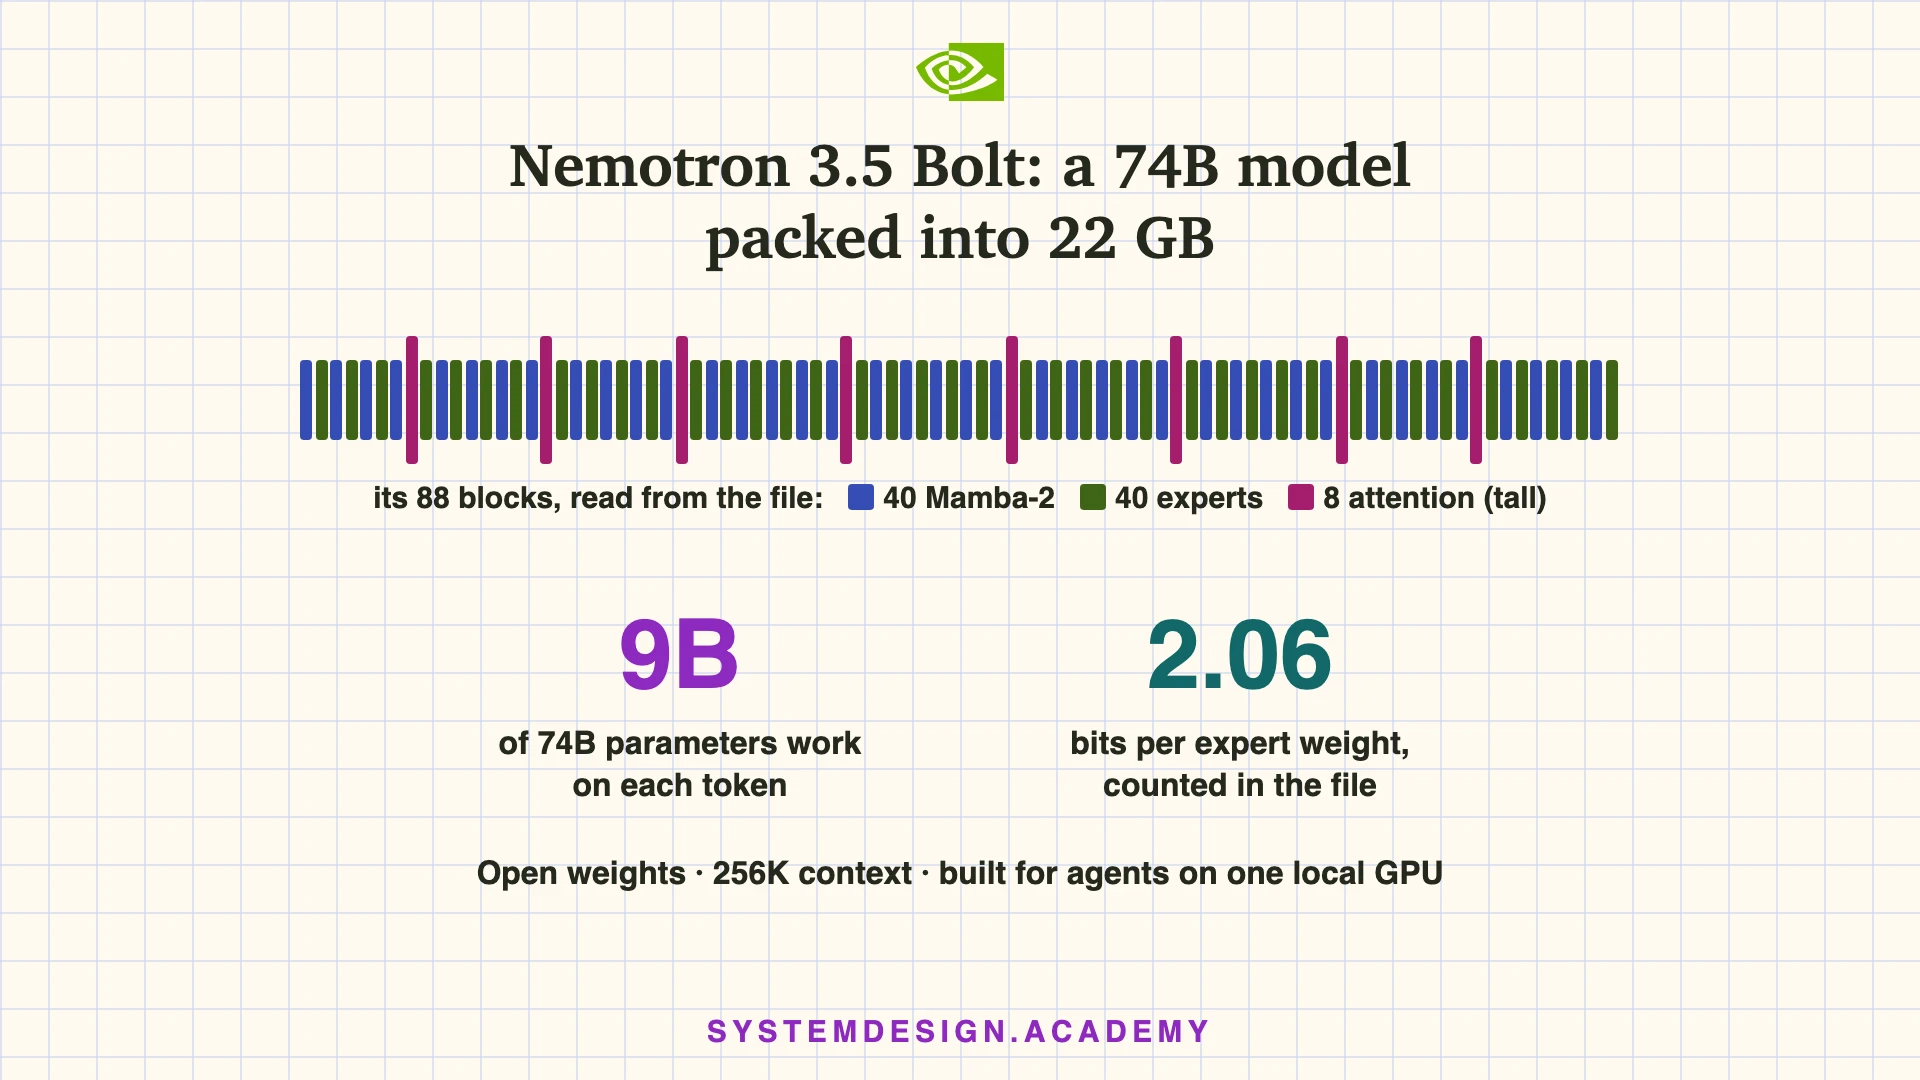
Nemotron 3.5 Bolt 74B-A9B 24GB is the one aimed at your own machine. NVIDIA's card says it is "designed to run everyday agentic tasks locally, using a native 2-bit quantization to fit in 24GB of memory and run alongside other applications." Quantization means storing each weight in fewer bits than it was trained with; 2 bits is very aggressive. It has 74 billion parameters, 9 billion active per token, and up to 256K tokens of context.
Both are under OpenMDW-1.1, a short permissive licence from the Linux Foundation's OpenMDW project. It lets you use, change and share the model "without restriction", commercially too, as long as you keep the licence and notices when you redistribute it. NVIDIA's Hugging Face page also lists new Nemotron 3.5 Embed and Rerank models from the same weeks, which are used for search rather than chat.