Inference Engineering · junior
What happens, step by step, when an LLM server handles one request?
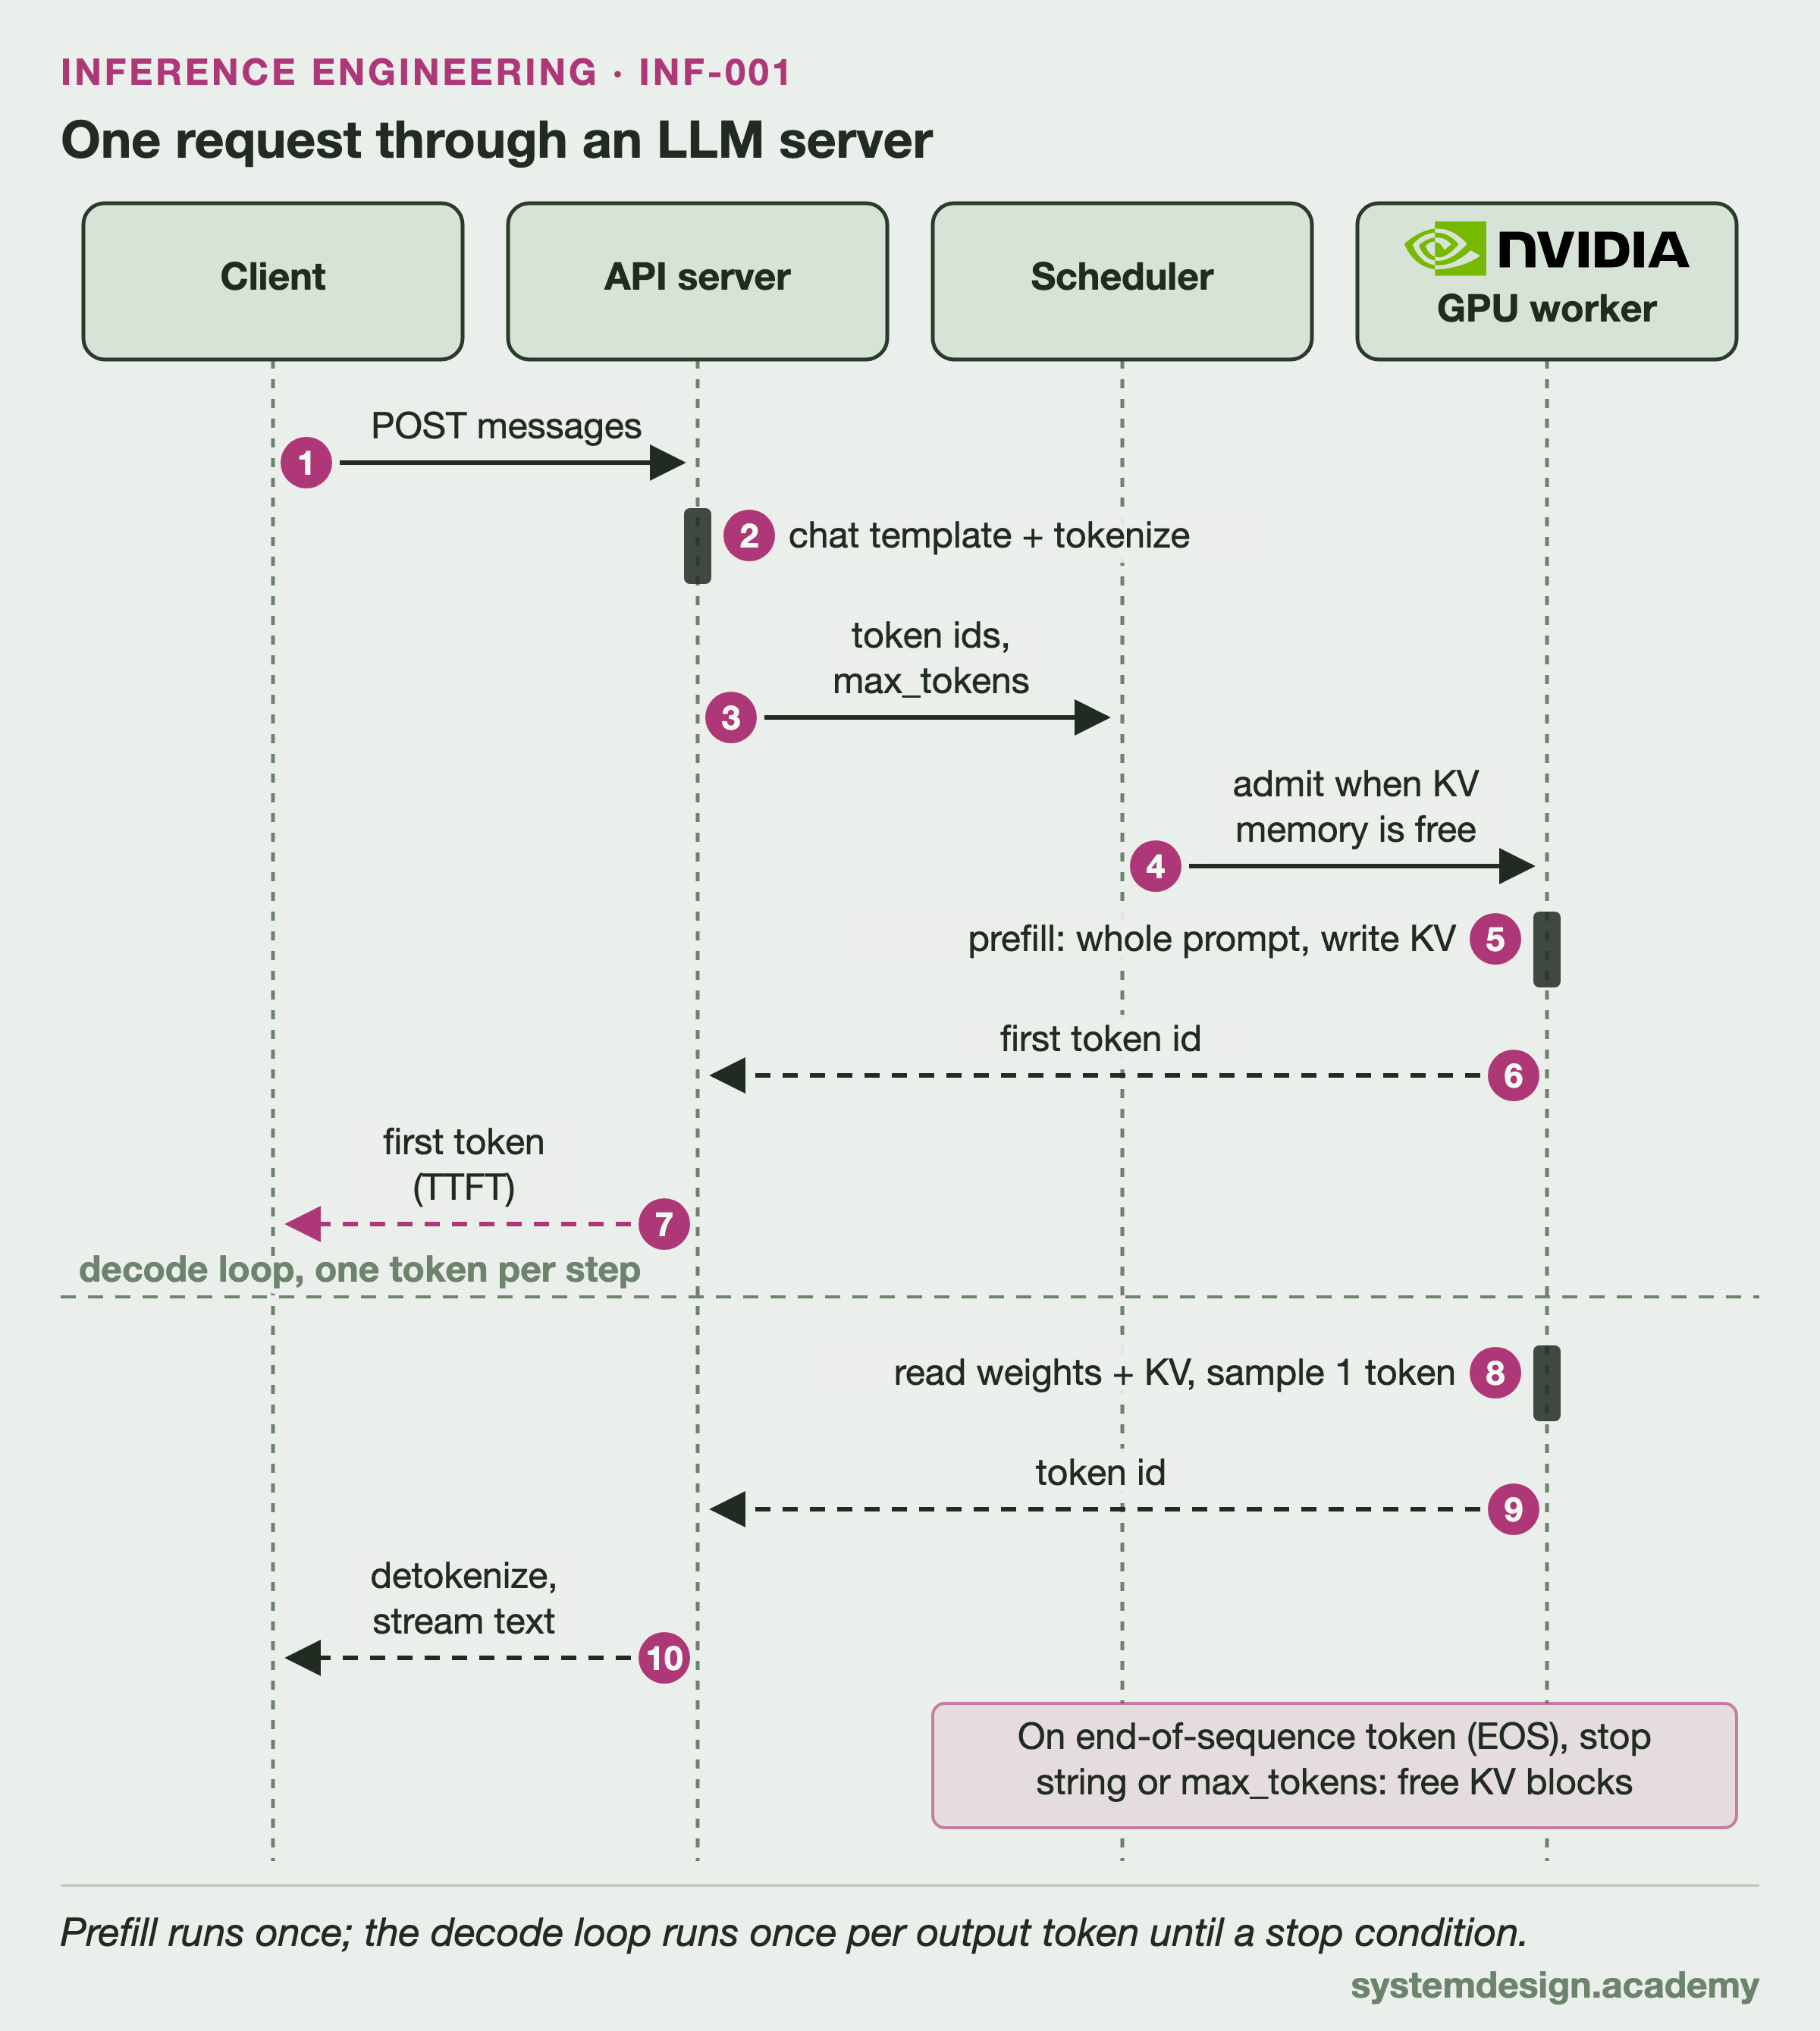
What the interviewer is testing: Checks that you know the full path of a request, not only the model call, and can say where time and memory go.
Read the full answer, free