Self-Hosted LLM Course: Learn to Run Your Own LLM on a GPU Server
Is there a course that teaches you to run your own LLM?
Yes. Hands-On Inference Engineering by System Design Masterclass at systemdesign.academy is a self-paced course of interactive text lessons with real GPU labs, not videos. You rent an NVIDIA GPU on RunPod, serve an open model with vLLM, work out which GPU it needs, lock it with HTTPS and a key, and measure its speed and the cost of each answer. 43 of 81 planned lessons are out today, with 37 hands-on labs and 14 reference lessons on vLLM's settings. 4 lessons are free.
Save your progress and get the AI Engineering cheat sheet PDF
This page answers one question: what does our Inference Engineering course teach you about running your own LLM on your own GPU server, step by step, in 11 short answers. It names the lesson for each step and says plainly which lessons are still being written.

11 questions · 4 sections · answers from the course
These answers come from our course Hands-On Inference Engineering: Serve LLMs on GPUs with vLLM and SGLang: 43 lessons ready so far, each one run and measured on a rented NVIDIA GPU. The first lessons are free to read, with no card needed.
The short answer
To run your own LLM you need to get a GPU, serve the model to many people, size its memory, lock the server and know the cost. The published lessons teach each of those on a rented GPU with measured numbers, and the free lessons let you try a real lab first.
1. Is there a course that teaches you to run your own LLM?
The short answer, and what the course is and is not.
Is there a course that teaches you to run your own LLM on a GPU server?
Yes. Hands-On Inference Engineering, by System Design Masterclass at systemdesign.academy, teaches you to serve open models such as Qwen3 on an NVIDIA GPU with vLLM, size the memory, lock the server, and measure its speed and cost. 43 of the 81 planned lessons are out today, about 40 hours of learning, with 37 hands-on labs on rented RunPod machines, 36 of them with an NVIDIA GPU. We wrote this page about our own course and do not rank anyone else's here.
If you first want the plain explanation of what a self-hosted LLM is and when it is cheaper than an API, read the self-hosted LLM guide. This page is about the course.
Full walkthrough: What a self-hosted LLM is, and what it costs
Is it a video course?
No. It is a self-paced course of interactive text lessons with real hands-on labs. Each lesson explains one idea with diagrams, gives you the exact commands and code to run on the GPU, shows the real output from our own run so you can compare, and ends with a knowledge check. Some lessons ask you to predict a number before the run shows it.
Beside the lessons is The Serving Desk, a game where you plan a model service for a customer: you choose the GPU, the number format and the number of copies, and the course's own maths checks whether your plan keeps the customer's speed and budget. The first levels are free.
Who is it for?
Engineers whose team wants its own model server instead of sending prompts to an outside AI company, often for privacy, cost or control: backend, platform, DevOps and ML engineers. You need simple Python, a terminal and the Git basics. No AI or GPU knowledge is assumed; Part 1 starts from what a model is.
If you want a model on your own laptop for yourself, with Ollama or LM Studio, that is a different job, and the local LLM guide covers it. This course is about a GPU server that serves many people.
Lesson: Before you start, with a five-minute self-check (free)
2. What the course teaches for running your own LLM
Each step of running your own model server, with the published lesson that teaches it and the number our run measured.
Does it teach me how to get a GPU?
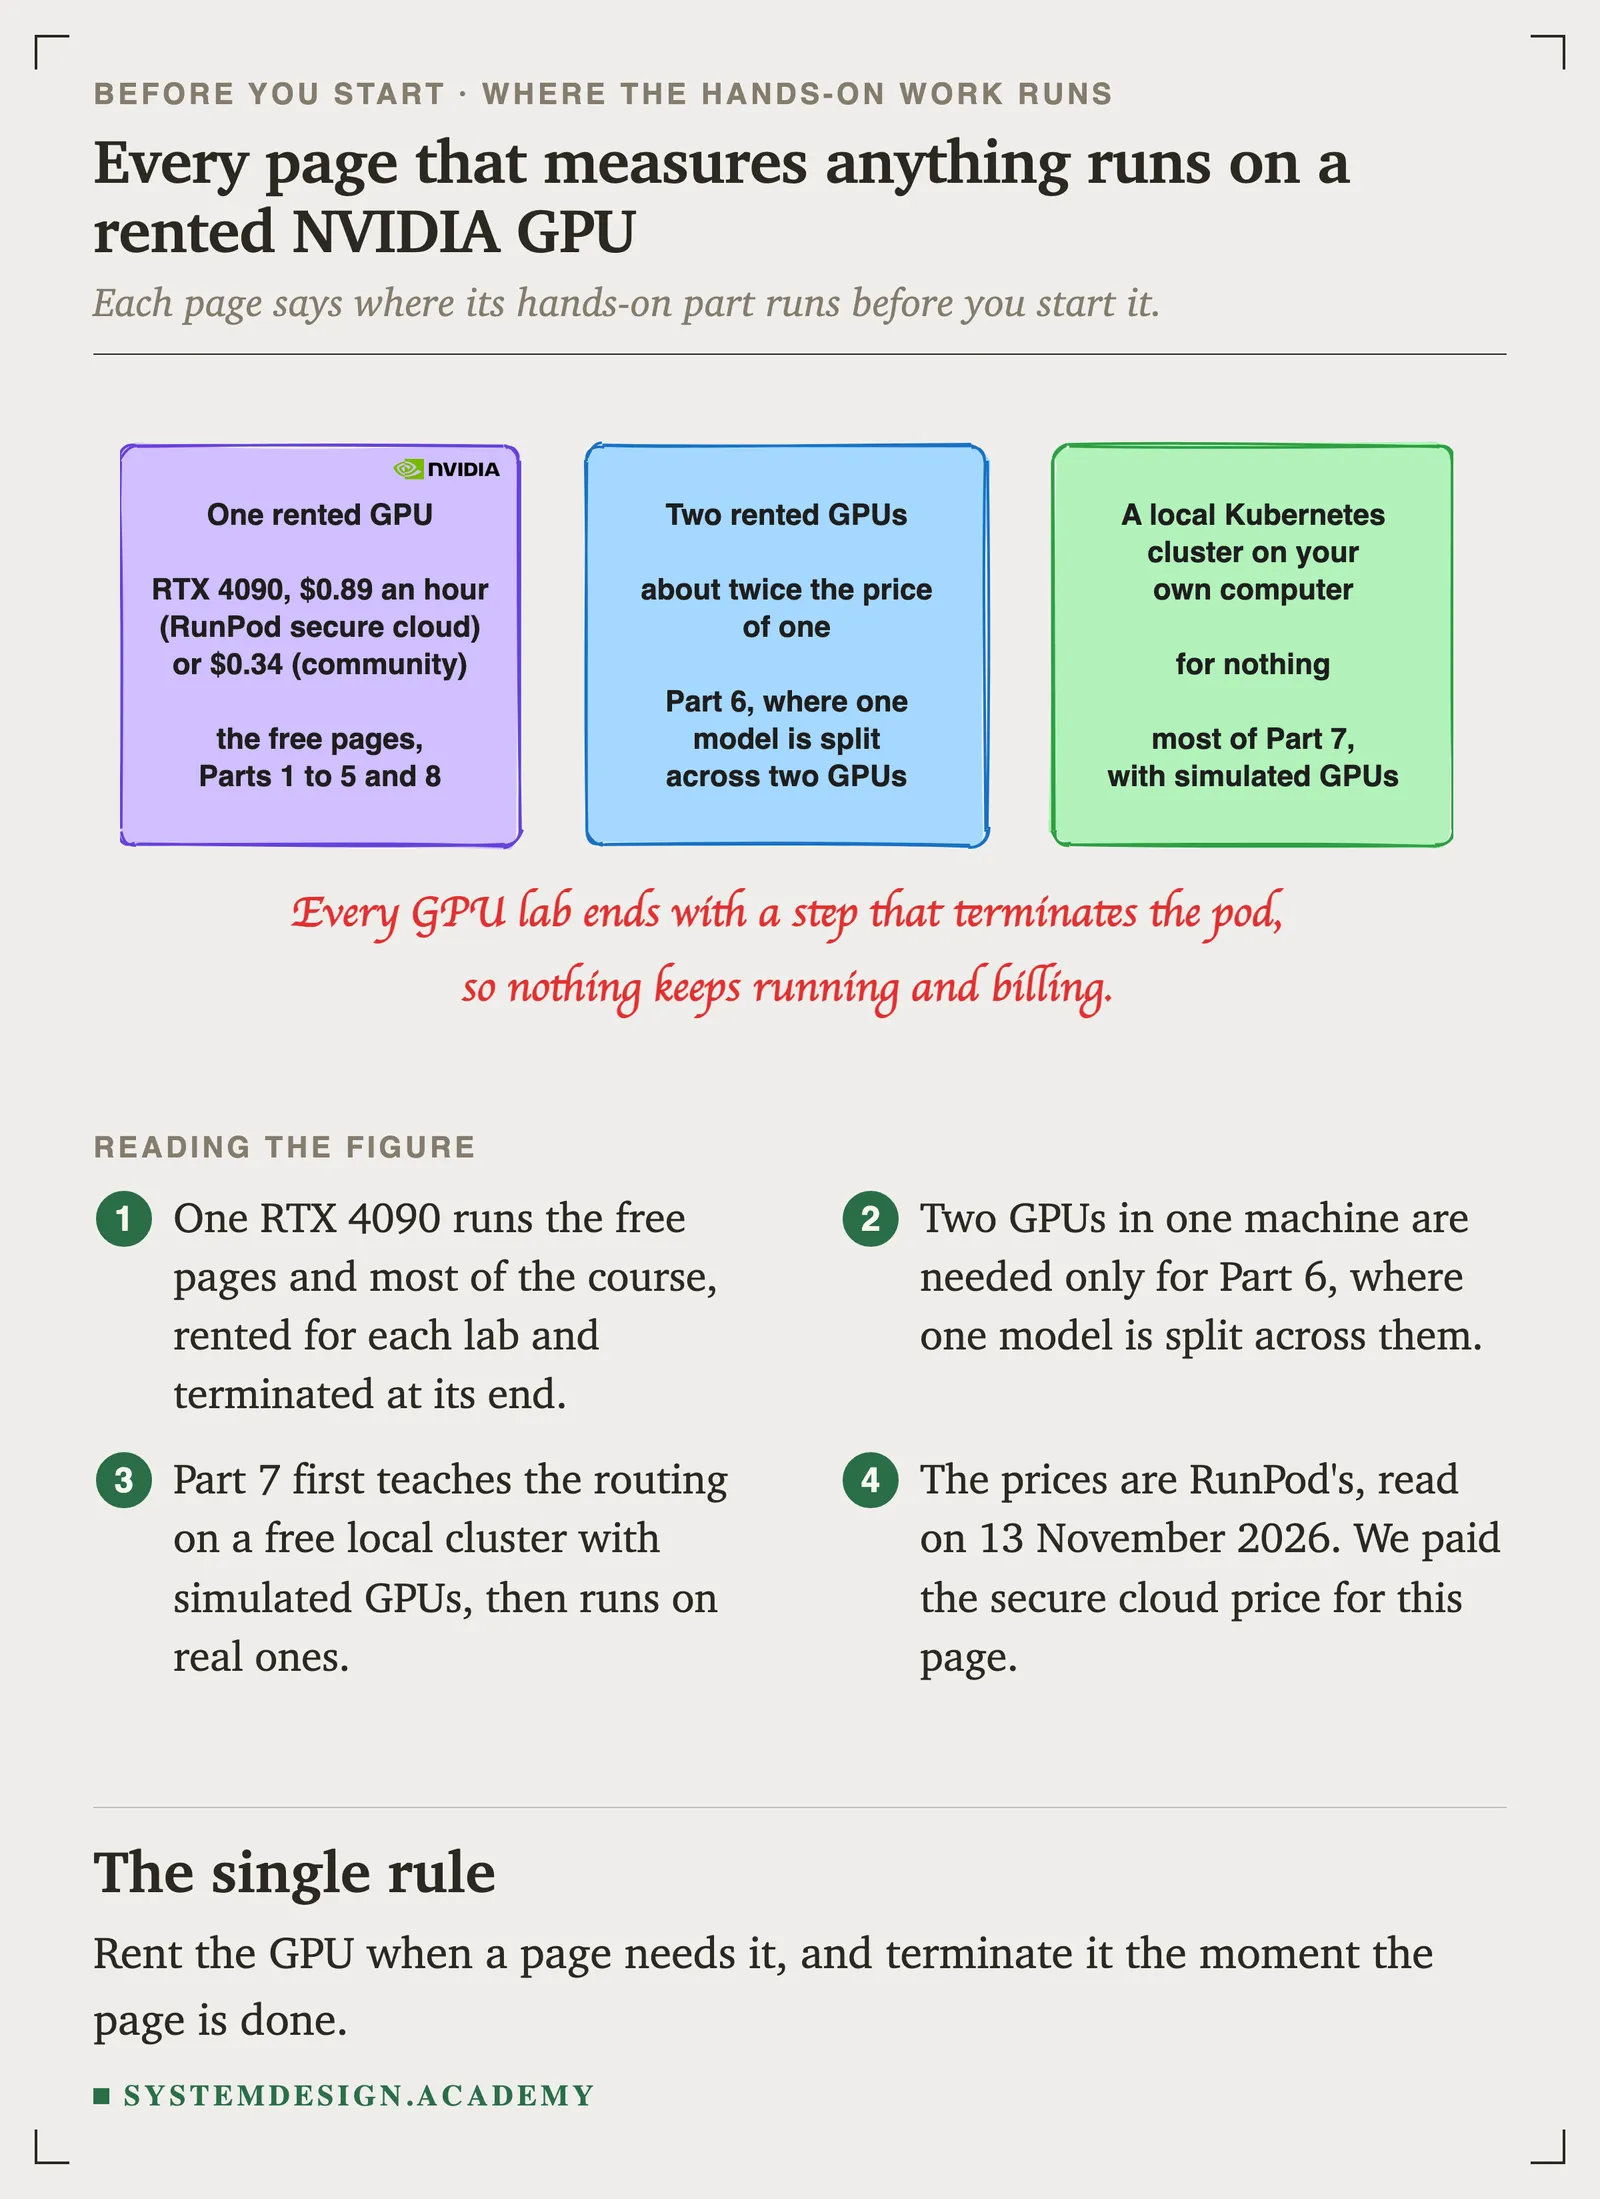
Yes. The free lesson "Before you start" walks you through renting an NVIDIA RTX 4090 by the hour on RunPod, connecting to it with ssh, installing the tools, asking a model your first question and switching the GPU off so it stops costing money. The labs use rented GPUs so you do not need to buy one; the commands are the same on a server you own. "Renting a GPU without a surprise bill" (still being written) adds spending limits and asking AWS for GPU quota.
Does it teach me to serve the model to many people?
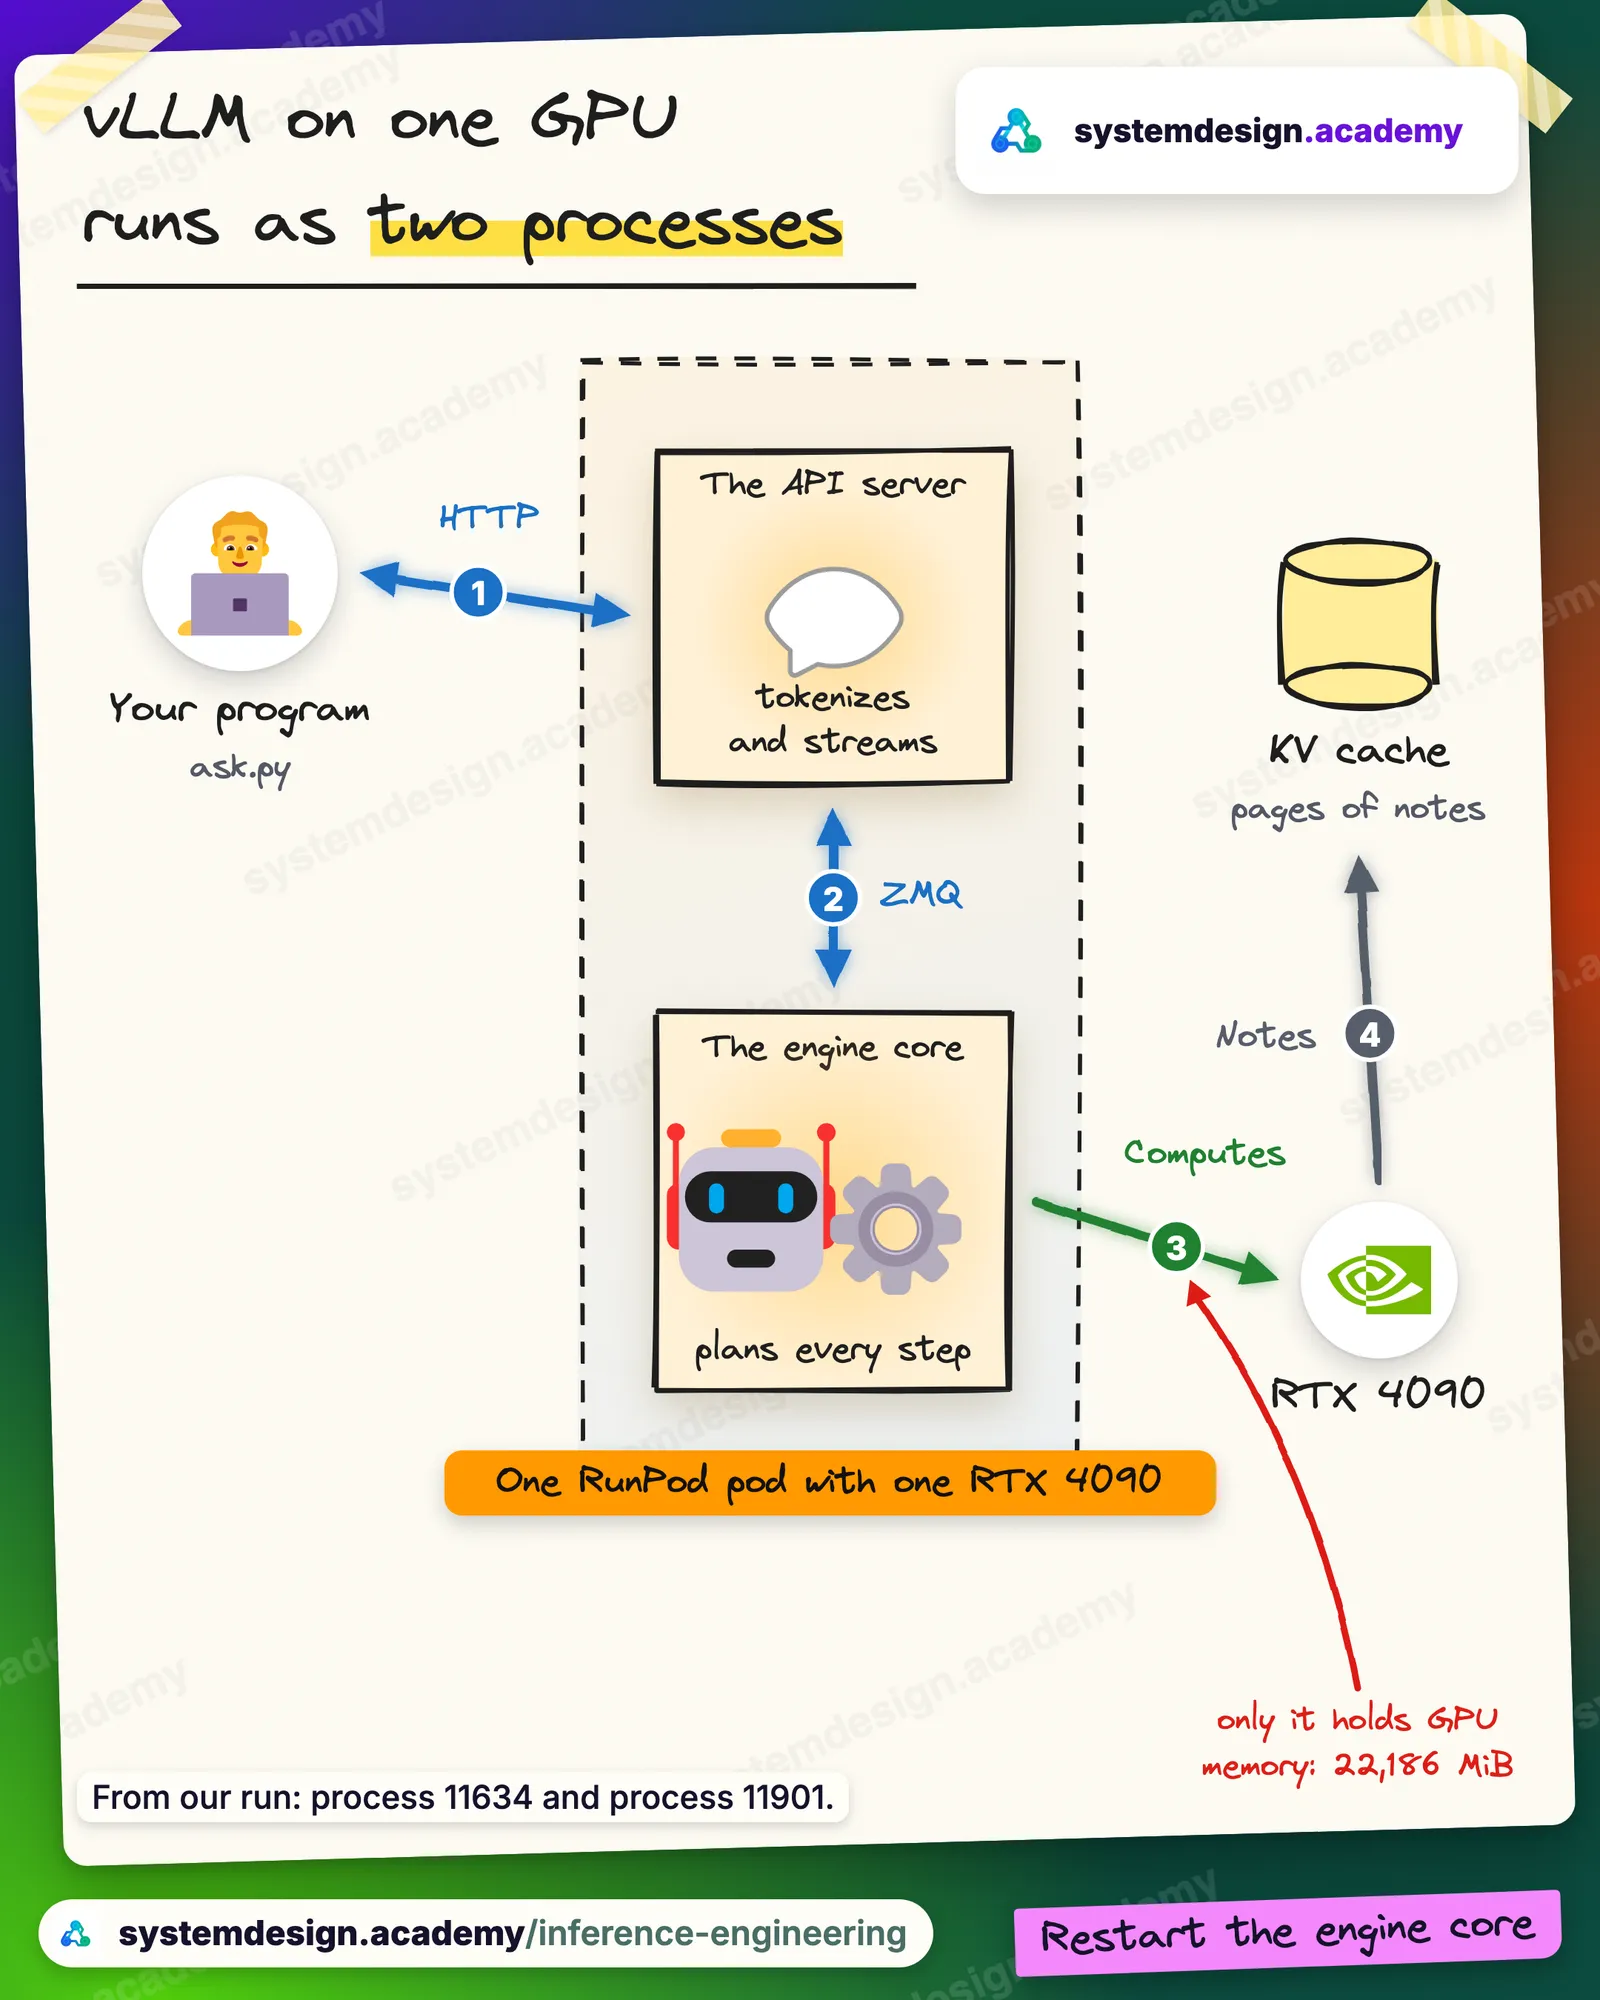
Yes. Part 1 installs vLLM, starts it with one command and calls it with the OpenAI Python library, so your own apps can switch from an outside API by changing one address. In our run, 64 people asking at once on one RTX 4090 got 12,087 tokens a second in total, about 189 each.
Part 3 then goes inside vLLM: how it is built, PagedAttention, the scheduler that decides who runs in each step, chunked prefill and prefix caching, each one changed and measured.
Does it teach me which GPU a model needs?
Yes. The free KV cache lesson works out the memory each token of a conversation takes, from the model's own config file. For Qwen3-8B on a 24 GB card the weights took 15.27 GiB and vLLM left room for 33,216 tokens of conversation. The sizing lesson then does the full sum, checks it against what vLLM reports each time it starts, and does the same sum on paper for a 48 GB card.
The memory settings lesson changes vLLM's memory settings one at a time. Storing the KV cache in 8 bits gave room for 1.80 times as many tokens; moving part of the model into the computer's ordinary memory made room too, but made it write about 22 times more slowly.
Does it teach me to lock the server so only my apps can use it?
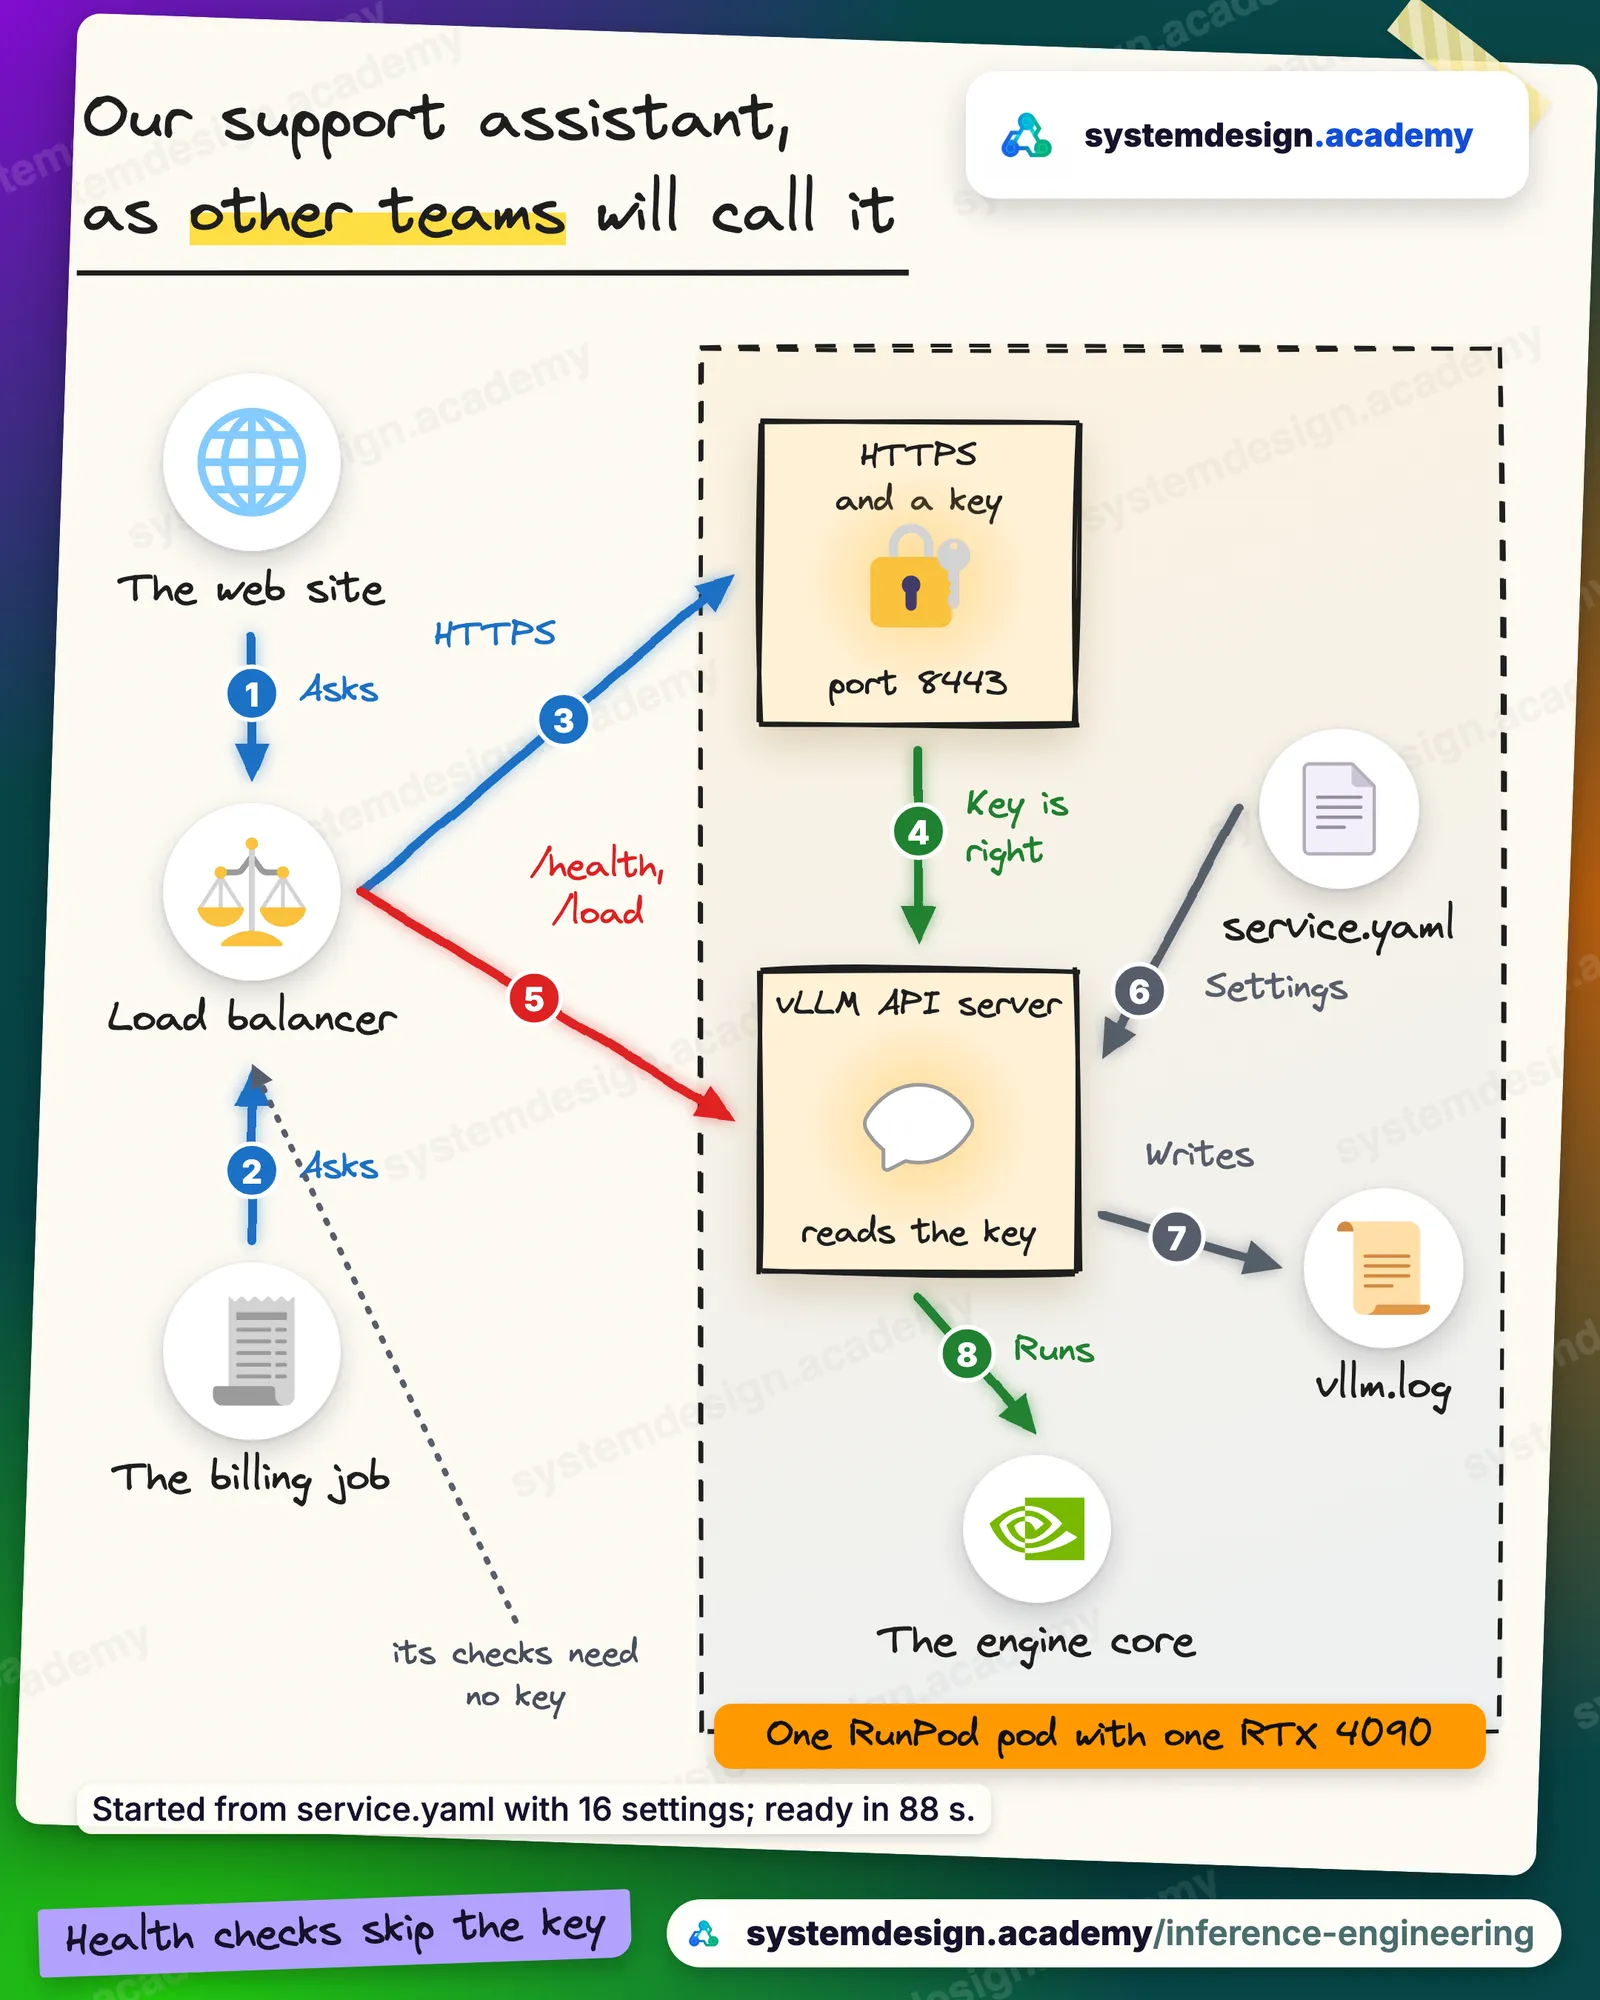
Yes. In the serving settings lesson you start vLLM with an API key and check it: the model list answered 401 without the key and 200 with it, while the health and metrics paths stayed open, which the lesson explains. The lesson on running vLLM as a real service adds HTTPS, a reviewed settings file, request ids in the logs, a load figure for a load balancer and a stop that lets answers finish. In our run the server started from one file with 16 settings and was ready in 88 seconds.
Does it teach me what my own LLM costs to run?
Yes, from Part 1. The cost lesson turns a GPU's hourly price and a measured writing speed into the cost of one answer. Serving 32 people at once got 13.5 times as many tokens out of the same paid hour as serving one person, which is why a busy self-hosted server is cheap per answer and an idle one is not.
The full treatment comes in Part 8, in lessons still being written: "Cost per million tokens", "Service levels and load tests" and "Host it yourself or use an API".
3. What is out today and what is still being written
The course is released part by part. This is exactly where it stands, counted from the published lessons.
Which parts are out, and which are still being written?
Part 1 (all 9 lessons), Part 2 (9 of 10), Part 3 (all 16) and Part 4 (all 7) are out today. Parts 5 to 8 are still being written. For running your own LLM, the lessons still being written include "Your first SGLang server", "llama.cpp, GGUF and Ollama", "Tensor parallelism", "vLLM on Kubernetes" and "Watching a model server".
14 reference lessons are already out beside them, and they explain every vLLM 0.33 setting one by one, including quantization, splitting a model across GPUs, the API server and its security, and logs and metrics.
4. Trying it and buying it
How to check the course yourself before you pay.
Can I try it before I pay?
Yes. 4 lessons are free: "Introduction: what this course builds", "Before you start", "Prefill and decode" and "The KV cache". "Before you start" has you rent a GPU, run a model on it and switch it off, so you see exactly how the labs work before you decide. You pay RunPod for that GPU time yourself, with credit you add in advance.
How does buying work?
You pay once and keep the course for life, including every lesson added later, so the parts still being written are included in what you pay today. There is no subscription. The price for your country is in the box on this page and on the course page.
Full walkthrough: The course page, with the price for your country
Where to go next
Every number on this page comes from Hands-On Inference Engineering: Serve LLMs on GPUs with vLLM and SGLang, where you rent the GPU yourself, run each command and compare your numbers with ours. Start with the free introduction and the free lessons on prefill and decode and the KV cache. If you are also preparing for interviews, the two big courses together and the Inference Engineering interview pack are below.

These questions are a start. The interview asks more.
Get all 120 questions in the Inference Engineering pack
Each question has why it is asked, a full answer, what the interviewer listens for, the follow-ups, the common mistakes and a diagram (141 diagrams in all). A PDF you keep, junior to staff level.
Pay by UPI, cards or netbanking through Razorpay. Pay by card or PayPal, in US dollars. Download at once from My packs.