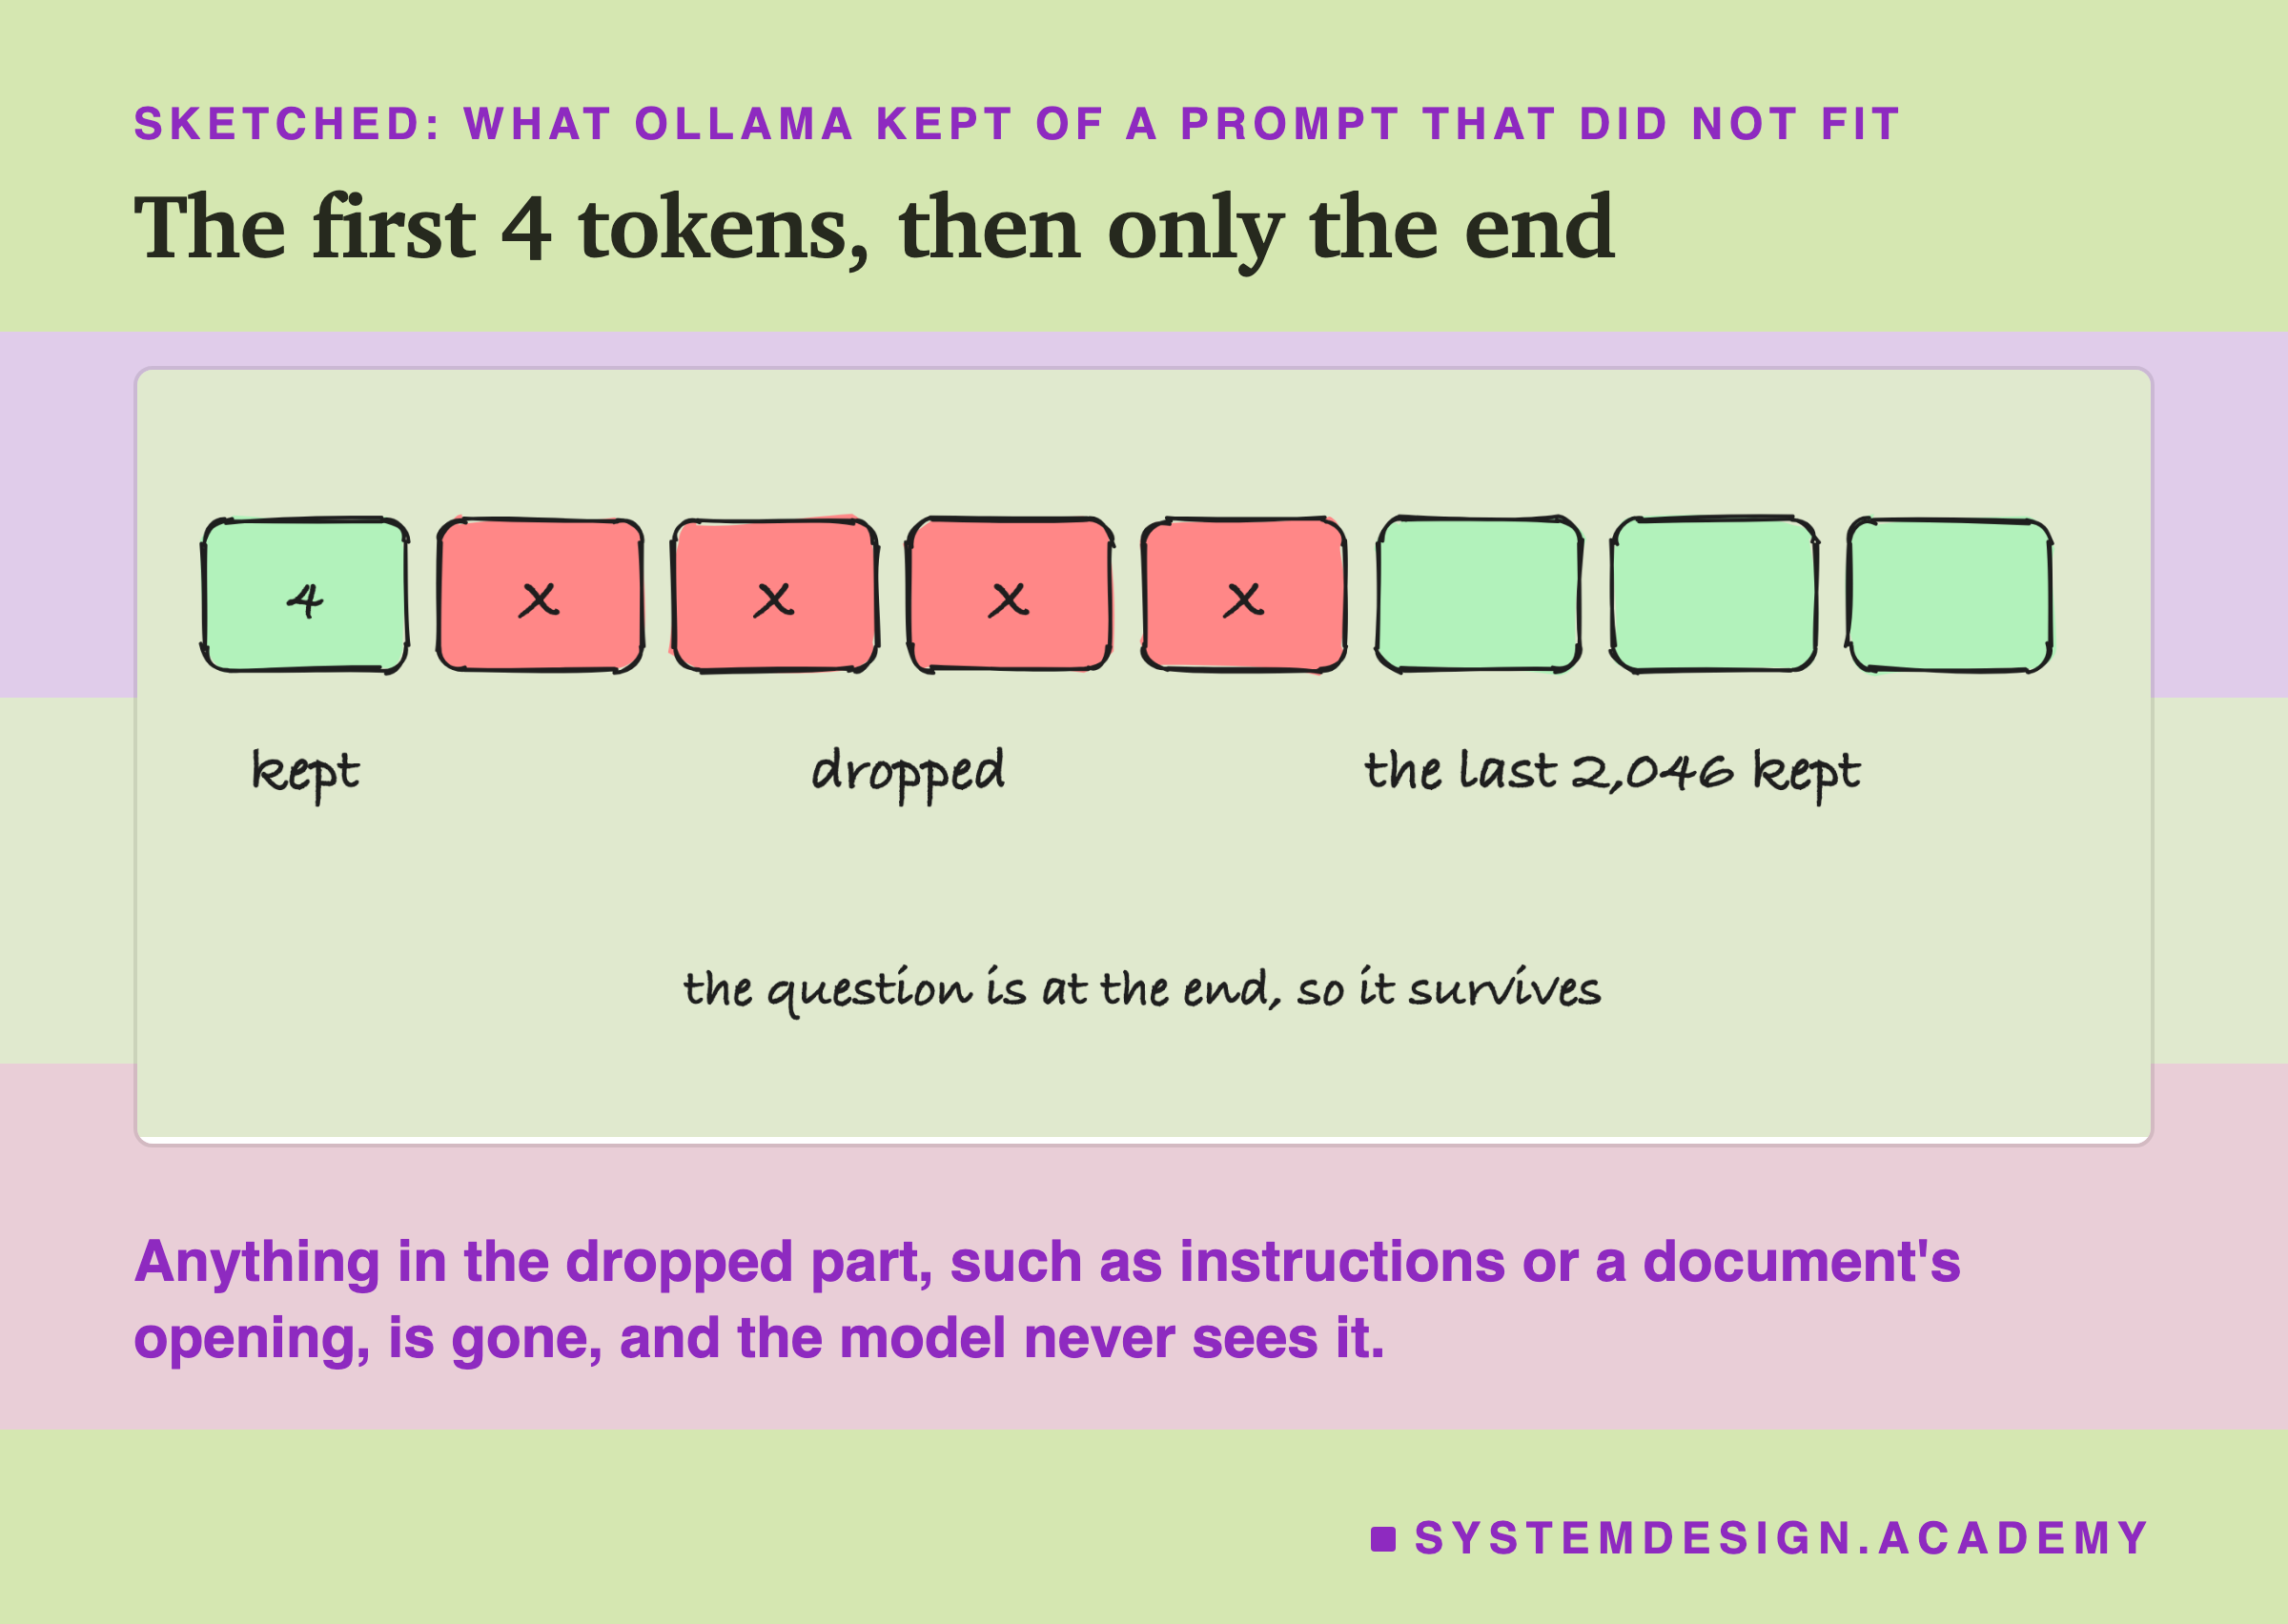
A server has only a few choices. It can refuse the request with an error. It can make the window bigger. Or it can cut the prompt down and carry on. Cutting a prompt to fit is called truncation. You cannot tell which one happened from the reply's text alone.
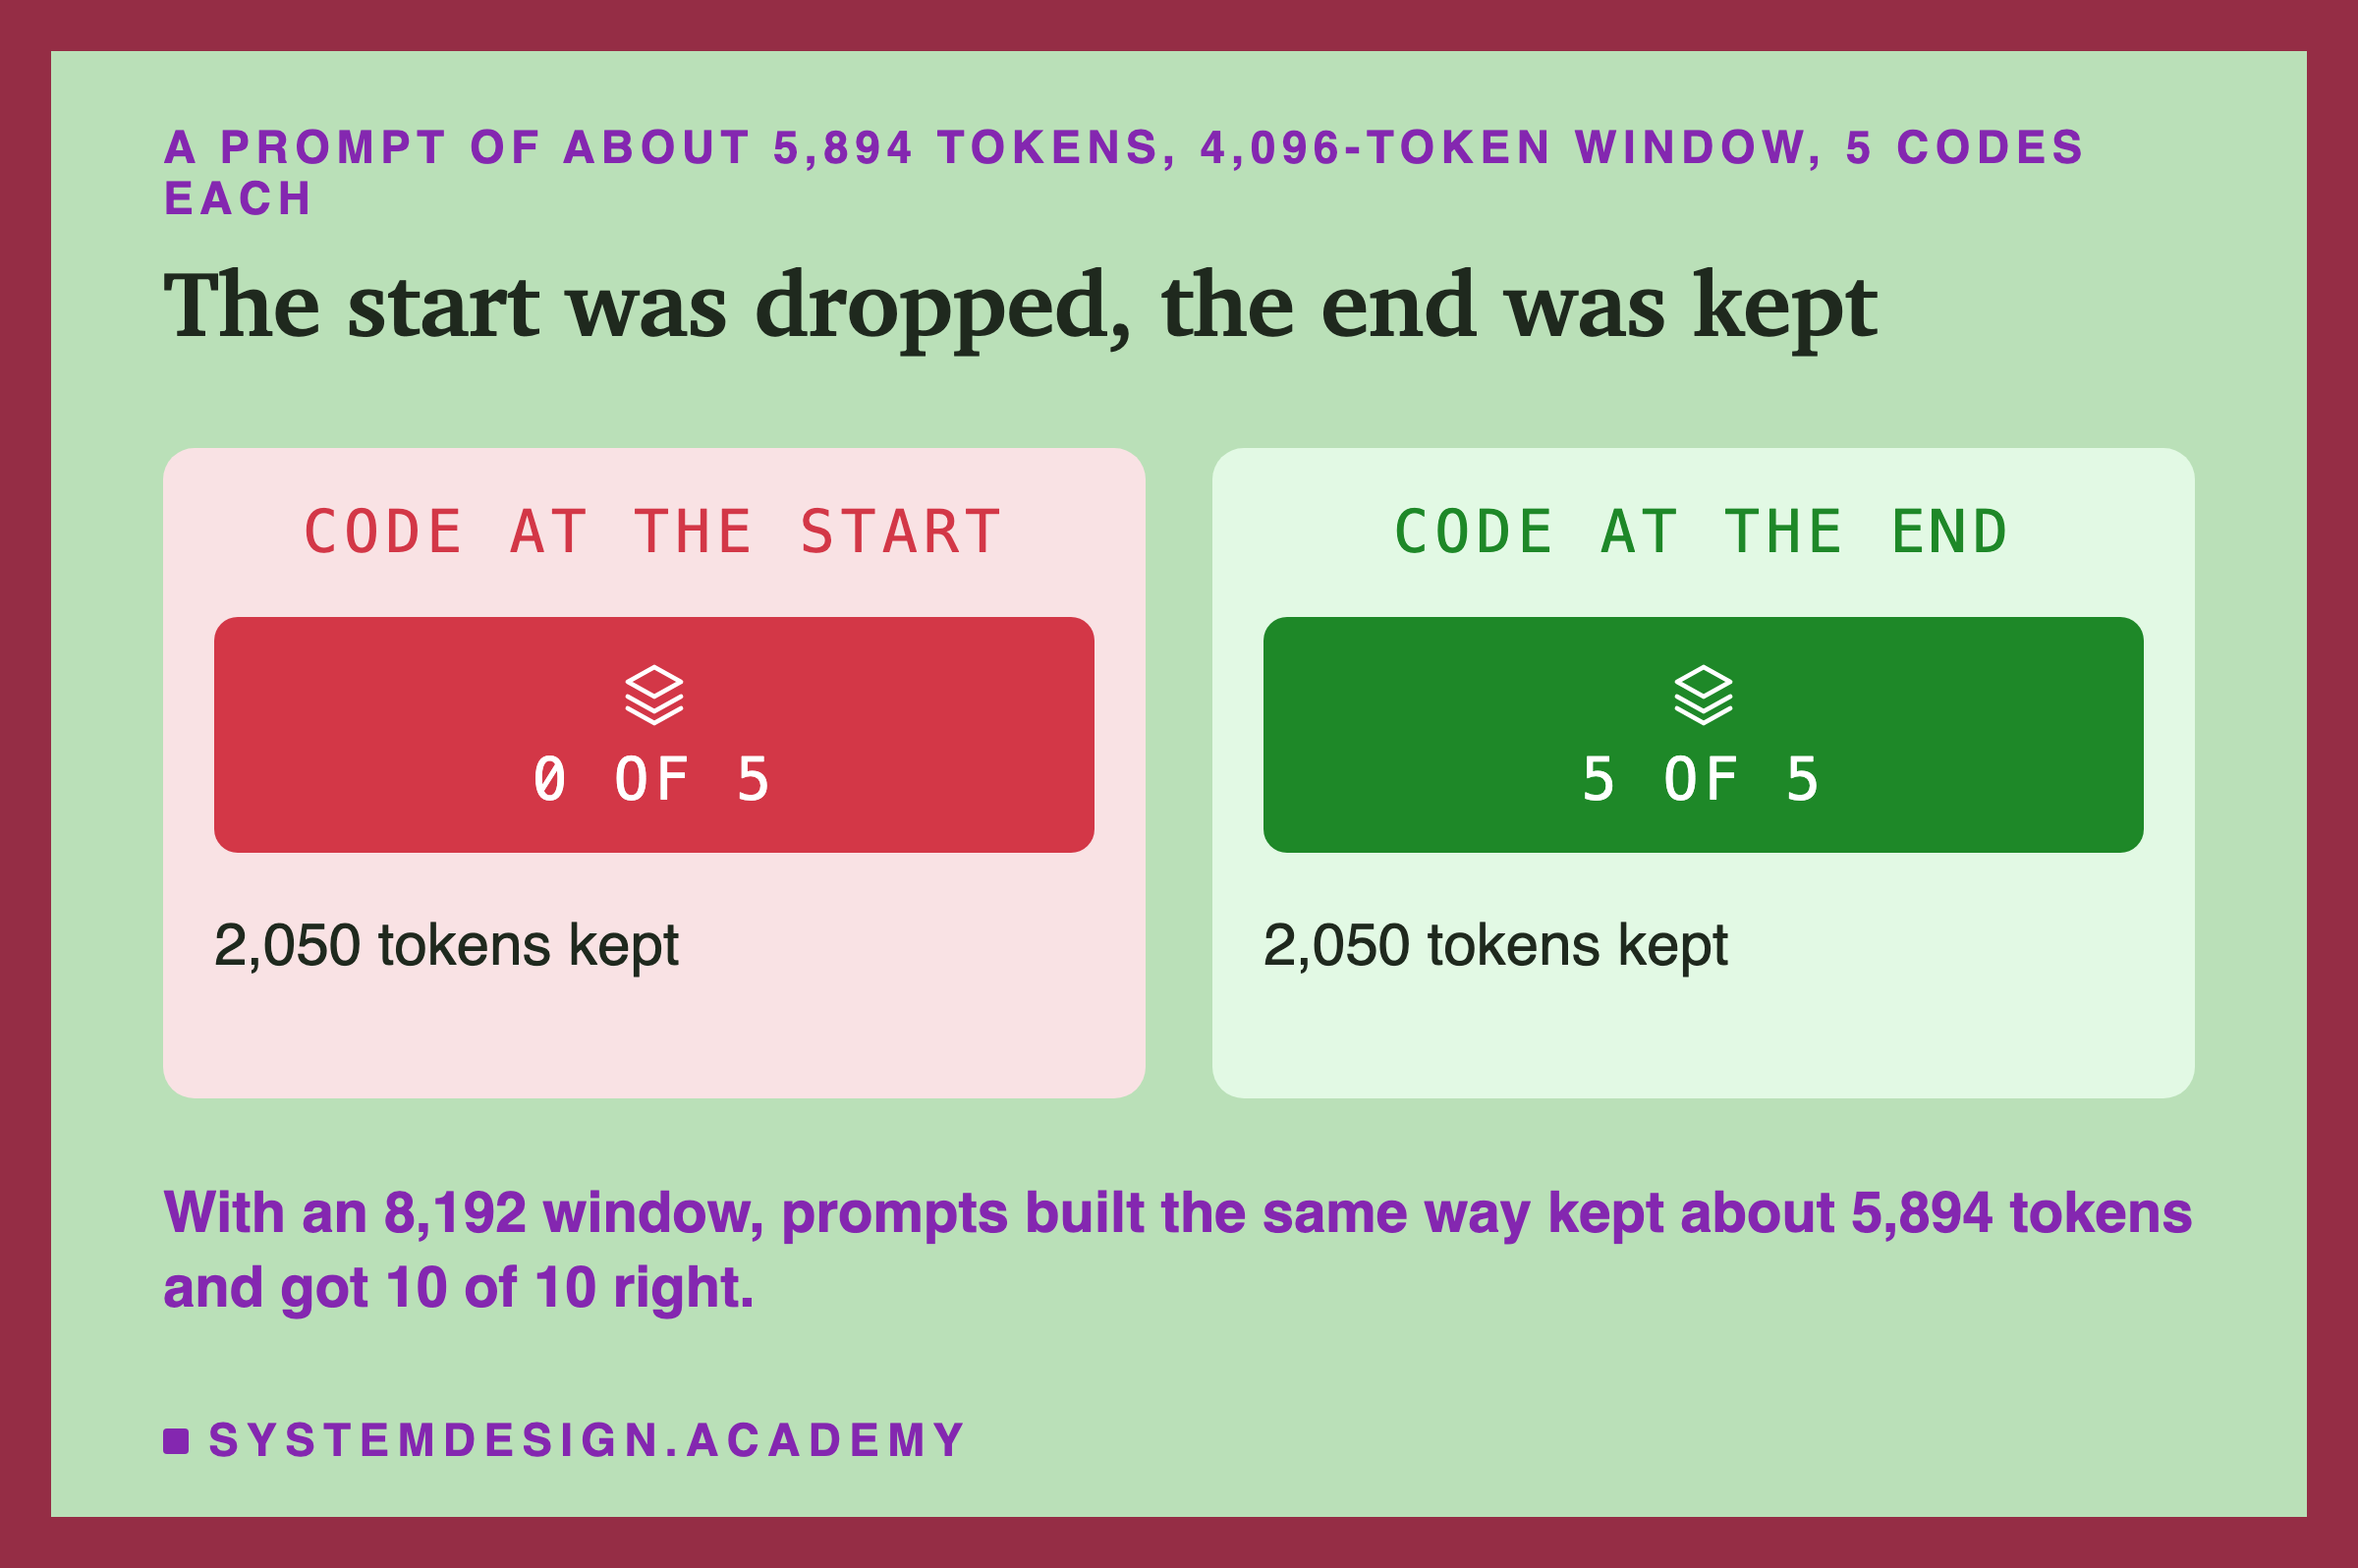
The lesson measured what one popular local server, Ollama, does. It built a prompt of about 5,894 tokens and sent it to a small model, qwen2.5:3b, with a window of 4,096 tokens. Ollama's setting for the window size is called num_ctx.
The reply came back normally. There was no error and no warning in it. But the count of prompt tokens the model read, a field called prompt_eval_count, was 2,050. About 3,844 tokens, roughly 65% of the prompt, were never read.
Two things are surprising here. First, the cut was silent. Second, the prompt was cut to far less than the window. The window had room for 4,096 tokens, and only about half of it was used.